# Agent UI
Source: https://docs.phidata.com/agent-ui
Phidata provides a beautiful Agent UI for interacting with your agents.
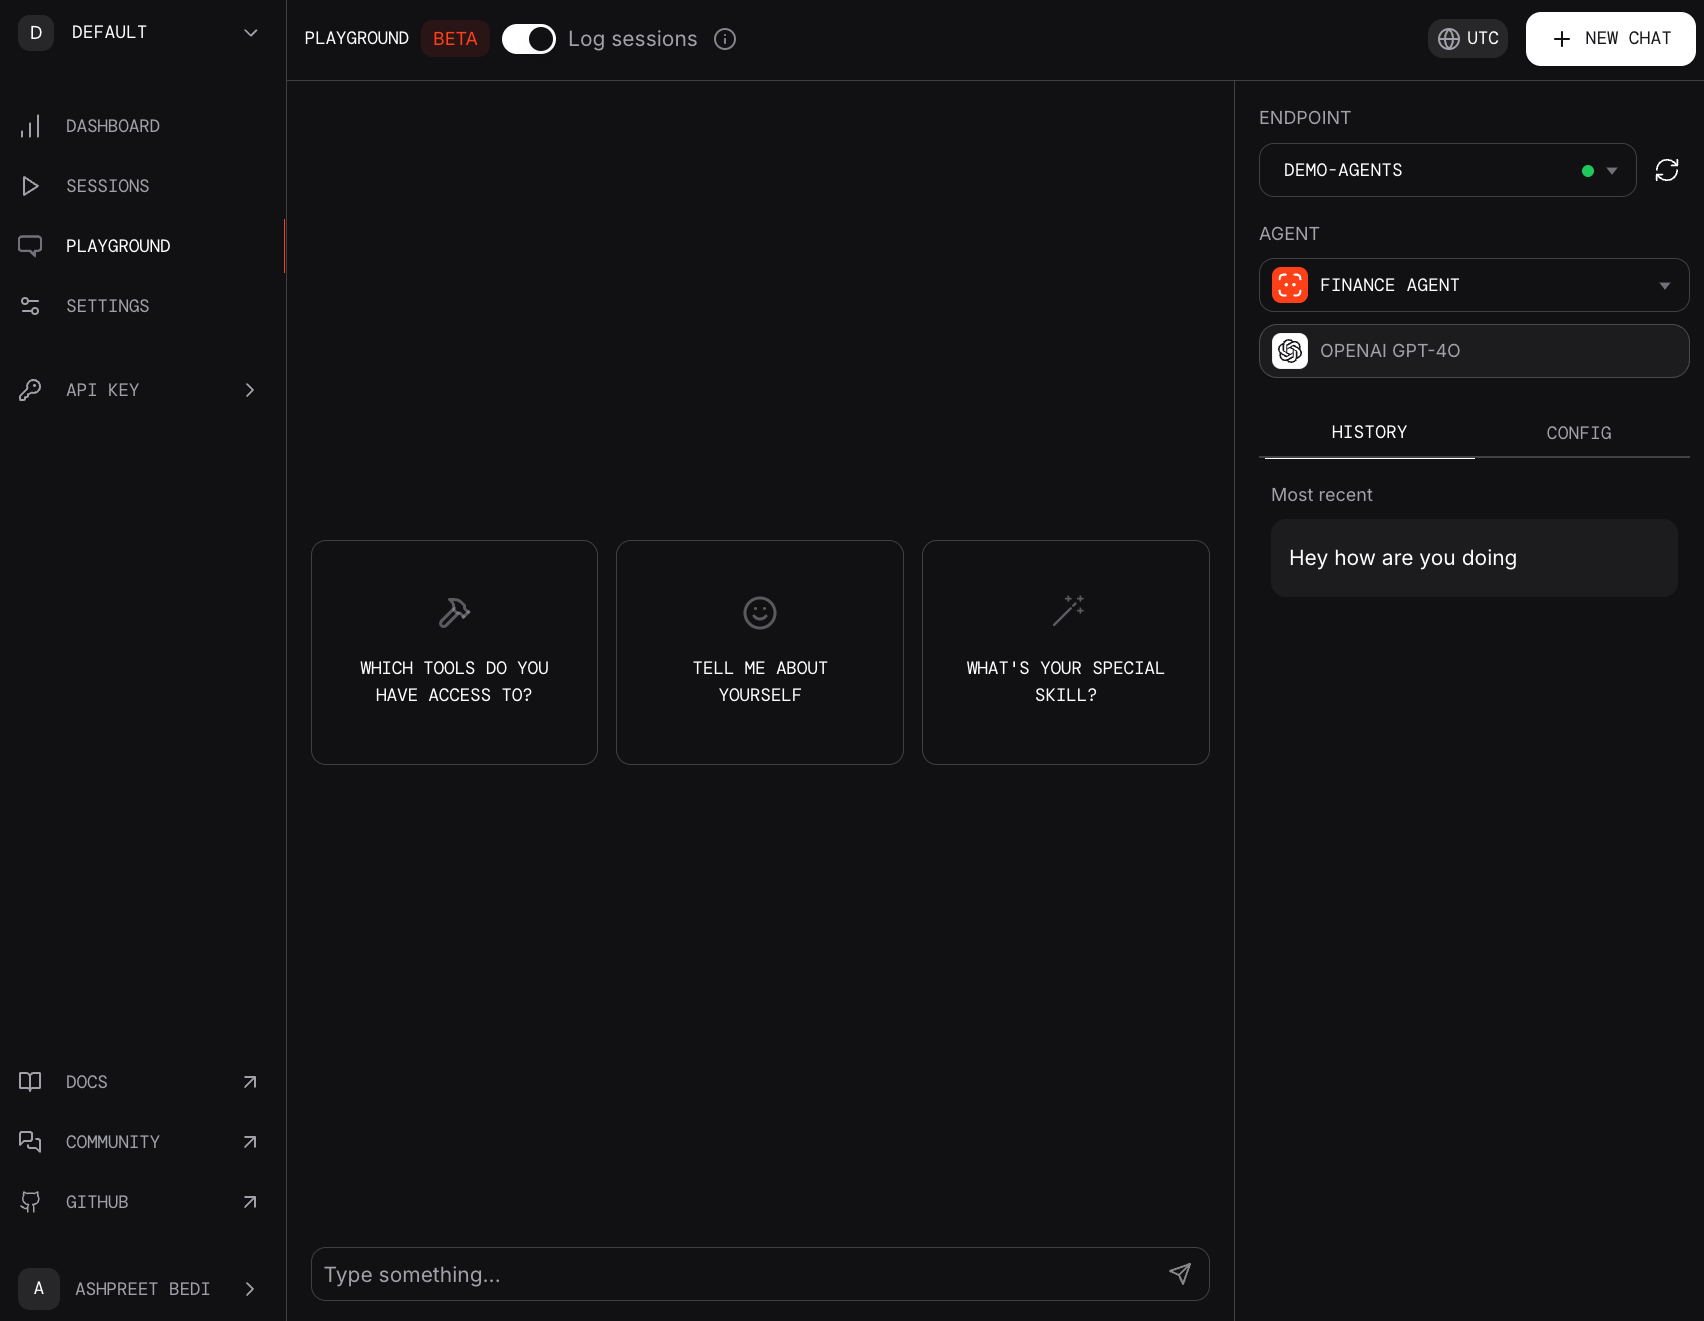 No data is sent to phidata, all agent sessions are stored locally in a sqlite
database.
Let's take it for a spin, create a file `playground.py`
```python playground.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.storage.agent.sqlite import SqlAgentStorage
from phi.tools.duckduckgo import DuckDuckGo
from phi.playground import Playground, serve_playground_app
web_agent = Agent(
name="Web Agent",
model=OpenAIChat(id="gpt-4o"),
tools=[DuckDuckGo()],
instructions=["Always include sources"],
storage=SqlAgentStorage(table_name="web_agent", db_file="agents.db"),
add_history_to_messages=True,
markdown=True,
)
finance_agent = Agent(
name="Finance Agent",
model=OpenAIChat(id="gpt-4o"),
instructions=["Use tables to display data"],
storage=SqlAgentStorage(table_name="finance_agent", db_file="agents.db"),
add_history_to_messages=True,
markdown=True,
)
app = Playground(agents=[finance_agent, web_agent]).get_app()
if __name__ == "__main__":
serve_playground_app("playground:app", reload=True)
```
Make sure the `serve_playground_app()` points to the file that contains your
`Playground` app.
### Run the playground
Install dependencies and run the Agent Playground:
```shell
pip install 'fastapi[standard]' sqlalchemy
python playground.py
```
### View the playground
* Open the link provided or navigate to `http://phidata.app/playground` (login required)
* Select the `localhost:7777` endpoint and start chatting with your agents!
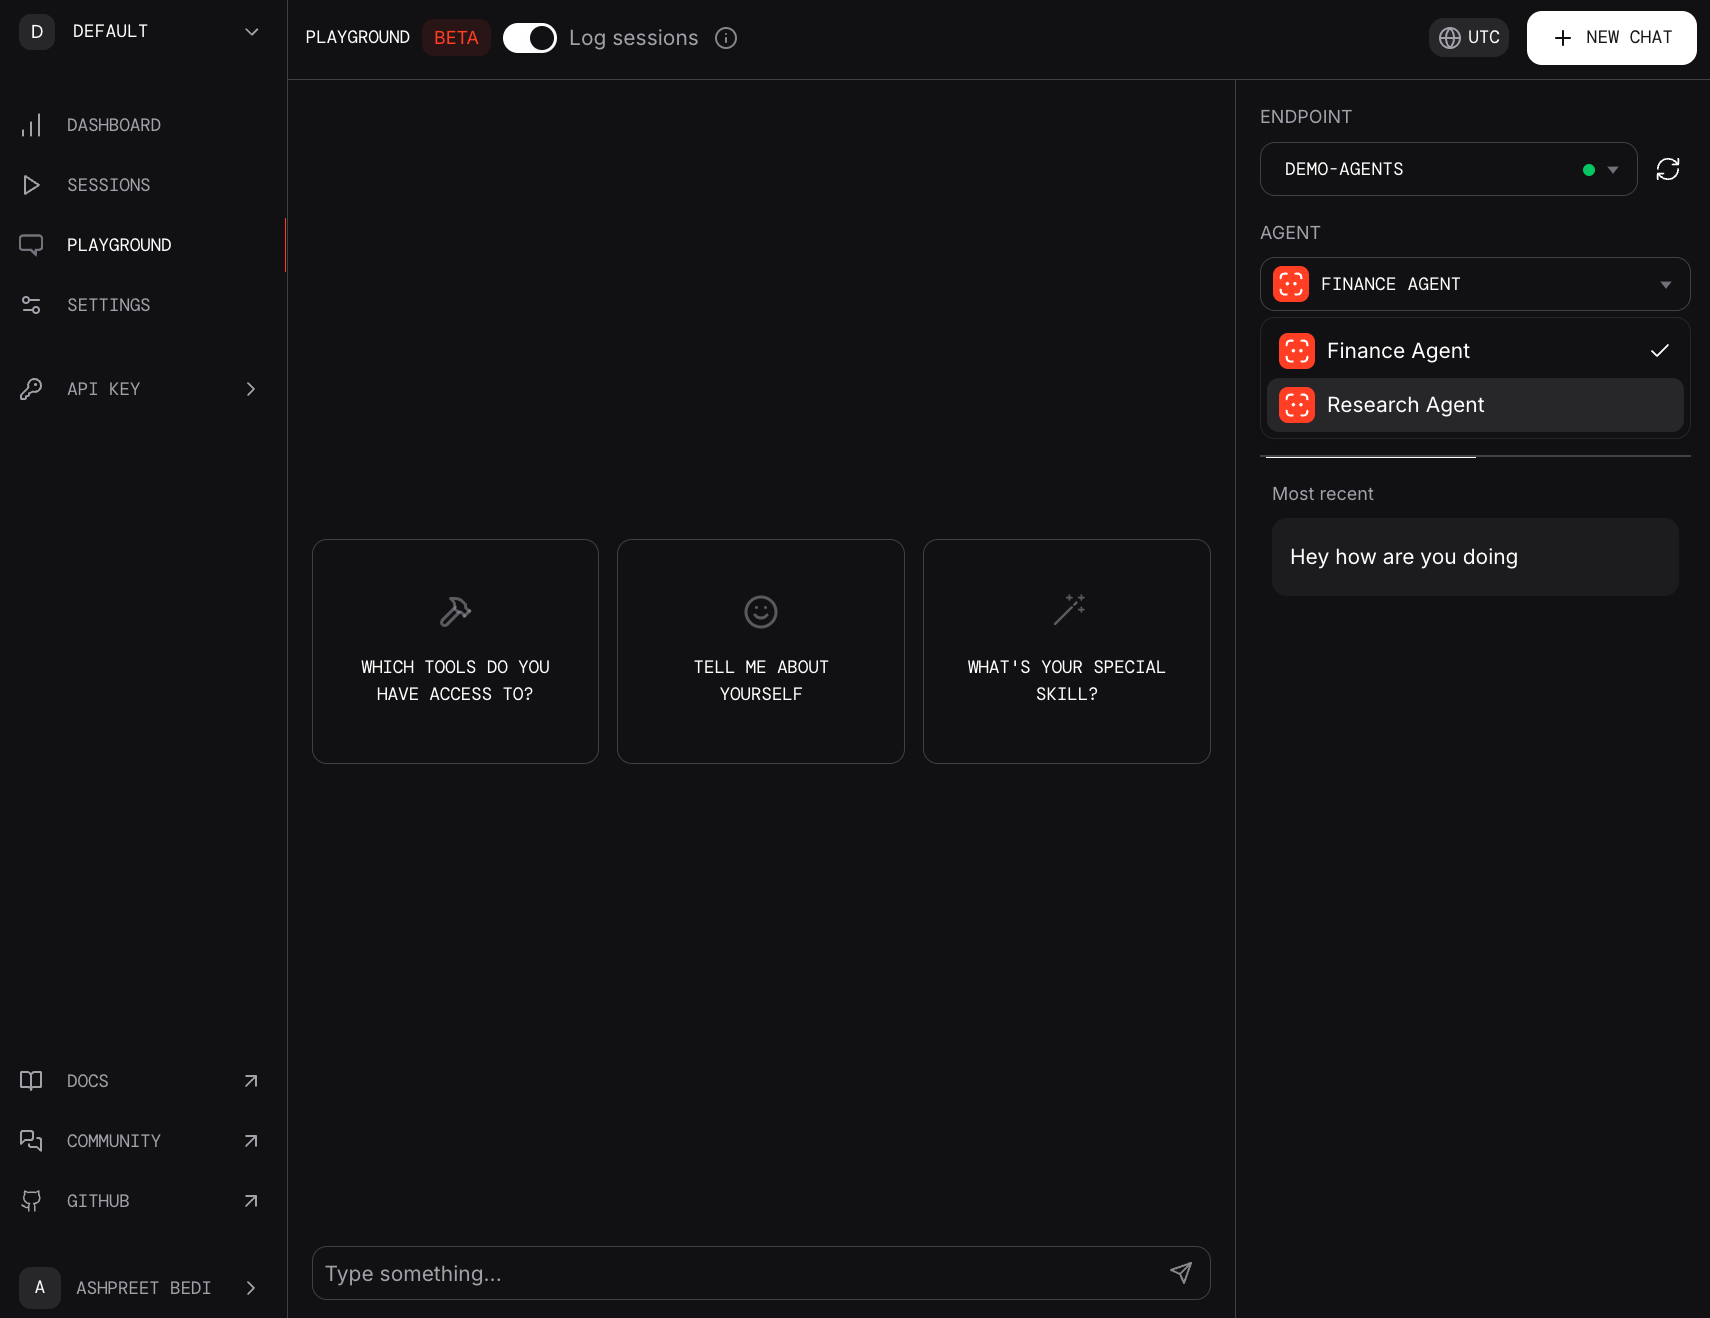
## Demo Agents
The Agent Playground includes a few demo agents that you can test with. If you have recommendations for other agents we should build, please let us know in the [community forum](https://community.phidata.com/).
 # Introduction
Source: https://docs.phidata.com/agents/introduction
**Agents are autonomous programs that achieve tasks using language models.**
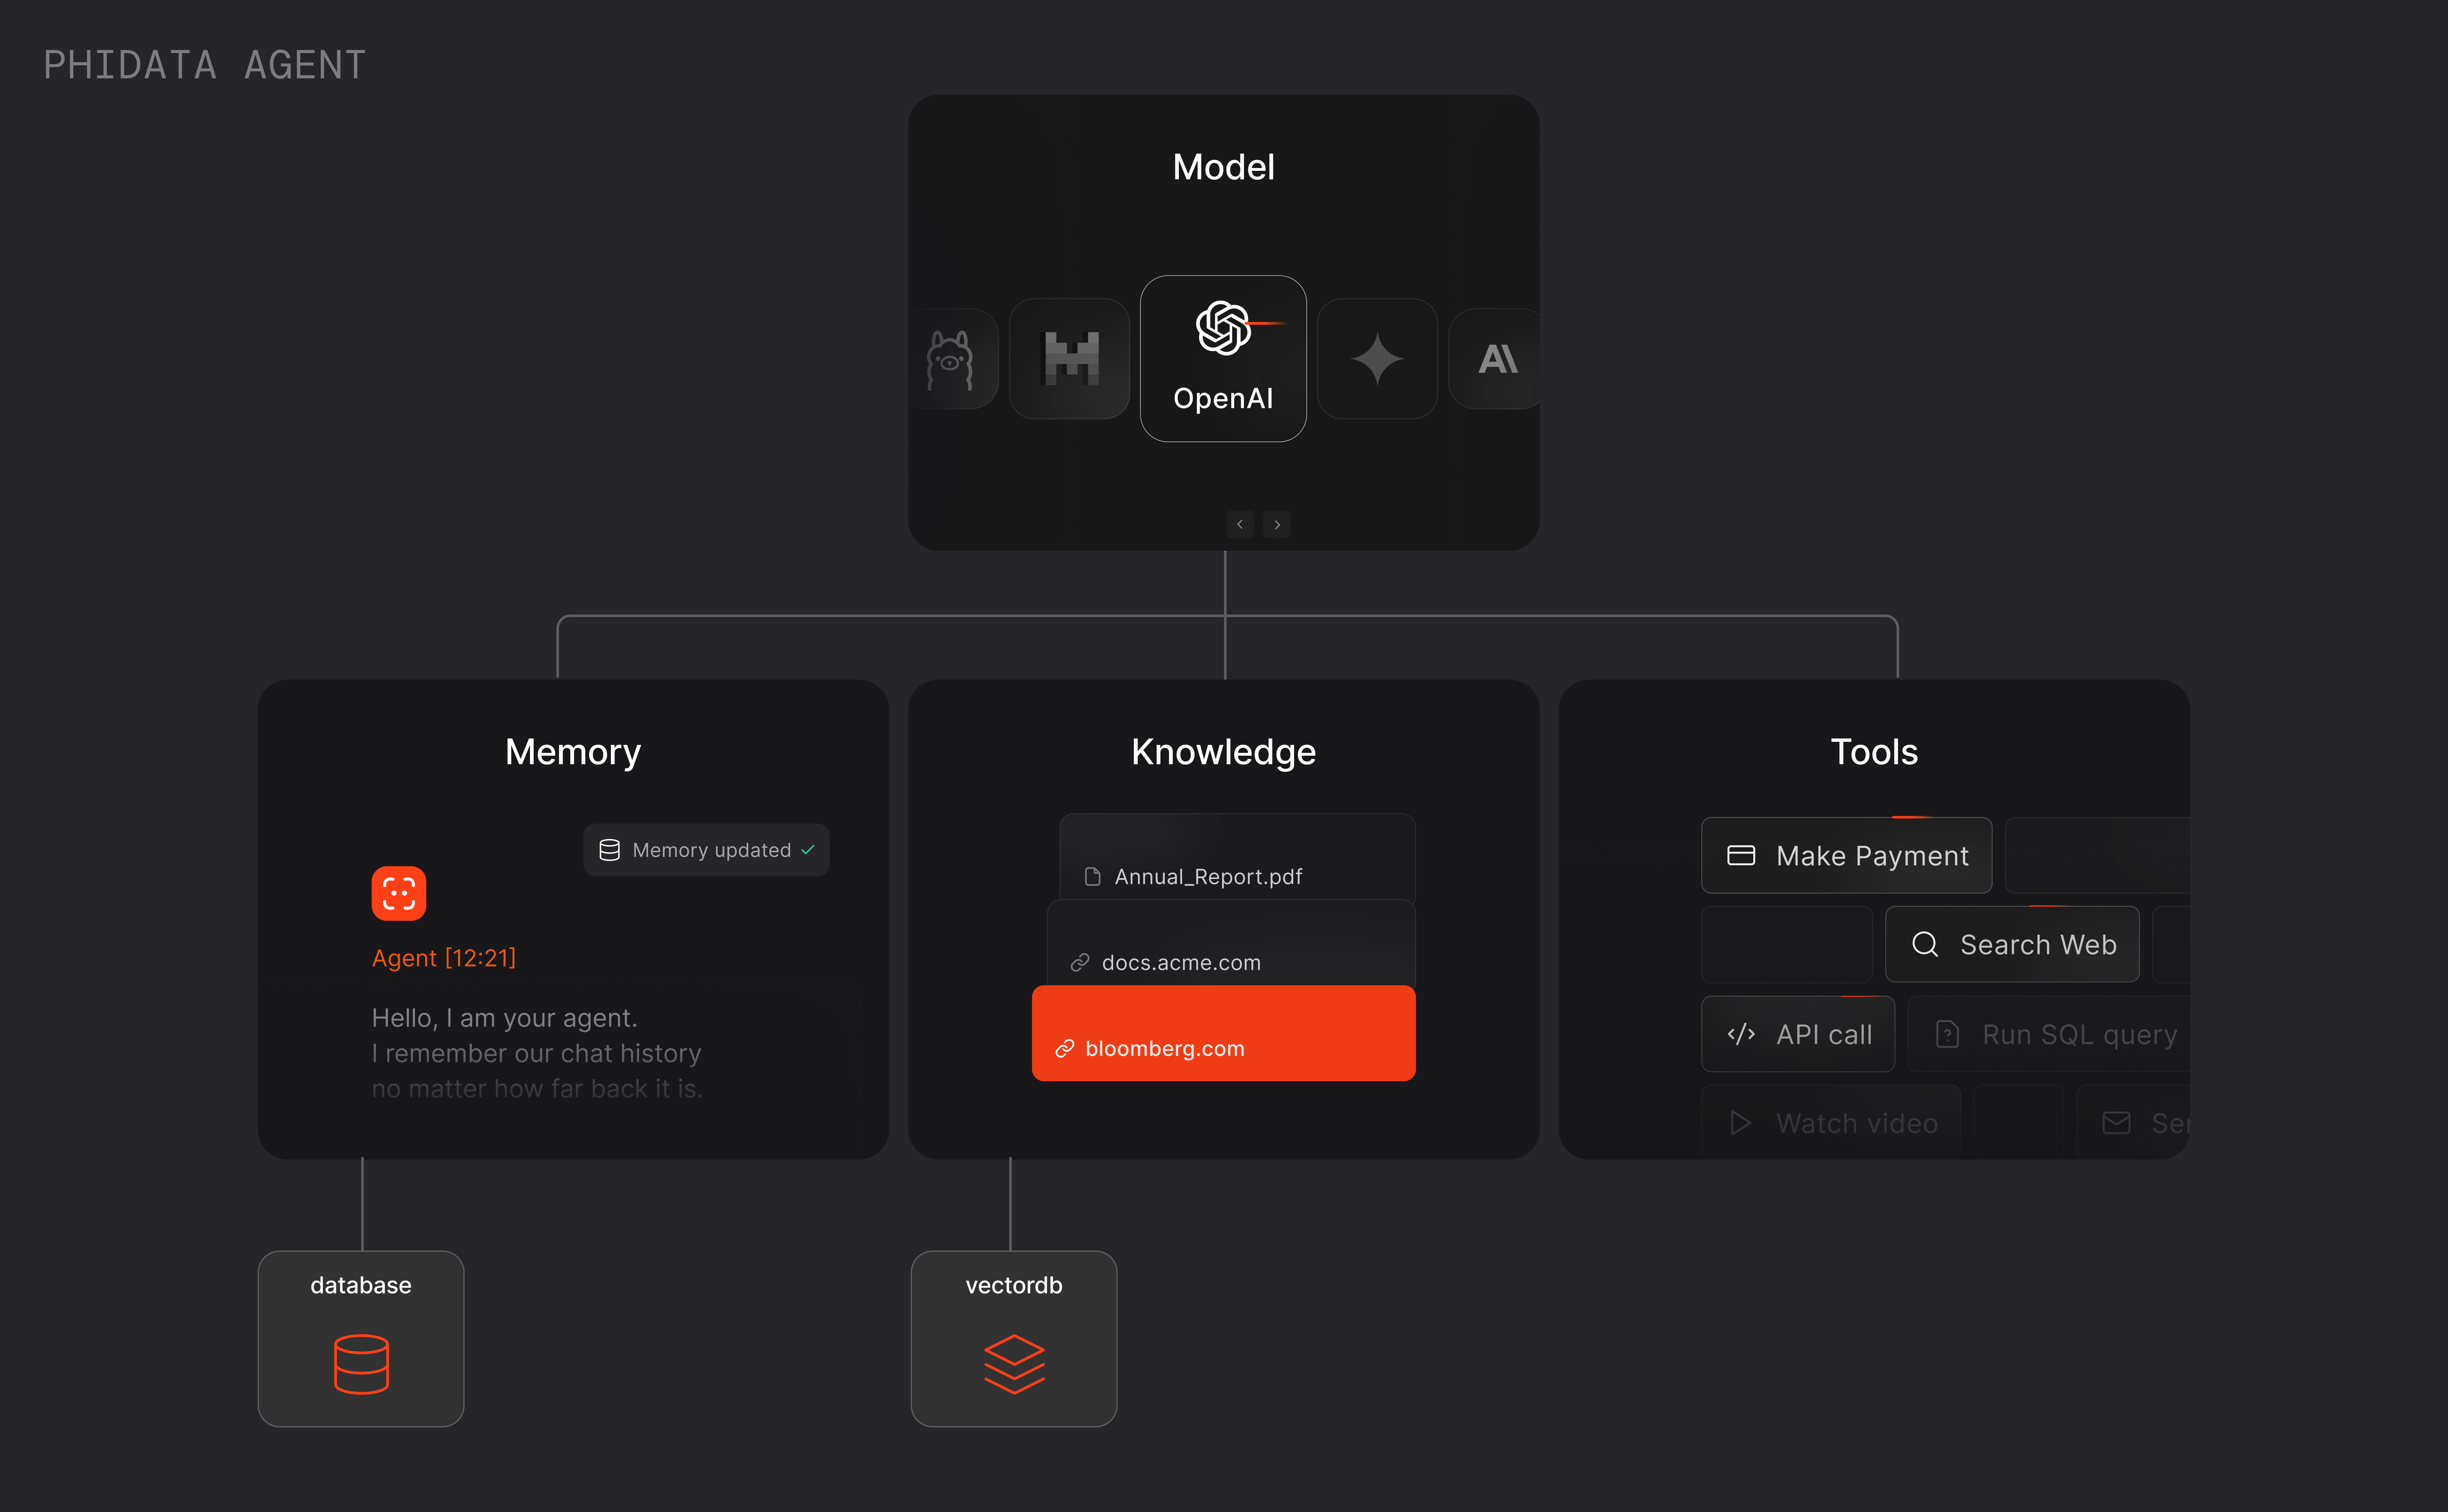
Engineers use phidata to build agents with memory, knowledge, tools and reasoning.
 ## Example: Research Agent
Let's create a research agent that can search the web, read the top links and write a report for us. We **"prompt"** the agent using `description` and `instructions`.
Create a file `research_agent.py`
```python research_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.duckduckgo import DuckDuckGo
from phi.tools.newspaper4k import Newspaper4k
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
tools=[DuckDuckGo(), Newspaper4k()],
description="You are a senior NYT researcher writing an article on a topic.",
instructions=[
"For a given topic, search for the top 5 links.",
"Then read each URL and extract the article text, if a URL isn't available, ignore it.",
"Analyse and prepare an NYT worthy article based on the information.",
],
markdown=True,
show_tool_calls=True,
add_datetime_to_instructions=True,
# debug_mode=True,
)
agent.print_response("Simulation theory", stream=True)
```
Install libraries
```shell
pip install phidata openai duckduckgo-search newspaper4k lxml_html_clean
```
Run the agent
```shell
python research_agent.py
```
The description and instructions are converted to the system prompt and the input (e.g. `Simulation theory`) is passed as the user prompt.
Use `debug_mode=True` to view the raw logs behind the scenes.
## Capturing the Agent's response in a variable
While `Agent.print_response()` is useful for quick experiments, we typically want to capture the agent's response in a variable to either pass to the frontend, another agent or use in our application. The `Agent.run()` function returns the response as a `RunResponse` object.
```python
from phi.agent import Agent, RunResponse
from phi.utils.pprint import pprint_run_response
agent = Agent(...)
# Run agent and return the response as a variable
response: RunResponse = agent.run("Simulation theory")
# Print the response in markdown format
pprint_run_response(response, markdown=True)
```
By default `stream=False`, set `stream=True` to return a stream of `RunResponse` objects.
```python
from typing import Iterator
# Run agent and return the response as a stream
response_stream: Iterator[RunResponse] = agent.run("Simulation theory", stream=True)
# Print the response stream in markdown format
pprint_run_response(response_stream, markdown=True, show_time=True)
```
## RunResponse
The `Agent.run()` function returns either a `RunResponse` object or an `Iterator[RunResponse]` when `stream=True`.
### RunResponse Attributes
| Attribute | Type | Default | Description |
| -------------- | ---------------------- | ----------------------------- | -------------------------------------------- |
| `content` | `Any` | `None` | Content of the response. |
| `content_type` | `str` | `"str"` | Specifies the data type of the content. |
| `context` | `List[MessageContext]` | `None` | The context added to the response for RAG. |
| `event` | `str` | `RunEvent.run_response.value` | Event type of the response. |
| `event_data` | `Dict[str, Any]` | `None` | Data associated with the event. |
| `messages` | `List[Message]` | `None` | A list of messages included in the response. |
| `metrics` | `Dict[str, Any]` | `None` | Usage metrics of the run. |
| `model` | `Model` | `OpenAIChat` | OpenAI model is used to run by default. |
| `run_id` | `str` | `None` | Run Id. |
| `agent_id` | `str` | `None` | Agent Id for the run. |
| `session_id` | `str` | `None` | Session Id for the run. |
| `tools` | `List[Dict[str, Any]]` | `None` | List of tools provided to the model. |
| `created_at` | `int` | - | Unix timestamp of the response creation. |
# Knowledge
Source: https://docs.phidata.com/agents/knowledge
**Agents use knowledge to supplement their training data with domain expertise**.
Knowledge is stored in a vector database and provides agents with business context at query time, helping them respond in a context-aware manner. The general syntax is:
```python
from phi.agent import Agent, AgentKnowledge
# Create a knowledge base for the Agent
knowledge_base = AgentKnowledge(vector_db=...)
# Add information to the knowledge base
knowledge_base.load_text("The sky is blue")
# Add the knowledge base to the Agent and
# give it a tool to search the knowledge base as needed
agent = Agent(knowledge=knowledge_base, search_knowledge=True)
```
## Vector Databases
While any type of storage can act as a knowledge base, vector databases offer the best solution for retrieving relevant results from dense information quickly. Here's how vector databases are used with Agents:
Break down the knowledge into smaller chunks to ensure our search query
returns only relevant results.
Convert the chunks into embedding vectors and store them in a vector
database.
When the user sends a message, we convert the input message into an
embedding and "search" for nearest neighbors in the vector database.
## Example: RAG Agent with a PDF Knowledge Base
Let's build a **RAG Agent** that answers questions from a PDF.
### Step 1: Run PgVector
Let's use `PgVector` as our vector db as it can also provide storage for our Agents.
Install [docker desktop](https://docs.docker.com/desktop/install/mac-install/) and run **PgVector** on port **5532** using:
```bash
docker run -d \
-e POSTGRES_DB=ai \
-e POSTGRES_USER=ai \
-e POSTGRES_PASSWORD=ai \
-e PGDATA=/var/lib/postgresql/data/pgdata \
-v pgvolume:/var/lib/postgresql/data \
-p 5532:5432 \
--name pgvector \
phidata/pgvector:16
```
### Step 2: Traditional RAG
Retrieval Augmented Generation (RAG) means **"stuffing the prompt with relevant information"** to improve the model's response. This is a 2 step process:
1. Retrieve relevant information from the knowledge base.
2. Augment the prompt to provide context to the model.
Let's build a **traditional RAG** Agent that answers questions from a PDF of recipes.
Install the required libraries using pip
```bash Mac
pip install -U pgvector pypdf "psycopg[binary]" sqlalchemy
```
```bash Windows
pip install -U pgvector pypdf "psycopg[binary]" sqlalchemy
```
Create a file `traditional_rag.py` with the following contents
```python traditional_rag.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector, SearchType
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
# Read PDF from this URL
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
# Store embeddings in the `ai.recipes` table
vector_db=PgVector(table_name="recipes", db_url=db_url, search_type=SearchType.hybrid),
)
# Load the knowledge base: Comment after first run
knowledge_base.load(upsert=True)
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
knowledge=knowledge_base,
# Enable RAG by adding references from AgentKnowledge to the user prompt.
add_context=True,
# Set as False because Agents default to `search_knowledge=True`
search_knowledge=False,
markdown=True,
# debug_mode=True,
)
agent.print_response("How do I make chicken and galangal in coconut milk soup")
```
Run the agent (it takes a few seconds to load the knowledge base).
```bash Mac
python traditional_rag.py
```
```bash Windows
python traditional_rag.py
```
If you want to use local PDFs, use a `PDFKnowledgeBase` instead
```python agent.py
from phi.knowledge.pdf import PDFKnowledgeBase
...
knowledge_base = PDFKnowledgeBase(
path="data/pdfs",
vector_db=PgVector(
table_name="pdf_documents",
db_url=db_url,
),
)
...
```
### Step 3: Agentic RAG
With traditional RAG above, `add_context=True` always adds information from the knowledge base to the prompt, regardless of whether it is relevant to the question or helpful.
With Agentic RAG, we let the Agent decide **if** it needs to access the knowledge base and what search parameters it needs to query the knowledge base.
Set `search_knowledge=True` and `read_chat_history=True`, giving the Agent tools to search its knowledge and chat history on demand.
Create a file `agentic_rag.py` with the following contents
```python agentic_rag.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector, SearchType
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector(table_name="recipes", db_url=db_url, search_type=SearchType.hybrid),
)
# Load the knowledge base: Comment out after first run
knowledge_base.load(upsert=True)
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
knowledge=knowledge_base,
# Add a tool to search the knowledge base which enables agentic RAG.
search_knowledge=True,
# Add a tool to read chat history.
read_chat_history=True,
show_tool_calls=True,
markdown=True,
# debug_mode=True,
)
agent.print_response("How do I make chicken and galangal in coconut milk soup", stream=True)
agent.print_response("What was my last question?", markdown=True)
```
Run the agent
```bash Mac
python agentic_rag.py
```
```bash Windows
python agentic_rag.py
```
Notice how it searches the knowledge base and chat history when needed
## Attributes
| Parameter | Type | Default | Description |
| -------------------------- | ------------------------------------- | ------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `knowledge` | `AgentKnowledge` | `None` | Provides the knowledge base used by the agent. |
| `search_knowledge` | `bool` | `True` | Adds a tool that allows the Model to search the knowledge base (aka Agentic RAG). Enabled by default when `knowledge` is provided. |
| `add_context` | `bool` | `False` | Enable RAG by adding references from AgentKnowledge to the user prompt. |
| `retriever` | `Callable[..., Optional[list[dict]]]` | `None` | Function to get context to add to the user message. This function is called when add\_context is True. |
| `context_format` | `Literal['json', 'yaml']` | `json` | Specifies the format for RAG, either "json" or "yaml". |
| `add_context_instructions` | `bool` | `False` | If True, add instructions for using the context to the system prompt (if knowledge is also provided). For example: add an instruction to prefer information from the knowledge base over its training data. |
# Memory
Source: https://docs.phidata.com/agents/memory
Phidata provides 3 types of memories for building a great Agent experience (AX):
1. **Chat History:** previous messages from the conversation, we recommend sending the last 3-5 messages to the model.
2. **User Memories:** notes and insights about the user, this helps the model personalize the response to the user.
3. **Summaries:** a summary of the conversation, which is added to the prompt when chat history gets too long.
Before we dive in, let's understand the terminology:
* **Session:** Each conversation with an Agent is called a **session**. Sessions are identified by a `session_id`.
* **Run:** Every interaction (i.e. chat) within a session is called a **run**. Runs are identified by a `run_id`.
* **Messages:** are the individual messages sent to and received from the model. They have a `role` (`system`, `user` or `assistant`) and `content`.
**Sessions** are equivalent to **threads** in the OpenAI Assistant API.
## Built-in Memory
Every Agent comes with built-in memory that can be used to access the historical **runs** and **messages**. Access it using `agent.memory`
The list of runs between the user and agent. Each run contains the input message and output response.
The full list of messages sent to the model, including system prompt, tool calls etc.
### Example
```python agent_memory.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from rich.pretty import pprint
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
# Set add_history_to_messages=true to add the previous chat history to the messages sent to the Model.
add_history_to_messages=True,
# Number of historical responses to add to the messages.
num_history_responses=3,
description="You are a helpful assistant that always responds in a polite, upbeat and positive manner.",
)
# -*- Create a run
agent.print_response("Share a 2 sentence horror story", stream=True)
# -*- Print the messages in the memory
pprint([m.model_dump(include={"role", "content"}) for m in agent.memory.messages])
# -*- Ask a follow up question that continues the conversation
agent.print_response("What was my first message?", stream=True)
# -*- Print the messages in the memory
pprint([m.model_dump(include={"role", "content"}) for m in agent.memory.messages])
```
## Persistent Memory
The built-in memory only lasts while the session is active. To persist memory across sessions, we can store Agent sessions in a database using `AgentStorage`.
Storage is a necessary component when building user facing AI products as any production application will require users to be able to "continue" their conversation with the Agent.
Let's test this out, create a file `persistent_memory.py` with the following code:
```python persistent_memory.py
import json
from rich.console import Console
from rich.panel import Panel
from rich.json import JSON
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.storage.agent.sqlite import SqlAgentStorage
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
# Store agent sessions in a database
storage=SqlAgentStorage(table_name="agent_sessions", db_file="tmp/agent_storage.db"),
# Set add_history_to_messages=true to add the previous chat history to the messages sent to the Model.
add_history_to_messages=True,
# Number of historical responses to add to the messages.
num_history_responses=3,
# The session_id is used to identify the session in the database
# You can resume any session by providing a session_id
# session_id="xxxx-xxxx-xxxx-xxxx",
# Description creates a system prompt for the agent
description="You are a helpful assistant that always responds in a polite, upbeat and positive manner.",
)
console = Console()
def print_chat_history(agent):
# -*- Print history
console.print(
Panel(
JSON(json.dumps([m.model_dump(include={"role", "content"}) for m in agent.memory.messages]), indent=4),
title=f"Chat History for session_id: {agent.session_id}",
expand=True,
)
)
# -*- Create a run
agent.print_response("Share a 2 sentence horror story", stream=True)
# -*- Print the chat history
print_chat_history(agent)
# -*- Ask a follow up question that continues the conversation
agent.print_response("What was my first message?", stream=True)
# -*- Print the chat history
print_chat_history(agent)
```
### Run the agent
Install dependencies and run the agent:
```shell
pip install openai sqlalchemy phidata
python persistent_memory.py
```
You can view the agent sessions in the sqlite database and continue any conversation by providing the same `session_id`.
Read more in the [storage](/agents/storage) section.
## User preferences and conversation summaries
Along with storing chat history and run messages, `AgentMemory` can be extended to automatically classify and store user preferences and conversation summaries.
To do this, add a `db` to `AgentMemory` and set `create_user_memories=True` and `create_session_summary=True`
User memories are stored in the `AgentMemory` whereas session summaries are stored in the `AgentStorage` table with the rest of the session information.
User preferences and conversation summaries are currently only compatible with
`OpenAI` and `OpenAILike` models. While Persistent Memory is compatible with
all model providers.
## Example
```python personalized_memories_and_summaries.py
from rich.pretty import pprint
from phi.agent import Agent, AgentMemory
from phi.model.openai import OpenAIChat
from phi.memory.db.postgres import PgMemoryDb
from phi.storage.agent.postgres import PgAgentStorage
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
# Store the memories and summary in a database
memory=AgentMemory(
db=PgMemoryDb(table_name="agent_memory", db_url=db_url), create_user_memories=True, create_session_summary=True
),
# Store agent sessions in a database
storage=PgAgentStorage(table_name="personalized_agent_sessions", db_url=db_url),
# Show debug logs so you can see the memory being created
# debug_mode=True,
)
# -*- Share personal information
agent.print_response("My name is john billings?", stream=True)
# -*- Print memories
pprint(agent.memory.memories)
# -*- Print summary
pprint(agent.memory.summary)
# -*- Share personal information
agent.print_response("I live in nyc?", stream=True)
# -*- Print memories
pprint(agent.memory.memories)
# -*- Print summary
pprint(agent.memory.summary)
# -*- Share personal information
agent.print_response("I'm going to a concert tomorrow?", stream=True)
# -*- Print memories
pprint(agent.memory.memories)
# -*- Print summary
pprint(agent.memory.summary)
# Ask about the conversation
agent.print_response("What have we been talking about, do you know my name?", stream=True)
```
## Attributes
| Parameter | Type | Default | Description |
| ---------------------------------- | ------------- | --------------- | --------------------------------------------------------------------------------------------------------------- |
| `memory` | `AgentMemory` | `AgentMemory()` | Agent's memory object used for storing and retrieving information. |
| `add_history_to_messages` | `bool` | `False` | If true, adds the chat history to the messages sent to the Model. Also known as `add_chat_history_to_messages`. |
| `num_history_responses` | `int` | `3` | Number of historical responses to add to the messages. |
| `create_user_memories` | `bool` | `False` | If true, create and store personalized memories for the user. |
| `update_user_memories_after_run` | `bool` | `True` | If true, update memories for the user after each run. |
| `create_session_summary` | `bool` | `False` | If true, create and store session summaries. |
| `update_session_summary_after_run` | `bool` | `True` | If true, update session summaries after each run. |
# Prompts
Source: https://docs.phidata.com/agents/prompts
We prompt Agents using `description` and `instructions` and a number of other settings. These settings are used to build the **system** prompt that is sent to the language model.
Understanding how these prompts are created will help you build better Agents.
The 2 key parameters are:
1. **Description**: A description that guides the overall behaviour of the agent.
2. **Instructions**: A list of precise, task-specific instructions on how to achieve its goal.
Description and instructions only provide a formatting benefit, we do not alter or abstract any information and you can always use `system_prompt` to provide your own system prompt.
## System message
The system message is created using `description`, `instructions` and a number of other settings. The `description` is added to the start of the system message and `instructions` are added as a list after `## Instructions`. For example:
```python instructions.py
from phi.agent import Agent
agent = Agent(
description="You are a famous short story writer asked to write for a magazine",
instructions=["You are a pilot on a plane flying from Hawaii to Japan."],
markdown=True,
debug_mode=True,
)
agent.print_response("Tell me a 2 sentence horror story.", stream=True)
```
Will translate to (set `debug_mode=True` to view the logs):
```js
DEBUG ============== system ==============
DEBUG You are a famous short story writer asked to write for a magazine
## Instructions
- You are a pilot on a plane flying from Hawaii to Japan.
- Use markdown to format your answers.
DEBUG ============== user ==============
DEBUG Tell me a 2 sentence horror story.
DEBUG ============== assistant ==============
DEBUG As the autopilot disengaged inexplicably mid-flight over the Pacific, the pilot glanced at the copilot's seat
only to find it empty despite his every recall of a full crew boarding. Hands trembling, he looked into the
cockpit's rearview mirror and found his own reflection grinning back with blood-red eyes, whispering,
"There's no escape, not at 30,000 feet."
DEBUG **************** METRICS START ****************
DEBUG * Time to first token: 0.4518s
DEBUG * Time to generate response: 1.2594s
DEBUG * Tokens per second: 63.5243 tokens/s
DEBUG * Input tokens: 59
DEBUG * Output tokens: 80
DEBUG * Total tokens: 139
DEBUG * Prompt tokens details: {'cached_tokens': 0}
DEBUG * Completion tokens details: {'reasoning_tokens': 0}
DEBUG **************** METRICS END ******************
```
## Set the system message directly
You can manually set the system message using the `system_prompt` parameter.
```python
from phi.agent import Agent
agent = Agent(system_prompt="Share a 2 sentence story about")
agent.print_response("Love in the year 12000.")
```
## User message
The input `message` sent to the `Agent.run()` or `Agent.print_response()` functions is used as the user message.
### User message when `enable_rag=True`
If the Agent is provided `knowledge`, and the `enable_rag=True`, the user message is set to:
```python
user_prompt += f"""Use the following information from the knowledge base if it helps:"
## Context
{context}
"""
```
## Default system message
The Agent creates a default system message that can be customized using the following parameters:
| Parameter | Type | Default | Description |
| ------------------------------ | ---------------- | -------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `description` | `str` | `None` | A description of the Agent that is added to the start of the system message. |
| `task` | `str` | `None` | Describe the task the agent should achieve. |
| `instructions` | `List[str]` | `None` | List of instructions added to the system prompt in `` tags. Default instructions are also created depending on values for `markdown`, `output_model` etc. |
| `additional_context` | `str` | `None` | Additional context added to the end of the system message. |
| `expected_output` | `str` | `None` | Provide the expected output from the Agent. This is added to the end of the system message. |
| `extra_instructions` | `List[str]` | `None` | List of extra instructions added to the default system prompt. Use these when you want to add some extra instructions at the end of the default instructions. |
| `prevent_hallucinations` | `bool` | `False` | If True, add instructions to return "I don't know" when the agent does not know the answer. |
| `prevent_prompt_injection` | `bool` | `False` | If True, add instructions to prevent prompt injection attacks. |
| `limit_tool_access` | `bool` | `False` | If True, add instructions for limiting tool access to the default system prompt if tools are provided |
| `markdown` | `bool` | `False` | Add an instruction to format the output using markdown. |
| `add_datetime_to_instructions` | `bool` | `False` | If True, add the current datetime to the prompt to give the agent a sense of time. This allows for relative times like "tomorrow" to be used in the prompt |
| `system_prompt` | `str` | `None` | System prompt: provide the system prompt as a string |
| `system_prompt_template` | `PromptTemplate` | `None` | Provide the system prompt as a PromptTemplate. |
| `use_default_system_message` | `bool` | `True` | If True, build a default system message using agent settings and use that. |
| `system_message_role` | `str` | `system` | Role for the system message. |
Disable the default system message by setting `use_default_system_message=False`.
## Default user message
The Agent creates a default user message, which is either the input message or a message with the `context` if `enable_rag=True`. The default user message can be customized using:
| Parameter | Type | Default | Description |
| -------------------------- | ------------------------ | ------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `enable_rag` | `bool` | `False` | Enable RAG by adding references from the knowledge base to the prompt. |
| `add_rag_instructions` | `bool` | `False` | If True, adds instructions for using the RAG to the system prompt (if knowledge is also provided). For example: add an instruction to prefer information from the knowledge base over its training data. |
| `add_history_to_messages` | `bool` | `False` | If true, adds the chat history to the messages sent to the Model. |
| `num_history_responses` | `int` | `3` | Number of historical responses to add to the messages. |
| `user_prompt` | `Union[List, Dict, str]` | `None` | Provide the user prompt as a string. Note: this will ignore the message sent to the run function. |
| `user_prompt_template` | `PromptTemplate` | `None` | Provide the user prompt as a PromptTemplate. |
| `use_default_user_message` | `bool` | `True` | If True, build a default user prompt using references and chat history. |
| `user_message_role` | `str` | `user` | Role for the user message. |
Disable the default user message by setting `use_default_user_message=False`.
# Reasoning
Source: https://docs.phidata.com/agents/reasoning
Reasoning is an **experimental feature** that enables an `Agent` to think through a problem step-by-step before jumping into a response. The Agent works through different ideas, validating and correcting as needed. Once it reaches a final answer, it will validate and provide a response. Let's give it a try. Create a file `reasoning_agent.py`
```python reasoning_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
task = (
"Three missionaries and three cannibals need to cross a river. "
"They have a boat that can carry up to two people at a time. "
"If, at any time, the cannibals outnumber the missionaries on either side of the river, the cannibals will eat the missionaries. "
"How can all six people get across the river safely? Provide a step-by-step solution and show the solutions as an ascii diagram"
)
reasoning_agent = Agent(model=OpenAIChat(id="gpt-4o"), reasoning=True, markdown=True, structured_outputs=True)
reasoning_agent.print_response(task, stream=True, show_full_reasoning=True)
```
Run the Reasoning Agent:
```bash
pip install -U phidata openai
export OPENAI_API_KEY=***
python reasoning_agent.py
```
Reasoning is currently limited to OpenAI models and will break about 20% of the time. **It is not a replacement for o1.**
It is an experiment fueled by curiosity, combining COT and tool use. Set your expectations very low for this initial release. For example: It will not be able to count ‘r’s in ‘strawberry’.
## How to use reasoning
To add reasoning, set `reasoning=True`. When using reasoning with tools, do not use `structured_outputs=True` as gpt-4o cannot use tools with structured outputs.
```python
reasoning_agent = Agent(
model=OpenAIChat(id="gpt-4o-2024-08-06"),
reasoning=True,
markdown=True,
structured_outputs=True,
)
reasoning_agent.print_response("How many 'r' are in the word 'supercalifragilisticexpialidocious'?", stream=True, show_full_reasoning=True)
```
## Reasoning with tools
You can also use tools with a reasoning agent, but do not use `structured_outputs=True` as gpt-4o cannot use tools with structured outputs. Lets create a finance agent that can reason.
Reasoning with tools is currently limited to OpenAI models and will break about 20% of the time.
```python finance_reasoning.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
reasoning_agent = Agent(
model=OpenAIChat(id="gpt-4o"),
instructions=["Use tables to show data"],
show_tool_calls=True,
markdown=True,
reasoning=True,
)
reasoning_agent.print_response("Write a report comparing NVDA to TSLA", stream=True, show_full_reasoning=True)
```
Run the script to see the output.
```bash
pip install -U phidata openai
export OPENAI_API_KEY=***
python finance_reasoning.py
```
## More reasoning examples
### Logical puzzles
```python logical_puzzle.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
task = (
"Three missionaries and three cannibals need to cross a river. "
"They have a boat that can carry up to two people at a time. "
"If, at any time, the cannibals outnumber the missionaries on either side of the river, the cannibals will eat the missionaries. "
"How can all six people get across the river safely? Provide a step-by-step solution and show the solutions as an ascii diagram"
)
reasoning_agent = Agent(
model=OpenAIChat(id="gpt-4o-2024-08-06"), reasoning=True, markdown=True, structured_outputs=True
)
reasoning_agent.print_response(task, stream=True, show_full_reasoning=True)
```
Run the script to see the output.
```bash
pip install -U phidata openai
export OPENAI_API_KEY=***
python logical_puzzle.py
```
### Mathematical proofs
```python mathematical_proof.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
task = "Prove that for any positive integer n, the sum of the first n odd numbers is equal to n squared. Provide a detailed proof."
reasoning_agent = Agent(
model=OpenAIChat(id="gpt-4o-2024-08-06"), reasoning=True, markdown=True, structured_outputs=True
)
reasoning_agent.print_response(task, stream=True, show_full_reasoning=True)
```
Run the script to see the output.
```bash
pip install -U phidata openai
export OPENAI_API_KEY=***
python mathematical_proof.py
```
### Scientific research
```python scientific_research.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
task = (
"Read the following abstract of a scientific paper and provide a critical evaluation of its methodology,"
"results, conclusions, and any potential biases or flaws:\n\n"
"Abstract: This study examines the effect of a new teaching method on student performance in mathematics. "
"A sample of 30 students was selected from a single school and taught using the new method over one semester. "
"The results showed a 15% increase in test scores compared to the previous semester. "
"The study concludes that the new teaching method is effective in improving mathematical performance among high school students."
)
reasoning_agent = Agent(
model=OpenAIChat(id="gpt-4o-2024-08-06"), reasoning=True, markdown=True, structured_outputs=True
)
reasoning_agent.print_response(task, stream=True, show_full_reasoning=True)
```
Run the script to see the output.
```bash
pip install -U phidata openai
export OPENAI_API_KEY=***
python scientific_research.py
```
### Ethical dilemma
```python ethical_dilemma.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
task = (
"You are a train conductor faced with an emergency: the brakes have failed, and the train is heading towards "
"five people tied on the track. You can divert the train onto another track, but there is one person tied there. "
"Do you divert the train, sacrificing one to save five? Provide a well-reasoned answer considering utilitarian "
"and deontological ethical frameworks. "
"Provide your answer also as an ascii art diagram."
)
reasoning_agent = Agent(
model=OpenAIChat(id="gpt-4o-2024-08-06"), reasoning=True, markdown=True, structured_outputs=True
)
reasoning_agent.print_response(task, stream=True, show_full_reasoning=True)
```
Run the script to see the output.
```bash
pip install -U phidata openai
export OPENAI_API_KEY=***
python ethical_dilemma.py
```
### Planning an itinerary
```python planning_itinerary.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
task = "Plan an itinerary from Los Angeles to Las Vegas"
reasoning_agent = Agent(
model=OpenAIChat(id="gpt-4o-2024-08-06"), reasoning=True, markdown=True, structured_outputs=True
)
reasoning_agent.print_response(task, stream=True, show_full_reasoning=True)
```
Run the script to see the output.
```bash
pip install -U phidata openai
export OPENAI_API_KEY=***
python planning_itinerary.py
```
### Creative writing
```python creative_writing.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
task = "Write a short story about life in 5000000 years"
reasoning_agent = Agent(
model=OpenAIChat(id="gpt-4o-2024-08-06"), reasoning=True, markdown=True, structured_outputs=True
)
reasoning_agent.print_response(task, stream=True, show_full_reasoning=True)
```
Run the script to see the output.
```bash
pip install -U phidata openai
export OPENAI_API_KEY=***
python creative_writing.py
```
# Storage
Source: https://docs.phidata.com/agents/storage
**Agents use storage to persist sessions by storing them in a database.**
Agents come with built-in memory, but it only lasts while the session is active. To continue conversations across sessions, we store agent sessions in a database like PostgreSQL.
The general syntax for adding storage to an Agent looks like:
```python
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.duckduckgo import DuckDuckGo
from phi.storage.agent.postgres import PgAgentStorage
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
storage=PgAgentStorage(table_name="agent_sessions", db_url="postgresql+psycopg://ai:ai@localhost:5532/ai"),
tools=[DuckDuckGo()],
show_tool_calls=True,
add_history_to_messages=True,
)
agent.print_response("How many people live in Canada?")
agent.print_response("What is their national anthem called?")
agent.print_response("Which country are we speaking about?")
```
## Example
Install [docker desktop](https://docs.docker.com/desktop/install/mac-install/) and run **Postgres** on port **5532** using:
```bash
docker run -d \
-e POSTGRES_DB=ai \
-e POSTGRES_USER=ai \
-e POSTGRES_PASSWORD=ai \
-e PGDATA=/var/lib/postgresql/data/pgdata \
-v pgvolume:/var/lib/postgresql/data \
-p 5532:5432 \
--name pgvector \
phidata/pgvector:16
```
Create a file `agent_with_storage.py` with the following contents
```python
import typer
from typing import Optional, List
from phi.agent import Agent
from phi.storage.agent.postgres import PgAgentStorage
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector, SearchType
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector(table_name="recipes", db_url=db_url, search_type=SearchType.hybrid),
)
# Load the knowledge base: Comment after first run
knowledge_base.load(upsert=True)
storage = PgAgentStorage(table_name="pdf_agent", db_url=db_url)
def pdf_agent(new: bool = False, user: str = "user"):
session_id: Optional[str] = None
if not new:
existing_sessions: List[str] = storage.get_all_session_ids(user)
if len(existing_sessions) > 0:
session_id = existing_sessions[0]
agent = Agent(
session_id=session_id,
user_id=user,
knowledge=knowledge_base,
storage=storage,
# Show tool calls in the response
show_tool_calls=True,
# Enable the agent to read the chat history
read_chat_history=True,
# We can also automatically add the chat history to the messages sent to the model
# But giving the model the chat history is not always useful, so we give it a tool instead
# to only use when needed.
# add_history_to_messages=True,
# Number of historical responses to add to the messages.
# num_history_responses=3,
)
if session_id is None:
session_id = agent.session_id
print(f"Started Session: {session_id}\n")
else:
print(f"Continuing Session: {session_id}\n")
# Runs the agent as a cli app
agent.cli_app(markdown=True)
if __name__ == "__main__":
typer.run(pdf_agent)
```
Install libraries
```bash Mac
pip install -U phidata openai pgvector pypdf "psycopg[binary]" sqlalchemy
```
```bash Windows
pip install -U phidata openai pgvector pypdf "psycopg[binary]" sqlalchemy
```
Run the agent
```bash
python agent_with_storage.py
```
Now the agent continues across sessions. Ask a question:
```
How do I make pad thai?
```
Then message `bye` to exit, start the app again and ask:
```
What was my last message?
```
Run the `agent_with_storage.py` file with the `--new` flag to start a new run.
```bash
python agent_with_storage.py --new
```
## Params
| Parameter | Type | Default | Description |
| --------- | ------------------------ | ------- | ----------------------------------------------- |
| `storage` | `Optional[AgentStorage]` | `None` | Storage mechanism for the agent, if applicable. |
# Structured Output
Source: https://docs.phidata.com/agents/structured-output
One of our favorite features is using Agents to generate structured data (i.e. a pydantic model). Use this feature to extract features, classify data, produce fake data etc. The best part is that they work with function calls, knowledge bases and all other features.
## Example
Let's create an Movie Agent to write a `MovieScript` for us.
```python movie_agent.py
from typing import List
from rich.pretty import pprint
from pydantic import BaseModel, Field
from phi.agent import Agent, RunResponse
from phi.model.openai import OpenAIChat
class MovieScript(BaseModel):
setting: str = Field(..., description="Provide a nice setting for a blockbuster movie.")
ending: str = Field(..., description="Ending of the movie. If not available, provide a happy ending.")
genre: str = Field(
..., description="Genre of the movie. If not available, select action, thriller or romantic comedy."
)
name: str = Field(..., description="Give a name to this movie")
characters: List[str] = Field(..., description="Name of characters for this movie.")
storyline: str = Field(..., description="3 sentence storyline for the movie. Make it exciting!")
# Agent that uses JSON mode
json_mode_agent = Agent(
model=OpenAIChat(id="gpt-4o"),
description="You write movie scripts.",
response_model=MovieScript,
)
# Agent that uses structured outputs
structured_output_agent = Agent(
model=OpenAIChat(id="gpt-4o-2024-08-06"),
description="You write movie scripts.",
response_model=MovieScript,
structured_outputs=True,
)
# Get the response in a variable
# json_mode_response: RunResponse = json_mode_agent.run("New York")
# pprint(json_mode_response.content)
# structured_output_response: RunResponse = structured_output_agent.run("New York")
# pprint(structured_output_response.content)
json_mode_agent.print_response("New York")
structured_output_agent.print_response("New York")
```
Run the script to see the output.
```bash
pip install -U phidata openai
python movie_agent.py
```
The output is an object of the `MovieScript` class, here's how it looks:
```python
# Using JSON mode
MovieScript(
│ setting='The bustling streets of New York City, filled with skyscrapers, secret alleyways, and hidden underground passages.',
│ ending='The protagonist manages to thwart an international conspiracy, clearing his name and winning the love of his life back.',
│ genre='Thriller',
│ name='Shadows in the City',
│ characters=['Alex Monroe', 'Eva Parker', 'Detective Rodriguez', 'Mysterious Mr. Black'],
│ storyline="When Alex Monroe, an ex-CIA operative, is framed for a crime he didn't commit, he must navigate the dangerous streets of New York to clear his name. As he uncovers a labyrinth of deceit involving the city's most notorious crime syndicate, he enlists the help of an old flame, Eva Parker. Together, they race against time to expose the true villain before it's too late."
)
# Use the structured output
MovieScript(
│ setting='In the bustling streets and iconic skyline of New York City.',
│ ending='Isabella and Alex, having narrowly escaped the clutches of the Syndicate, find themselves standing at the top of the Empire State Building. As the glow of the setting sun bathes the city, they share a victorious kiss. Newly emboldened and as an unstoppable duo, they vow to keep NYC safe from any future threats.',
│ genre='Action Thriller',
│ name='The NYC Chronicles',
│ characters=['Isabella Grant', 'Alex Chen', 'Marcus Kane', 'Detective Ellie Monroe', 'Victor Sinclair'],
│ storyline='Isabella Grant, a fearless investigative journalist, uncovers a massive conspiracy involving a powerful syndicate plotting to control New York City. Teaming up with renegade cop Alex Chen, they must race against time to expose the culprits before the city descends into chaos. Dodging danger at every turn, they fight to protect the city they love from imminent destruction.'
)
```
# Teams
Source: https://docs.phidata.com/agents/teams
We can combine multiple Agents to form a team and tackle tasks as a cohesive unit. Here's a simple example that uses a team of agents to write an article about the top stories on hackernews.
```python hn_team.py
from phi.agent import Agent
from phi.tools.hackernews import HackerNews
from phi.tools.duckduckgo import DuckDuckGo
from phi.tools.newspaper4k import Newspaper4k
hn_researcher = Agent(
name="HackerNews Researcher",
role="Gets top stories from hackernews.",
tools=[HackerNews()],
)
web_searcher = Agent(
name="Web Searcher",
role="Searches the web for information on a topic",
tools=[DuckDuckGo()],
add_datetime_to_instructions=True,
)
article_reader = Agent(
name="Article Reader",
role="Reads articles from URLs.",
tools=[Newspaper4k()],
)
hn_team = Agent(
name="Hackernews Team",
team=[hn_researcher, web_searcher, article_reader],
instructions=[
"First, search hackernews for what the user is asking about.",
"Then, ask the article reader to read the links for the stories to get more information.",
"Important: you must provide the article reader with the links to read.",
"Then, ask the web searcher to search for each story to get more information.",
"Finally, provide a thoughtful and engaging summary.",
],
show_tool_calls=True,
markdown=True,
)
hn_team.print_response("Write an article about the top 2 stories on hackernews", stream=True)
```
Run the script to see the output.
```bash
pip install -U openai duckduckgo-search newspaper4k lxml_html_clean phidata
python hn_team.py
```
## How to build Agent Teams
1. Add a `name` and `role` parameter to the member Agents.
2. Create a Team Leader that can delegate tasks to team-members.
3. Use your Agent team just like you would use a regular Agent.
Open-ended Agentic teams are great to play with, but are not reliable for real-world problems that require high reliability.
They need constant oversight and can get confused on very complex tasks. This drawback should improve as models get better (eagerly waiting for gpt-5o).
In our experience, Agent teams work best for simple tasks that require a small number of steps. We highly recommend using Workflows for production applications.
# Tools
Source: https://docs.phidata.com/agents/tools
**Agents use tools to take actions and interact with external systems**.
Tools are functions that an Agent can run to achieve tasks. For example: searching the web, running SQL, sending an email or calling APIs. You can use any python function as a tool or use a pre-built **toolkit**. The general syntax is:
```python
from phi.agent import Agent
agent = Agent(
# Add functions or Toolkits
tools=[...],
# Show tool calls in the Agent response
show_tool_calls=True
)
```
## Using a Toolkit
Phidata provides many pre-built **toolkits** that you can add to your Agents. For example, let's use the DuckDuckGo toolkit to search the web.
You can find more toolkits in the [Toolkits](/tools/toolkits) guide.
Create a file `web_search.py`
```python web_search.py
from phi.agent import Agent
from phi.tools.duckduckgo import DuckDuckGo
agent = Agent(tools=[DuckDuckGo()], show_tool_calls=True, markdown=True)
agent.print_response("Whats happening in France?", stream=True)
```
Install libraries
```shell
pip install openai duckduckgo-search phidata
```
Run the agent
```shell
python web_search.py
```
## Writing your own Tools
For more control, write your own python functions and add them as tools to an Agent. For example, here's how to add a `get_top_hackernews_stories` tool to an Agent.
```python hn_agent.py
import json
import httpx
from phi.agent import Agent
def get_top_hackernews_stories(num_stories: int = 10) -> str:
"""Use this function to get top stories from Hacker News.
Args:
num_stories (int): Number of stories to return. Defaults to 10.
Returns:
str: JSON string of top stories.
"""
# Fetch top story IDs
response = httpx.get('https://hacker-news.firebaseio.com/v0/topstories.json')
story_ids = response.json()
# Fetch story details
stories = []
for story_id in story_ids[:num_stories]:
story_response = httpx.get(f'https://hacker-news.firebaseio.com/v0/item/{story_id}.json')
story = story_response.json()
if "text" in story:
story.pop("text", None)
stories.append(story)
return json.dumps(stories)
agent = Agent(tools=[get_top_hackernews_stories], show_tool_calls=True, markdown=True)
agent.print_response("Summarize the top 5 stories on hackernews?", stream=True)
```
Read more about:
* [Available toolkits](/tools/toolkits)
* [Using functions as tools](/tools/functions)
## Attributes
The following attributes allow an `Agent` to use tools
| Parameter | Type | Default | Description |
| ------------------------ | ------------------------------------------------------ | ------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `tools` | `List[Union[Tool, Toolkit, Callable, Dict, Function]]` | - | A list of tools provided to the Model. Tools are functions the model may generate JSON inputs for. |
| `show_tool_calls` | `bool` | `False` | Print the signature of the tool calls in the Model response. |
| `tool_call_limit` | `int` | - | Maximum number of tool calls allowed. |
| `tool_choice` | `Union[str, Dict[str, Any]]` | - | Controls which (if any) tool is called by the model. "none" means the model will not call a tool and instead generates a message. "auto" means the model can pick between generating a message or calling a tool. Specifying a particular function via `{"type": "function", "function": {"name": "my_function"}}` forces the model to call that tool. "none" is the default when no tools are present. "auto" is the default if tools are present. |
| `read_chat_history` | `bool` | `False` | Add a tool that allows the Model to read the chat history. |
| `search_knowledge` | `bool` | `False` | Add a tool that allows the Model to search the knowledge base (aka Agentic RAG). |
| `update_knowledge` | `bool` | `False` | Add a tool that allows the Model to update the knowledge base. |
| `read_tool_call_history` | `bool` | `False` | Add a tool that allows the Model to get the tool call history. |
# Product updates
Source: https://docs.phidata.com/changelog/overview
## Release 2.7.10
## New Features:
* **ClickUp Tool**: Added support for managing tasks on ClickUp.
## Improvements:
* **Postgres custom table schema:** Add custom table schema parameter for Postgres tools.
## New Examples:
* **LLM-OS v1:** Add a streamlit application example for LLM-OS. A application that uses an LLM with advanced operating-system level capabilities.
* **GeoBuddy:** An AI-powered geography agent that analyzes images to predict locations based on visible cues like landmarks, architecture, and cultural symbols.
## Bug Fixes:
* **Text Search Compatibility:** Resolved an issue where Text Search was not forward-compatible with recent versions.
* **Custom Function Parsing:** Fixed an issue where function parsing for custom functions did not pass all parameters to the AI.
* **Claude Memory Handling:** Addressed an issue in Claude where memory was not correctly handled during streaming.
* **Gemini RepeatedComposite and other parsing issues:** Gemini messages were incompatible with memory and storage in some cases. This has been resolved.
## Tools and Fixes
## New Features
* **RedditTools**: Added RedditTools with cookbook examples.
* **TelegramTools**: Introduced TelegramTools with a cookbook example.
## Improvements
* **GeminiEmbedder Defaults**: Updated the defaults on the GeminiEmbedder to use a more up-to-date model and incorporate recommendations from their [docs](https://docs.phidata.com/embedder/gemini#params)
## Bug Fixes:
* **Playground Imports**: Fixed imports of `docx` being required for using the playground.
* **AzureOpenAI Compatibility**: Resolved compatibility issues with AzureOpenAIEmbedder and AzureOpenAIChat.
* **SlackTool Exceptions**: Fixed cases where SlackTool threw an exception when the "user" field was blank or not available.
* **Response Models**: Fixed cases where Response Models didn’t work with `show_tool_calls`, ensuring the response model is used if one is available.
* **Claude Memory Blocks**: Fixed an issue where memory blocks in raw Claude fromat with TextBlock, etc.
* **Model Switching**: Fixed cases where switching models from ChatGPT to Gemini with the same history caused issues.
## Support for OpenAI o1
## New Features:
* Google Calendar Tool Added
## Bug Fixes:
* Fixed `get_embedding_and_usage` function of `FastEmbedEmbedder`.
* Fixed `developer` as a role being incorrect for `OpenAILike` models.
* Fixed `insert` function of `LanceDb` .
## New Example
* New Marketing Workflow example added
## Improvements and Fixes
This release introduces new capabilities, such as image-to-image generation, MongoDB vector support, and enhanced chunking methods, alongside significant bug fixes and usability enhancements.
### New Features:
* **Image-to-Image Generation Support**: Extended FalTools to support image-to-image generation.
* **MongoDB Integrations**: Added MongoDB support across agent storage, knowledge base, agent memory, and workflow storage.
* **Download Image Utility**: Introduced a utility to download agent-generated images directly for enhanced workflows.
### Improvements:
* **Audio Transcript Handling**: Refined the handling of audio transcripts to ensure accurate message output when processing audio files.
* **Optimized Chunking**: Enhanced fixed and recursive chunking methods to improve document processing performance.
* **HuggingFace Embedder**: Resolved compatibility issues with HuggingFace embedder for better reliability.
* **Ollama Embedder**: Upgraded the Ollama embedder for more robust and efficient embedding capabilities.
* **OpenAI o1 Model Specification Support**: Added support for OpenAI o1 model specifications, enabling compatibility with the latest OpenAI features.
* **Spider Tool Improvements**: Addressed performance issues with the Spider tool to enhance reliability.
* **LanceDB Enhancements**: Added support for accessing existing database tables in LanceDB.
* **Github tool repo creation**: Added support for repo creation via the Github tool.
* **ScrapeGraph tool addition**: Adds integration with ScrapeGraph AI for smart web scraping and markdown conversion capabilities.
### Bug Fixes:
* **OpenAI rejecting functions with too large description**: This issue was discovered with Composio tools, but affected all tools. Resolved and made tool definitions better match JSON Schema.
* **Google Embedder Compatibility**: Fixed an issue with Pydantic 2.10.x that caused the rejection of the Google embedder, restoring full functionality.
* **ChromaDB Upsert Issue**: Resolved bugs that caused errors during upsert operations in ChromaDB.
* **Async Error Messaging**: Improved error messages for unsupported async operations in models.
* **Gemini Tool Parameters**: Fixed an issue with parameter handling in Gemini tools.
## Extending Vector database support
This update adds new vector database integrations, improvements to DuckDuckGo tool and Gemini model and new cookbooks.
### New Features:
* **Cassandra Integration as a Vector Database**: Introduced support for Apache Cassandra as a Vector Database, leveraging CassIO for vector storage and retrieval.
* **ClickHouse as a Vector Database**: Added support for ClickHouse as a Vector Database.
### Improvements
* **DuckDuckGo Modifier**: Added a `modifier` parameter to the DuckDuckGo tool, allowing users to refine searches with site-specific queries, file type filters, and safe search toggles.
* **Enhanced Error Handling for python-docx**: Improved error messaging for scenarios where the `python-docx` library is not installed, providing clearer guidance and smoother debugging.
### Bug Fixes
* **Qdrant Default Embedder**: Removed OpenAI as the default embedder for Qdrant, enabling user-configurable embeddings.
* **Gemini Import Fix**: Fixed an issue where missing OpenAI library dependencies caused errors when using Gemini.
## Confluence Tool & Fixes
This update introduces the Confluence tool for collaboration, improves tool compatibility, and resolves deep copy issues for Ollama chat agents.
### New Features
* **Confluence Tool**: Added a new tool using the Atlassian Confluence SDK, enabling operations such as listing pages in a space, creating and updating pages, retrieving page content by title, and getting space details.
### Improvements
* **Tool Compatibility**: Enhanced older custom functions with manually specified descriptions and parameters to align with the updated tool-building system.
### Bug Fixes
* **Deep Copy for Ollama Chat Agents**: Addressed an issue where manually set clients caused errors during agent model copying, ensuring all properties are properly handled.
## Audio Support and Enhancements
This release enhances multimodal capabilities with audio support, improves session page performance, and fixes various bugs for better stability and usability.
 ### New Features
* **Audio Response Support**: Added support for audio responses, enhancing multimodal interaction capabilities.
* **Audio Generation Tools**: Integrated Eleven Labs for Audio Generation.
* **Cohere Embedder**: Introduced a new Cohere Embedder class with a corresponding cookbook example to demonstrate its usage.
* **File Agent Storage Support**: Added JSON and YAML as storage options for agent session data.
### Improvements
* **Version Checker for OpenAI**: Added a warning for users with OpenAI versions below 1.52.0 to ensure compatibility with features like `audio` in `ChatCompletionMessage`.
* **Agent Response Handling**: Enhanced processing of agent responses to support lists, improving handling of multi-item outputs.
### Bug Fixes
* **AWS Bedrock Tool Descriptions**: Fixed an issue where the transfer tool description was missing, causing incompatibility with AWS Bedrock Claude.
* **Response Content Handling**: Resolved crashes on the session page caused by non-string response content.
* **Deep Copy Agent Memory**: Addressed deep copy errors when using agent memory on the playground.
* **Session Page Enhancements**: Fixed the refresh button.
* **Fix Tool Parsing for Ollama**: Fixed JSON schema tool parsing by transforming `['string', 'null']` parameters to `'string'` for compatibility.
* **Response Parsing for Gemini Tool**: Improved response parsing to handle unserializable objects in `tool_calls` for Gemini on the playground.
* **Memory Handling for Google Provider**: Fixed an issue in `monitoring_data` where memory was removed for all providers, causing blank titles on Phidata.app; now only modifies memory for Google provider.
* **RecursiveChunking ID Conflict**: Resolved an issue in RecursiveChunking where processing large files with multiple chunks caused duplicate chunk record IDs, leading to `psycopg.errors.UniqueViolation`.
## Multi-Modal Tools
This update introduces new multimodal tools, enhances the multimodal capabilities of existing models, and includes several quality-of-life improvements.
## New Features
* **Giphy Tool**: Added Giphy integration to enhance creative collaboration.
* **Native image upload support for Claude**: Added native support for uploading images natively to the Anthropic API.
* **Youtube Knowledge base**: Added support for new YouTube knowledge base, allowing it to be loaded directly using YouTube video links.
## Improvements
* **API key validation**: Added API key validation for model classes.
* **Gemini audio**: Improved native audio upload support for Gemini Model.
* **YoutubeTools**: A new Youtube tool which allows generation of timestamps
* **Workspace Configuration Flexibility**: Refactored type-checking logic using `isinstance()` to enhance flexibility and maintainability.
* **Web Crawler Stability**: Switched to crawl4ai async to resolve issues and improve performance.
* **Memory Optimization**: Improved memory usage in large-scale workflows for better efficiency.
* **User Interface**: Refined the UI for better tracking of team activities.
## Bug Fixes
* **Role-Based Access Control Bugs**: Resolved issues affecting access permissions.
* **Gemini Functions**: Fixed errors when functions had no specified parameters.
## Gemini Improvements
### Improvements
* Improvements to Gemini Multimodality.
## Gemini 2 Update
 ### New Features
* **Gemini Multimodal Support**: Added support for multimodal (image, video, text) input processing with Gemini.
* **Mem0 Integration Example**: Introduced a cookbook example demonstrating Mem0 integration for Agent memory.
* **CSV URL Knowledgebase**: Added functionality to create and manage knowledgebases from CSV URLs.
### Improvements
* **Vertex AI Gemini 2 Update**: The Vertex AI class has been updated to support the Gemini 2 model.
### Bug Fixes
* **Structured Output Fix**: Resolved issues with Ollama structured output to ensure consistent data formatting.
## From Text to Media: A Multi-Modal Leap
This update introduces image and video multi-modal support for the agent playground and adds image and video generation tools like FAL, replicate, and ModelLabs.
 ### Highlights
* **Support for video**: Agents now natively support video.
* **Multi-Modal rendering on Agent Playground**: Agent Playground can now render images and videos.
### New Features
* **New Tools**: Added Replicate, FAL, and ModelLabs tools to generate video and images.
### Improvements
* Various cookbook examples were added to cover real-world agent use cases.
## Enhanced Agent Visibility, RAG Improvements, and Workflow Tools
This update introduces exciting new features, performance enhancements, and crucial fixes to ensure better usability and functionality.
### Highlights
* **Multimodal Agents**: Agents now natively support image and audio with video coming soon.
* **Agentic Workflows are now generally available**: Build deterministic multi-agent pipelines using Workflows.
* **Agent can share state between tool calls**: New session\_state variable allows Agents to maintain and share state across function calls.
* **Agents in teams can respond directly to the user**: now responses of team members do not need to go through the team leader.
* **Context Injection**: Agents can be provided context that is resolved in real-time during execution.
* **Human-in-the-loop**: Tool calls can now be confirmed (or approved) before being executed.
* **Advanced chunking**: Support for Semantic and Agentic chunking (and more).
### New Features
* **Show Reasoning in the Playground**: Provides users with insights into the agent's thought process and decision-making, offering a behind-the-scenes look at how the agent operates within the Playground.
* **Show Tool Call in the Playground**: Display tool call results and metrics on hover within the Playground.
* **Sessions Page Enhancements**: Added context, reasoning, and tools integration to the Sessions page.
* **Delete Custom Endpoint for Playground**: Introduced the ability to delete endpoints directly within the Playground.
* **Show References in the Playground**: You can now view the sources used for RAG.
* **Chunking Strategies in RAG**: Introduced five levels of chunking strategies in RAG: Semantic Chunking, Fixed Chunking, Agentic Chunking, Document Chunking, and Recursive Chunking.
* **Unified Reranker for Vector Databases**: Implemented a unified reranking feature across various vector databases, including LanceDB, with support for CohereReranker.
* **Milvus Vector Database Integration**: Added support for Milvus as a vector database option.
* **Support for Multi-Modalities**: Added support for processing audio, video, and image data to enhance agent capabilities.
* **Context Injection**: Improved context handling to enhance agent responses and usability.
* **Pre-hook and post-hook for function calls**: enabling users to validate arguments, add human-in-the-loop flows and validate results of tool calls.
### Improvements
* **Duplicate Endpoint Prevention**: Enhanced endpoint creation logic to prevent duplicates.
* **Workflow Session Logging**: Improved logging mechanisms for workflow sessions.
* **Ollama Tool Call Streaming**: Updated the Ollama tool to improve call streaming capabilities.
* **Logging Updates for Gemini**: Enhanced logging functionality for Gemini models.
* **Ollama LLM Class Updates**: Resolved issues in tool calling to improve usage reliability.
* **Product Manager Agent Workflow Example**: Added a new example to demonstrate the practical use and capabilities of workflow.
* **Dynamic Prompt**: System prompt, user prompt and instructions can now be passed as functions resolved during run-time.
### Bug Fixes
* **Session Read-All Fix**: Fixed an issue where titles were not created when users provided a list of messages instead of a single message.
* **Ollama Tool Response Issue**: Addressed inconsistencies where Ollama tools always returned empty responses.
### Breaking Changes
* **`Agent.add_context` is now `Agent.add_references`** as the context terminology is now used for context injection. Similarly, `context_format` is now `references_format`.
## New Integrations
This update is packed with new integrations, significant improvements to existing tools, and crucial fixes to enhance functionality and user experience.
### New Features
* **InternLM Support**: Added feature request integration for InternLM25.
* **Google Vertex AI Integration**: Expanded compatibility with Google Model Vertex AI.
* **Discord Integration Tool**: Seamlessly connect and collaborate within Discord.
* **Baidu Search Tool**: Introducing Baidu Search integration for enhanced search capabilities in Phidata workflows.
### Improvements
* **Agent Monitoring Sync**: Optimized synchronization between Reasoning Agent and Main Agent
* **Knowledge Cookbooks**: Improved usability with enhanced S3, embedder, and document cookbooks; added an example using LanceDB as a vector database.
* **License Clarifications**: Updated license for better transparency and understanding.
* **Default Model Adjustments**: Refined the default model example for OpenAI; new guidance to avoid errors when changing models.
* **Qwen2.5 Coding Agent**: Performance enhancements and stability improvements.
* **Installation Improvements**: Added support for "psycopg\[binary]" in installation commands
### Bug Fixes
* **Phi Tool Templates**: Integrated new templates and added a comprehensive cookbook.
* **Knowledge Base Cookbooks**: Addressed inconsistencies for a seamless experience.
* **Context Creation**: Fixed an issue where empty contexts couldn't be created without a knowledge base.
* **Ollama Knowledge Example**: Resolved errors for improved functionality and reliability.
# Agentic Chunking
Source: https://docs.phidata.com/chunking/agentic-chunking
Agentic chunking is an intelligent method of splitting documents into smaller chunks by using an LLM to determine natural breakpoints in the text. Rather than splitting text at fixed character counts, it analyzes the content to find semantically meaningful boundaries like paragraph breaks and topic transitions.
## Usage
```python
from phi.agent import Agent
from phi.document.chunking.agentic import AgenticChunking
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector(table_name="recipes_agentic_chunking", db_url=db_url),
chunking_strategy=AgenticChunking(),
)
knowledge_base.load(recreate=False) # Comment out after first run
agent = Agent(
knowledge_base=knowledge_base,
search_knowledge=True,
)
agent.print_response("How to make Thai curry?", markdown=True)
```
## Params
| Parameter | Type | Default | Description |
| ---------------- | ------- | ------------ | ------------------------------- |
| `model` | `Model` | `OpenAIChat` | The model to use for chunking. |
| `max_chunk_size` | `int` | `5000` | The maximum size of each chunk. |
# Document Chunking
Source: https://docs.phidata.com/chunking/document-chunking
Document chunking is a method of splitting documents into smaller chunks based on document structure like paragraphs and sections. It analyzes natural document boundaries rather than splitting at fixed character counts. This is useful when you want to process large documents while preserving semantic meaning and context.
## Usage
```python
from phi.agent import Agent
from phi.document.chunking.document import DocumentChunking
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector(table_name="recipes_document_chunking", db_url=db_url),
chunking_strategy=DocumentChunking(),
)
knowledge_base.load(recreate=False) # Comment out after first run
agent = Agent(
knowledge_base=knowledge_base,
search_knowledge=True,
)
agent.print_response("How to make Thai curry?", markdown=True)
```
## Params
| Parameter | Type | Default | Description |
| ------------ | ----- | ------- | --------------------------------------------------- |
| `chunk_size` | `int` | `5000` | The maximum size of each chunk. |
| `overlap` | `int` | `0` | The number of characters to overlap between chunks. |
# Fixed Size Chunking
Source: https://docs.phidata.com/chunking/fixed-size-chunking
Fixed size chunking is a method of splitting documents into smaller chunks of a specified size, with optional overlap between chunks. This is useful when you want to process large documents in smaller, manageable pieces.
## Usage
```python
from phi.agent import Agent
from phi.document.chunking.fixed import FixedSizeChunking
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector(table_name="recipes_fixed_size_chunking", db_url=db_url),
chunking_strategy=FixedSizeChunking(),
)
knowledge_base.load(recreate=False) # Comment out after first run
agent = Agent(
knowledge_base=knowledge_base,
search_knowledge=True,
)
agent.print_response("How to make Thai curry?", markdown=True)
```
## Params
| Parameter | Type | Default | Description |
| ------------ | ----- | ------- | --------------------------------------------------- |
| `chunk_size` | `int` | `5000` | The maximum size of each chunk. |
| `overlap` | `int` | `0` | The number of characters to overlap between chunks. |
# Recursive Chunking
Source: https://docs.phidata.com/chunking/recursive-chunking
Recursive chunking is a method of splitting documents into smaller chunks by recursively applying a chunking strategy. This is useful when you want to process large documents in smaller, manageable pieces.
```python
from phi.agent import Agent
from phi.document.chunking.recursive import RecursiveChunking
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector(table_name="recipes_recursive_chunking", db_url=db_url),
chunking_strategy=RecursiveChunking(),
)
knowledge_base.load(recreate=False) # Comment out after first run
agent = Agent(
knowledge_base=knowledge_base,
search_knowledge=True,
)
agent.print_response("How to make Thai curry?", markdown=True)
```
## Params
| Parameter | Type | Default | Description |
| ------------ | ----- | ------- | --------------------------------------------------- |
| `chunk_size` | `int` | `5000` | The maximum size of each chunk. |
| `overlap` | `int` | `0` | The number of characters to overlap between chunks. |
# Semantic Chunking
Source: https://docs.phidata.com/chunking/semantic-chunking
Semantic chunking is a method of splitting documents into smaller chunks by analyzing semantic similarity between text segments using embeddings. It uses the chonkie library to identify natural breakpoints where the semantic meaning changes significantly, based on a configurable similarity threshold. This helps preserve context and meaning better than fixed-size chunking by ensuring semantically related content stays together in the same chunk, while splitting occurs at meaningful topic transitions.
```python
from phi.agent import Agent
from phi.document.chunking.semantic import SemanticChunking
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector(table_name="recipes_semantic_chunking", db_url=db_url),
chunking_strategy=SemanticChunking(),
)
knowledge_base.load(recreate=False) # Comment out after first run
agent = Agent(
knowledge_base=knowledge_base,
search_knowledge=True,
)
agent.print_response("How to make Thai curry?", markdown=True)
```
## Params
| Parameter | Type | Default | Description |
| ---------------------- | ---------- | ---------------- | ---------------------------------------------------------- |
| `embedder` | `Embedder` | `OpenAIEmbedder` | The embedder to use for semantic chunking. |
| `chunk_size` | `int` | `5000` | The maximum size of each chunk. |
| `similarity_threshold` | `float` | `0.5` | The similarity threshold for determining chunk boundaries. |
# Azure OpenAI Embedder
Source: https://docs.phidata.com/embedder/azure_openai
The `AzureOpenAIEmbedder` class is used to embed text data into vectors using the Azure OpenAI API. Get your key from [here](https://ai.azure.com/).
## Usage
```python cookbook/embedders/azure_embedder.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.azure_openai import AzureOpenAIEmbedder
embeddings = AzureOpenAIEmbedder().get_embedding("The quick brown fox jumps over the lazy dog.")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="azure_openai_embeddings",
embedder=AzureOpenAIEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| ------------------------- | ----------------------------- | -------------------------- | -------------------------------------------------------------------------------- |
| `model` | `str` | `"text-embedding-ada-002"` | The name of the model used for generating embeddings. |
| `dimensions` | `int` | `1536` | The dimensionality of the embeddings generated by the model. |
| `encoding_format` | `Literal['float', 'base64']` | `"float"` | The format in which the embeddings are encoded. Options are "float" or "base64". |
| `user` | `str` | - | The user associated with the API request. |
| `api_key` | `str` | - | The API key used for authenticating requests. |
| `api_version` | `str` | `"2024-02-01"` | The version of the API to use for the requests. |
| `azure_endpoint` | `str` | - | The Azure endpoint for the API requests. |
| `azure_deployment` | `str` | - | The Azure deployment name for the API requests. |
| `base_url` | `str` | - | The base URL for the API endpoint. |
| `azure_ad_token` | `str` | - | The Azure Active Directory token for authentication. |
| `azure_ad_token_provider` | `Any` | - | The provider for obtaining the Azure AD token. |
| `organization` | `str` | - | The organization associated with the API request. |
| `request_params` | `Optional[Dict[str, Any]]` | - | Additional parameters to include in the API request. Optional. |
| `client_params` | `Optional[Dict[str, Any]]` | - | Additional parameters for configuring the API client. Optional. |
| `openai_client` | `Optional[AzureOpenAIClient]` | - | An instance of the AzureOpenAIClient to use for making API requests. Optional. |
# Fireworks Embedder
Source: https://docs.phidata.com/embedder/fireworks
The `FireworksEmbedder` can be used to embed text data into vectors using the Fireworks API. Fireworks uses the OpenAI API specification, so the `FireworksEmbedder` class is similar to the `OpenAIEmbedder` class, incorporating adjustments to ensure compatibility with the Fireworks platform. Get your key from [here](https://fireworks.ai/account/api-keys).
## Usage
```python cookbook/embedders/fireworks_embedder.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.fireworks import FireworksEmbedder
embeddings = FireworksEmbedder().get_embedding("The quick brown fox jumps over the lazy dog.")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="fireworks_embeddings",
embedder=FireworksEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| ------------ | ----- | ----------------------------------------- | ------------------------------------------------------------ |
| `model` | `str` | `"nomic-ai/nomic-embed-text-v1.5"` | The name of the model used for generating embeddings. |
| `dimensions` | `int` | `768` | The dimensionality of the embeddings generated by the model. |
| `api_key` | `str` | - | The API key used for authenticating requests. |
| `base_url` | `str` | `"https://api.fireworks.ai/inference/v1"` | The base URL for the API endpoint. |
# Gemini Embedder
Source: https://docs.phidata.com/embedder/gemini
The `GeminiEmbedder` class is used to embed text data into vectors using the Gemini API. You can get one from [here](https://ai.google.dev/aistudio).
## Usage
```python cookbook/embedders/gemini_embedder.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.google import GeminiEmbedder
embeddings = GeminiEmbedder().get_embedding("The quick brown fox jumps over the lazy dog.")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="gemini_embeddings",
embedder=GeminiEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| ---------------- | -------------------------- | --------------------------- | ----------------------------------------------------------- |
| `dimensions` | `int` | `768` | The dimensionality of the generated embeddings |
| `model` | `str` | `models/text-embedding-004` | The name of the Gemini model to use |
| `task_type` | `str` | - | The type of task for which embeddings are being generated |
| `title` | `str` | - | Optional title for the embedding task |
| `api_key` | `str` | - | The API key used for authenticating requests. |
| `request_params` | `Optional[Dict[str, Any]]` | - | Optional dictionary of parameters for the embedding request |
| `client_params` | `Optional[Dict[str, Any]]` | - | Optional dictionary of parameters for the Gemini client |
| `gemini_client` | `Optional[Client]` | - | Optional pre-configured Gemini client instance |
# HuggingFace Embedder
Source: https://docs.phidata.com/embedder/huggingface
The `HuggingfaceCustomEmbedder` class is used to embed text data into vectors using the Hugging Face API. You can get one from [here](https://huggingface.co/settings/tokens).
## Usage
```python cookbook/embedders/huggingface_embedder.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.huggingface import HuggingfaceCustomEmbedder
embeddings = HuggingfaceCustomEmbedder().get_embedding("The quick brown fox jumps over the lazy dog.")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="huggingface_embeddings",
embedder=HuggingfaceCustomEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| -------------------- | -------------------------- | ------------------ | ------------------------------------------------------------ |
| `dimensions` | `int` | - | The dimensionality of the generated embeddings |
| `model` | `str` | `all-MiniLM-L6-v2` | The name of the HuggingFace model to use |
| `api_key` | `str` | - | The API key used for authenticating requests |
| `client_params` | `Optional[Dict[str, Any]]` | - | Optional dictionary of parameters for the HuggingFace client |
| `huggingface_client` | `Any` | - | Optional pre-configured HuggingFace client instance |
# Introduction
Source: https://docs.phidata.com/embedder/introduction
An Embedder converts complex information into vector representations, allowing it to be stored in a vector database. By transforming data into embeddings, the embedder enables efficient searching and retrieval of contextually relevant information. This process enhances the responses of language models by providing them with the necessary business context, ensuring they are context-aware. Phidata uses `OpenAIEmbedder` as the default embedder, but other embedders are supported as well. Here is an example:
```python
from phi.agent import Agent, AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.openai import OpenAIEmbedder
# Create knowledge base
knowledge_base=AgentKnowledge(
vector_db=PgVector(
db_url=db_url,
table_name=embeddings_table,
embedder=OpenAIEmbedder(),
),
# 2 references are added to the prompt
num_documents=2,
),
# Add information to the knowledge base
knowledge_base.load_text("The sky is blue")
# Add the knowledge base to the Agent
agent = Agent(knowledge_base=knowledge_base)
```
The following embedders are supported:
* [OpenAI](/embedder/openai)
* [Gemini](/embedder/gemini)
* [Ollama](/embedder/ollama)
* [Voyage AI](/embedder/voyageai)
* [Azure OpenAI](/embedder/azure_openai)
* [Mistral](/embedder/mistral)
* [Fireworks](/embedder/fireworks)
* [Together](/embedder/together)
* [HuggingFace](/embedder/huggingface)
* [Qdrant FastEmbed](/embedder/qdrant_fastembed)
# Mistral Embedder
Source: https://docs.phidata.com/embedder/mistral
The `MistralEmbedder` class is used to embed text data into vectors using the Mistral API. Get your key from [here](https://console.mistral.ai/api-keys/).
## Usage
```python cookbook/embedders/mistral_embedder.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.mistral import MistralEmbedder
embeddings = MistralEmbedder().get_embedding("The quick brown fox jumps over the lazy dog.")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="mistral_embeddings",
embedder=MistralEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| ---------------- | -------------------------- | ----------------- | -------------------------------------------------------------------------- |
| `model` | `str` | `"mistral-embed"` | The name of the model used for generating embeddings. |
| `dimensions` | `int` | `1024` | The dimensionality of the embeddings generated by the model. |
| `request_params` | `Optional[Dict[str, Any]]` | - | Additional parameters to include in the API request. Optional. |
| `api_key` | `str` | - | The API key used for authenticating requests. |
| `endpoint` | `str` | - | The endpoint URL for the API requests. |
| `max_retries` | `Optional[int]` | - | The maximum number of retries for API requests. Optional. |
| `timeout` | `Optional[int]` | - | The timeout duration for API requests. Optional. |
| `client_params` | `Optional[Dict[str, Any]]` | - | Additional parameters for configuring the API client. Optional. |
| `mistral_client` | `Optional[MistralClient]` | - | An instance of the MistralClient to use for making API requests. Optional. |
# Ollama Embedder
Source: https://docs.phidata.com/embedder/ollama
The `OllamaEmbedder` can be used to embed text data into vectors locally using Ollama.
The model used for generating embeddings needs to run locally.
## Usage
```python cookbook/embedders/ollama_embedder.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.ollama import OllamaEmbedder
embeddings = OllamaEmbedder().get_embedding("The quick brown fox jumps over the lazy dog.")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="ollama_embeddings",
embedder=OllamaEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| --------------- | -------------------------- | -------------- | ------------------------------------------------------------------------- |
| `model` | `str` | `"openhermes"` | The name of the model used for generating embeddings. |
| `dimensions` | `int` | `4096` | The dimensionality of the embeddings generated by the model. |
| `host` | `str` | - | The host address for the API endpoint. |
| `timeout` | `Any` | - | The timeout duration for API requests. |
| `options` | `Any` | - | Additional options for configuring the API request. |
| `client_kwargs` | `Optional[Dict[str, Any]]` | - | Additional keyword arguments for configuring the API client. Optional. |
| `ollama_client` | `Optional[OllamaClient]` | - | An instance of the OllamaClient to use for making API requests. Optional. |
# OpenAI Embedder
Source: https://docs.phidata.com/embedder/openai
Phidata uses `OpenAIEmbedder` as the default embeder for the vector database. The `OpenAIEmbedder` class is used to embed text data into vectors using the OpenAI API. Get your key from [here](https://platform.openai.com/api-keys).
## Usage
```python cookbook/embedders/openai_embedder.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.openai import OpenAIEmbedder
embeddings = OpenAIEmbedder().get_embedding("Embed me")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="openai_embeddings",
embedder=OpenAIEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| ----------------- | ---------------------------- | -------------------------- | -------------------------------------------------------------------------------- |
| `model` | `str` | `"text-embedding-ada-002"` | The name of the model used for generating embeddings. |
| `dimensions` | `int` | `1536` | The dimensionality of the embeddings generated by the model. |
| `encoding_format` | `Literal['float', 'base64']` | `"float"` | The format in which the embeddings are encoded. Options are "float" or "base64". |
| `user` | `str` | - | The user associated with the API request. |
| `api_key` | `str` | - | The API key used for authenticating requests. |
| `organization` | `str` | - | The organization associated with the API request. |
| `base_url` | `str` | - | The base URL for the API endpoint. |
| `request_params` | `Optional[Dict[str, Any]]` | - | Additional parameters to include in the API request. |
| `client_params` | `Optional[Dict[str, Any]]` | - | Additional parameters for configuring the API client. |
| `openai_client` | `Optional[OpenAIClient]` | - | An instance of the OpenAIClient to use for making API requests. |
# Qdrant FastEmbed Embedder
Source: https://docs.phidata.com/embedder/qdrant_fastembed
The `FastEmbedEmbedder` class is used to embed text data into vectors using the [FastEmbed](https://qdrant.github.io/fastembed/).
## Usage
```python cookbook/embedders/qdrant_fastembed.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.fastembed import FastEmbedEmbedder
embeddings = FastEmbedEmbedder().get_embedding("The quick brown fox jumps over the lazy dog.")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="qdrant_embeddings",
embedder=FastEmbedEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| ------------ | ----- | ------------------------ | ---------------------------------------------- |
| `dimensions` | `int` | - | The dimensionality of the generated embeddings |
| `model` | `str` | `BAAI/bge-small-en-v1.5` | The name of the qdrant\_fastembed model to use |
# SentenceTransformers Embedder
Source: https://docs.phidata.com/embedder/sentencetransformers
The `SentenceTransformerEmbedder` class is used to embed text data into vectors using the [SentenceTransformers](https://www.sbert.net/) library.
## Usage
```python cookbook/embedders/sentence_transformer_embedder.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.sentence_transformer import SentenceTransformerEmbedder
embeddings = SentenceTransformerEmbedder().get_embedding("The quick brown fox jumps over the lazy dog.")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="sentence_transformer_embeddings",
embedder=SentenceTransformerEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| ----------------------------- | ------------------ | ------------------- | ------------------------------------------------------------ |
| `dimensions` | `int` | - | The dimensionality of the generated embeddings |
| `model` | `str` | `all-mpnet-base-v2` | The name of the SentenceTransformers model to use |
| `sentence_transformer_client` | `Optional[Client]` | - | Optional pre-configured SentenceTransformers client instance |
# Together Embedder
Source: https://docs.phidata.com/embedder/together
The `TogetherEmbedder` can be used to embed text data into vectors using the Together API. Together uses the OpenAI API specification, so the `TogetherEmbedder` class is similar to the `OpenAIEmbedder` class, incorporating adjustments to ensure compatibility with the Together platform. Get your key from [here](https://api.together.xyz/settings/api-keys).
## Usage
```python cookbook/embedders/together_embedder.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.together import TogetherEmbedder
embeddings = TogetherEmbedder().get_embedding("The quick brown fox jumps over the lazy dog.")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="together_embeddings",
embedder=TogetherEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| ------------ | ----- | ---------------------------------------- | ------------------------------------------------------------ |
| `model` | `str` | `"nomic-ai/nomic-embed-text-v1.5"` | The name of the model used for generating embeddings. |
| `dimensions` | `int` | `768` | The dimensionality of the embeddings generated by the model. |
| `api_key` | `str` | | The API key used for authenticating requests. |
| `base_url` | `str` | `"https://api.Together.ai/inference/v1"` | The base URL for the API endpoint. |
# Voyage AI Embedder
Source: https://docs.phidata.com/embedder/voyageai
The `VoyageAIEmbedder` class is used to embed text data into vectors using the Voyage AI API. Get your key from [here](https://dash.voyageai.com/api-keys).
## Usage
```python cookbook/embedders/voyageai_embedder.py
from phi.agent import AgentKnowledge
from phi.vectordb.pgvector import PgVector
from phi.embedder.voyageai import VoyageAIEmbedder
embeddings = VoyageAIEmbedder().get_embedding("The quick brown fox jumps over the lazy dog.")
# Print the embeddings and their dimensions
print(f"Embeddings: {embeddings[:5]}")
print(f"Dimensions: {len(embeddings)}")
# Example usage:
knowledge_base = AgentKnowledge(
vector_db=PgVector(
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
table_name="voyageai_embeddings",
embedder=VoyageAIEmbedder(),
),
num_documents=2,
)
```
## Params
| Parameter | Type | Default | Description |
| ---------------- | -------------------------- | ------------------------------------------ | ------------------------------------------------------------------- |
| `model` | `str` | `"voyage-2"` | The name of the model used for generating embeddings. |
| `dimensions` | `int` | `1024` | The dimensionality of the embeddings generated by the model. |
| `request_params` | `Optional[Dict[str, Any]]` | - | Additional parameters to include in the API request. Optional. |
| `api_key` | `str` | - | The API key used for authenticating requests. |
| `base_url` | `str` | `"https://api.voyageai.com/v1/embeddings"` | The base URL for the API endpoint. |
| `max_retries` | `Optional[int]` | - | The maximum number of retries for API requests. Optional. |
| `timeout` | `Optional[float]` | - | The timeout duration for API requests. Optional. |
| `client_params` | `Optional[Dict[str, Any]]` | - | Additional parameters for configuring the API client. Optional. |
| `voyage_client` | `Optional[Client]` | - | An instance of the Client to use for making API requests. Optional. |
# Agent Team
Source: https://docs.phidata.com/examples/agents/agent-team
Create a file `agent_team.py` with the following code:
```python agent_team.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.duckduckgo import DuckDuckGo
web_agent = Agent(
name="Web Agent",
role="Search the web for information",
model=OpenAIChat(id="gpt-4o"),
tools=[DuckDuckGo()],
instructions=["Always include sources"],
show_tool_calls=True,
markdown=True,
)
finance_agent = Agent(
name="Finance Agent",
role="Get financial data",
model=OpenAIChat(id="gpt-4o"),
tools=[DuckDuckGo()],
instructions=["Use tables to display data"],
show_tool_calls=True,
markdown=True,
)
agent_team = Agent(
team=[web_agent, finance_agent],
instructions=["Always include sources", "Use tables to display data"],
show_tool_calls=True,
markdown=True,
)
agent_team.print_response("Summarize analyst recommendations and share the latest news for NVDA", stream=True)
```
## Usage
`bash pip install openai duckduckgo-search phidata `
`bash python agent_team.py `
# Baidu Search Agent
Source: https://docs.phidata.com/examples/agents/baidu-search-agent
**BaiduSearch** enables an Agent to perform web searches using the Baidu search engine and retrieve structured results.
Create a file `baidusearch_agent.py` with the following code:
```python baidusearch_agent.py
from phi.agent import Agent
from phi.tools.baidusearch import BaiduSearch
agent = Agent(
tools=[BaiduSearch()],
description="You are a search agent that helps users find the most relevant information using Baidu.",
instructions=[
"Given a topic by the user, respond with the 3 most relevant search results about that topic.",
"Search for 5 results and select the top 3 unique items.",
"Search in both English and Chinese.",
],
)
agent.print_response("What are the latest advancements in AI?", markdown=True)
```
## Usage
```bash
pip install openai baidusearch pycountry
```
```bash
python baidusearch_agent.py
```
# Books Recommendation Agent
Source: https://docs.phidata.com/examples/agents/books-recommendation-agent
## Overview
The Book Recommendation Agent, Shelfie, provides personalized, diverse, and thoughtful book suggestions based on user preferences and interests.
## Implementation
Create a file `books_recommendation_agent.py` with the following code:
```python books_recommendation_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.exa import ExaTools
agent = Agent(
description="you help user with book recommendations",
name="Shelfie",
model=OpenAIChat(id="gpt-4o"),
instructions=[
"You are a highly knowledgeable book recommendation agent.",
"Your goal is to help the user discover books based on their preferences, reading history, and interests.",
"If the user mentions a specific genre, suggest books that span both classics and modern hits.",
"When the user mentions an author, recommend similar authors or series they may enjoy.",
"Highlight notable accomplishments of the book, such as awards, best-seller status, or critical acclaim.",
"Provide a short summary or teaser for each book recommended.",
"Offer up to 5 book recommendations for each request, ensuring they are diverse and relevant.",
"Leverage online resources like Goodreads, StoryGraph, and LibraryThing for accurate and varied suggestions.",
"Focus on being concise, relevant, and thoughtful in your recommendations.",
],
tools=[ExaTools()],
)
agent.print_response(
"I really found anxious people and lessons in chemistry interesting, can you suggest me more such books"
)
```
## Usage
```bash
pip install phidata openai exa_py
```
```bash
export OPENAI_API_KEY=****
export EXA_API_KEY=****
```
```bash
python books_recommendation_agent.py
```
# Cal.com Agent
Source: https://docs.phidata.com/examples/agents/calcom-agent
Cal.com is a scheduling tool that allows you to schedule meetings with your team.
Create a file `calcom_agent.py` with the following code:
```python calcom_agent.py
agent = Agent(
name="Calendar Assistant",
instructions=[
f"You're scheduing assistant. Today is {datetime.now()}.",
"You can help users by:",
"- Finding available time slots",
"- Creating new bookings",
"- Managing existing bookings (view, reschedule, cancel) ",
"- Getting booking details",
"- IMPORTANT: In case of rescheduling or cancelling booking, call the get_upcoming_bookings function to get the booking uid. check available slots before making a booking for given time",
"Always confirm important details before making bookings or changes.",
],
model=OpenAIChat(id="gpt-4"),
tools=[CalCom(user_timezone="America/New_York")],
show_tool_calls=True,
markdown=True,
)
agent.print_response("What are my bookings for tomorrow?")
```
## Usage
```bash
pip install requests pytz
```
```bash
export CALCOM_API_KEY="your_api_key"
export CALCOM_EVENT_TYPE_ID="your_event_type_id"
```
```bash
python calcom_agent.py
```
# Data Analyst
Source: https://docs.phidata.com/examples/agents/data-analyst
Create a file `data_analyst.py` with the following code:
```python data_analyst.py
import json
from phi.model.openai import OpenAIChat
from phi.agent.duckdb import DuckDbAgent
data_analyst = DuckDbAgent(
model=OpenAIChat(model="gpt-4o"),
semantic_model=json.dumps(
{
"tables": [
{
"name": "movies",
"description": "Contains information about movies from IMDB.",
"path": "https://phidata-public.s3.amazonaws.com/demo_data/IMDB-Movie-Data.csv",
}
]
}
),
markdown=True,
)
data_analyst.print_response(
"Show me a histogram of ratings. "
"Choose an appropriate bucket size but share how you chose it. "
"Show me the result as a pretty ascii diagram",
stream=True,
)
```
## Usage
```bash
pip install openai duckdb phidata
```
```bash
python data_analyst.py
```
# Discord Agent
Source: https://docs.phidata.com/examples/agents/discord-agent
Discord is a popular messaging platform that allows you to interact with your friends, family, and colleagues.
Create a file `discord_agent.py` with the following code:
```python discord_agent.py
import os
from phi.agent import Agent
from phi.tools.discord_tools import DiscordTools
# Create an agent with Discord tools
discord_agent = Agent(
name="Discord Agent",
instructions=[
"You are a Discord bot that can perform various operations.",
"You can send messages, read message history, manage channels, and delete messages.",
],
tools=[DiscordTools()],
)
# Replace with your Discord IDs
channel_id = "YOUR_CHANNEL_ID"
server_id = "YOUR_SERVER_ID"
# Example 1: Send a message
discord_agent.print_response(f"Send a warm message to channel {channel_id}", stream=True)
# Example 2: Get channel info
discord_agent.print_response(f"Get information about channel {channel_id}", stream=True)
# Example 3: List channels
discord_agent.print_response(f"List all channels in server {server_id}", stream=True)
```
## Usage
```bash
pip install phidata
```
```bash
export DISCORD_BOT_TOKEN=****
```
```bash
python discord_agent.py
```
# Firecrawl Agent
Source: https://docs.phidata.com/examples/agents/firecrawl-agent
Firecrawl is a tool that allows you to search the web using Firecrawl.
Create a file `firecrawl_agent.py` with the following code:
```python firecrawl_agent.py
from phi.agent import Agent
from phi.tools.firecrawl import FirecrawlTools
agent = Agent(tools=[FirecrawlTools(scrape=False, crawl=True)], show_tool_calls=True, markdown=True)
agent.print_response("Summarize this https://finance.yahoo.com/")
```
## Usage
```bash
pip install firecrawl-py
```
```bash
export FIRECRAWL_API_KEY=****
```
```bash
python firecrawl_agent.py
```
# Generate Image Agent
Source: https://docs.phidata.com/examples/agents/generate-image-agent
Create a file `generate_image_agent.py` with the following code:
```python generate_image_agent.py
from phi.agent import Agent
from phi.tools.dalle import Dalle
from phi.model.openai import OpenAIChat
image_agent = Agent(
model=OpenAIChat(id="gpt-4o"),
tools=[Dalle()],
description="You are an AI agent that can generate images using DALL-E.",
instructions="When the user asks you to create an image, use the `create_image` tool to create the image.",
markdown=True,
show_tool_calls=True,
)
image_agent.print_response("Generate an image of a white siamese cat")
images = image_agent.get_images()
if images and isinstance(images, list):
for image_response in images:
image_data = image_response.get("data") # type: ignore
if image_data:
for image in image_data:
image_url = image.get("url") # type: ignore
if image_url:
print(image_url)
```
## Usage
```bash
pip install openai phidata
```
```bash
python generate_image_agent.py
```
Open the image URL in your browser to view the image.
# Github Agent
Source: https://docs.phidata.com/examples/agents/github-agent
Github is a popular code hosting platform that allows you to collaborate with your team.
Create a file `github_agent.py` with the following code:
```python github_agent.py
from phi.agent import Agent
from phi.tools.github import GithubTools
agent = Agent(
instructions=[
"Use your tools to answer questions about the repo: agno-agi/phidata",
"Do not create any issues or pull requests unless explicitly asked to do so",
],
tools=[GithubTools(base_url="enter_base_url_here")],
)
agent.print_response("List open pull requests", markdown=True)
```
## Usage
```bash
pip install PyGithub
```
```bash
export GITHUB_ACCESS_TOKEN=****
```
```bash
python github_agent.py
```
# Globe Hopper Agent
Source: https://docs.phidata.com/examples/agents/globe-hopper-agent
**Globe Hopper** enables an Agent to plan travel itineraries, recommend flights, hotels, and activities.
Create a file `globe_hopper_agent.py` with the following code:
```python globe_hopper_agent.py
from phi.model.openai import OpenAIChat
from phi.agent import Agent
from phi.tools.exa import ExaTools
globe_hopper_agent = Agent(
name="Globe Hopper",
model=OpenAIChat(id="gpt-4o"),
tools=[ExaTools()],
markdown=True,
description="You are an expert itinerary planning agent. Your role is to assist users in creating detailed, customized travel plans tailored to their preferences and needs.",
instructions=[
"Use Exa to search and extract relevant data from reputable travel platforms.",
"Collect information on flights, accommodations, local attractions, and estimated costs from these sources.",
"Ensure that the gathered data is accurate and tailored to the user's preferences, such as destination, group size, and budget constraints.",
"Create a clear and concise itinerary that includes: detailed day-by-day travel plan, suggested transportation and accommodation options, activity recommendations (e.g., sightseeing, dining, events), an estimated cost breakdown (covering transportation, accommodation, food, and activities).",
"If a particular website or travel option is unavailable, provide alternatives from other trusted sources.",
"Do not include direct links to external websites or booking platforms in the response."
],
)
globe_hopper_agent.print_response(
"I want to plan an offsite for 14 people for 3 days (28th-30th March) in London within 10k dollars. Please suggest options for places to stay, activities, and co working spaces and a detailed itinerary for the 3 days with transportation and activities",
stream=True,
)
```
## Usage
```bash
pip install openai exa_py
```
```bash
export OPENAI_API_KEY=****
export EXA_API_KEY=****
```
```bash
python globe_hopper_agent.py
```
# Image Agent
Source: https://docs.phidata.com/examples/agents/image-agent
Create a file `image_agent.py` with the following code:
```python image_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
markdown=True,
)
agent.print_response(
"What are in these images? Is there any difference between them?",
images=[
"https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg",
"https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg",
],
)
```
## Usage
```bash
pip install openai phidata
```
```bash
python image_agent.py
```
# Image to Text Agent
Source: https://docs.phidata.com/examples/agents/image-to-text
Create a file `image_to_text.py` with the following code:
```python image_to_text.py
from pathlib import Path
from phi.agent import Agent
from phi.model.openai import OpenAIChat
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
markdown=True,
)
image_path = Path(__file__).parent.joinpath("multimodal-agents.jpg")
agent.print_response(
"Write a 3 sentence fiction story about the image",
images=[str(image_path)],
)
```
## Usage
```bash
pip install openai phidata
```
```bash
python image_to_text.py
```
# ModelsLabs Agent
Source: https://docs.phidata.com/examples/agents/models-labs-agent
ModelsLabs is a video generation tool that allows you to generate videos based on a text prompt.
Create a file `models_labs_agent.py` with the following code:
```python models_labs_agent.py
from phi.agent import Agent
from phi.tools.models_labs import ModelsLabs
# Create an Agent with the ModelsLabs tool
agent = Agent(tools=[ModelsLabs()], name="ModelsLabs Agent")
agent.print_response("Generate a video of a beautiful sunset over the ocean", markdown=True)
```
## Usage
```bash
pip install requests
```
```bash
export MODELS_LAB_API_KEY=****
```
```bash
python models_labs_agent.py
```
# Popcorn Pal
Source: https://docs.phidata.com/examples/agents/popcorn-pal-agent
**Popcorn Pal** is a movie recommendation agent that searches and scrapes movie websites to provide detailed recommendations, including ratings, genres, descriptions, trailers, and upcoming releases.
Create a file `popcorn_pal_agent.py` with the following code:
```python popcorn_pal_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.exa import ExaTools
popcorn_pal_agent = Agent(
name="Popcorn Pal",
tools=[
ExaTools(),
],
model=OpenAIChat(id="gpt-4o"),
description=(
"You are Popcorn Pal, a movie recommendation agent that searches and scrapes movie websites to provide detailed recommendations, "
"including ratings, genres, descriptions, trailers, and upcoming releases."
),
instructions=[
"Use Exa to search for the movies.",
"Provide results with the following details: movie title, genre, movies with good ratings, description, recommended viewing age, primary language,runtime, imdb rating and release date.",
"Include trailers for movies similar to the recommendations and upcoming movies of the same genre or from related directors/actors.",
"Give atleast 5 movie recommendations for each query",
"Present the output in a well-structured markdown table for readability.",
"Ensure all movie data is correct, especially for recent or upcoming releases.",
],
markdown=True,
)
popcorn_pal_agent.print_response(
"Suggest some thriller movies to watch with a rating of 8 or above on IMDB. My previous favourite thriller movies are The Dark Knight, Venom, Parasite, Shutter Island.",
stream=True,
)
```
## Usage
```bash
pip install openai exa_py
```
```bash
export OPENAI_API_KEY=****
export EXA_API_KEY=****
```
```bash
python popcorn_pal_agent.py
```
# Python Agent
Source: https://docs.phidata.com/examples/agents/python-agent
Create a file `python_agent.py` with the following code:
```python python_agent.py
from pathlib import Path
from phi.agent.python import PythonAgent
from phi.model.openai import OpenAIChat
from phi.file.local.csv import CsvFile
cwd = Path(__file__).parent.resolve()
tmp = cwd.joinpath("tmp")
if not tmp.exists():
tmp.mkdir(exist_ok=True, parents=True)
python_agent = PythonAgent(
model=OpenAIChat(id="gpt-4o"),
base_dir=tmp,
files=[
CsvFile(
path="https://phidata-public.s3.amazonaws.com/demo_data/IMDB-Movie-Data.csv",
description="Contains information about movies from IMDB.",
)
],
markdown=True,
pip_install=True,
show_tool_calls=True,
)
python_agent.print_response("What is the average rating of movies?")
```
## Usage
```bash
pip install openai phidata
```
```bash
python python_agent.py
```
# Python Function Agent
Source: https://docs.phidata.com/examples/agents/python-function-agent
Create a file `python_function_agent.py` with the following code:
```python python_function_agent.py
import json
import httpx
from phi.agent import Agent
def get_top_hackernews_stories(num_stories: int = 10) -> str:
"""Use this function to get top stories from Hacker News.
Args:
num_stories (int): Number of stories to return. Defaults to 10.
Returns:
str: JSON string of top stories.
"""
# Fetch top story IDs
response = httpx.get("https://hacker-news.firebaseio.com/v0/topstories.json")
story_ids = response.json()
# Fetch story details
stories = []
for story_id in story_ids[:num_stories]:
story_response = httpx.get(f"https://hacker-news.firebaseio.com/v0/item/{story_id}.json")
story = story_response.json()
if "text" in story:
story.pop("text", None)
stories.append(story)
return json.dumps(stories)
agent = Agent(tools=[get_top_hackernews_stories], show_tool_calls=True, markdown=True)
agent.print_response("Summarize the top 5 stories on hackernews?", stream=True)
```
## Usage
```bash
pip install openai phidata
```
```bash
python python_function_agent.py
```
# RAG Agent
Source: https://docs.phidata.com/examples/agents/rag-agent
RAG (Retrieval-Augmented Generation) is a technique that allows you to use a knowledge base to answer questions.
Create a file `rag_agent.py` with the following code:
```python rag_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.embedder.openai import OpenAIEmbedder
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.lancedb import LanceDb, SearchType
# Create a knowledge base from a PDF
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
# Use LanceDB as the vector database
vector_db=LanceDb(
table_name="recipes",
uri="tmp/lancedb",
search_type=SearchType.vector,
embedder=OpenAIEmbedder(model="text-embedding-3-small"),
),
)
# Comment out after first run as the knowledge base is loaded
knowledge_base.load(recreate=False)
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
# Add the knowledge base to the agent
knowledge=knowledge_base,
show_tool_calls=True,
markdown=True,
)
agent.print_response("How do I make chicken and galangal in coconut milk soup", stream=True)
```
## Usage
```bash
pip install openai lancedb tantivy pypdf sqlalchemy
```
```bash
python rag_agent.py
```
# Reasoning Agent
Source: https://docs.phidata.com/examples/agents/reasoning-agent
Create a file `reasoning_agent.py` with the following code:
```python reasoning_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
task = (
"Three missionaries and three cannibals need to cross a river. "
"They have a boat that can carry up to two people at a time. "
"If, at any time, the cannibals outnumber the missionaries on either side of the river, the cannibals will eat the missionaries. "
"How can all six people get across the river safely? Provide a step-by-step solution and show the solutions as an ascii diagram"
)
reasoning_agent = Agent(model=OpenAIChat(id="gpt-4o"), reasoning=True, markdown=True, structured_outputs=True)
reasoning_agent.print_response(task, stream=True, show_full_reasoning=True)
```
## Usage
```bash
pip install openai phidata
```
```bash
python reasoning_agent.py
```
# AI Recipe Creator Agent
Source: https://docs.phidata.com/examples/agents/recipe-creator-agent
## Overview
The Recipe Agent generates personalized recipe recommendations based on user inputs like ingredients, time, and dietary preferences. It relies on two recipe PDFs stored in a PgVector-powered knowledgebase for fast and efficient searches, then enhances suggestions with web searches using ExaTools.
## Implementation
Create a file `ai_recipe_creator_agent.py` with the following code:
```python ai_recipe_creator_agent.py
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector
from phi.tools.exa import ExaTools
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=[
"https://www.poshantracker.in/pdf/Awareness/MilletsRecipeBook2023_Low%20Res_V5.pdf",
"https://www.cardiff.ac.uk/__data/assets/pdf_file/0003/123681/Recipe-Book.pdf",
],
vector_db=PgVector(table_name="recipes", db_url=db_url), # we are using PgVector here, you can also use other vector dbs
)
knowledge_base.load(recreate=False)
recipe_agent = Agent(
name="RecipeGenie",
knowledge_base=knowledge_base,
search_knowledge=True,
tools=[ExaTools()],
markdown=True,
instructions=[
"Search for recipes based on the ingredients and time available from the knowledge base.",
"Include the exact calories, preparation time, cooking instructions, and highlight allergens for the recommended recipes.",
"Always search exa for recipe links or tips related to the recipes apart from knowledge base.",
"Provide a list of recipes that match the user's requirements and preferences.",
],
)
recipe_agent.print_response(
"I have potatoes, tomatoes, onions, garlic, ginger, and chicken. Suggest me a quick recipe for dinner", stream=True
)
```
## Usage
```bash
pip install phidata openai duckdb exa_py pypdf packaging
pip install sqlalchemy pgvector
pip install -U "psycopg[binary]"
```
```bash
export OPENAI_API_KEY=****
export EXA_API_KEY=****
```
```bash
docker run -d \
-e POSTGRES_DB=ai \
-e POSTGRES_USER=ai \
-e POSTGRES_PASSWORD=ai \
-e PGDATA=/var/lib/postgresql/data/pgdata \
-v pgvolume:/var/lib/postgresql/data \
-p 5532:5432 \
--name pgvector \
phidata/pgvector:16
```
```bash
python ai_recipe_creator_agent.py
```
# Research Agent
Source: https://docs.phidata.com/examples/agents/research-agent
Create a file `research_agent.py` with the following code:
```python rag_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.duckduckgo import DuckDuckGo
from phi.tools.newspaper4k import Newspaper4k
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
tools=[DuckDuckGo(), Newspaper4k()],
description="You are a senior NYT researcher writing an article on a topic.",
instructions=[
"For a given topic, search for the top 5 links.",
"Then read each URL and extract the article text, if a URL isn't available, ignore it.",
"Analyse and prepare an NYT worthy article based on the information.",
],
markdown=True,
show_tool_calls=True,
add_datetime_to_instructions=True,
# debug_mode=True,
)
agent.print_response("Simulation theory", stream=True)
```
## Usage
```bash
pip install openai duckduckgo-search newspaper4k lxml_html_clean phidata
```
```bash
python research_agent.py
```
# Shopping Agent
Source: https://docs.phidata.com/examples/agents/shopping-partner-agent
## Overview
The Shopping Partner Agent is a personalized product recommendation agent that helps users find items matching their preferences and needs. It uses FirecrawlTools to search trusted e-commerce platforms, ensuring recommendations are accurate, in stock, and sourced from reliable websites.
## Implementation
Create a file `shopping_agent.py` with the following code:
```python shopping_agent.py
from phi.agent import Agent
from phi.model.google import Gemini
from phi.tools.firecrawl import FirecrawlTools
agent = Agent(
name="shopping partner",
model=Gemini(id="gemini-2.0-flash-exp"),
instructions=[
"You are a product recommender agent specializing in finding products that match user preferences.",
"Prioritize finding products that satisfy as many user requirements as possible, but ensure a minimum match of 50%.",
"Search for products only from authentic and trusted e-commerce websites such as Google Shopping, Amazon, Flipkart, Myntra, Meesho, Nike, and other reputable platforms.",
"Verify that each product recommendation is in stock and available for purchase.",
"Avoid suggesting counterfeit or unverified products.",
"Clearly mention the key attributes of each product (e.g., price, brand, features) in the response.",
"Format the recommendations neatly and ensure clarity for ease of user understanding.",
],
tools=[FirecrawlTools()],
)
agent.print_response(
"I am looking for running shoes with the following preferences: Color: Black Purpose: Comfortable for long-distance running Budget: Under Rs. 10,000"
)
```
## Usage
```bash
pip install phidata google-generativeai openai firecrawl-py
```
```bash
export GOOGLE_API_KEY=****
export FIRECRAWL_API_KEY=****
```
```bash
python shopping_agent.py
```
# Slack Agent
Source: https://docs.phidata.com/examples/agents/slack-agent
Create a file `slack_agent.py` with the following code:
```python slack_agent.py
from phi.agent import Agent
from phi.tools.slack import SlackTools
from phi.model.openai import OpenAIChat
agent = Agent(model=OpenAIChat(id="gpt-4o"), tools=[SlackTools()], show_tool_calls=True)
agent.print_response("Send a warm message to the #general channel", markdown=True)
```
## Usage
```bash
pip install openai slack-sdk phidata
```
```bash
export SLACK_TOKEN=****
```
```bash
python slack-agent.py
```
# Structured Output
Source: https://docs.phidata.com/examples/agents/structured-output
Create a file `structured_output.py` with the following code:
```python structured_output.py
from typing import List
from rich.pretty import pprint # noqa
from pydantic import BaseModel, Field
from phi.agent import Agent, RunResponse # noqa
from phi.model.openai import OpenAIChat
class MovieScript(BaseModel):
setting: str = Field(..., description="Provide a nice setting for a blockbuster movie.")
ending: str = Field(..., description="Ending of the movie. If not available, provide a happy ending.")
genre: str = Field(
..., description="Genre of the movie. If not available, select action, thriller or romantic comedy."
)
name: str = Field(..., description="Give a name to this movie")
characters: List[str] = Field(..., description="Name of characters for this movie.")
storyline: str = Field(..., description="3 sentence storyline for the movie. Make it exciting!")
# Agent that uses JSON mode
json_mode_agent = Agent(
model=OpenAIChat(id="gpt-4o"),
description="You write movie scripts.",
response_model=MovieScript,
)
# Agent that uses structured outputs
structured_output_agent = Agent(
model=OpenAIChat(id="gpt-4o-2024-08-06"),
description="You write movie scripts.",
response_model=MovieScript,
structured_outputs=True,
)
# Get the response in a variable
# json_mode_response: RunResponse = json_mode_agent.run("New York")
# pprint(json_mode_response.content)
# structured_output_response: RunResponse = structured_output_agent.run("New York")
# pprint(structured_output_response.content)
json_mode_agent.print_response("New York")
structured_output_agent.print_response("New York")
```
## Usage
```bash
pip install openai phidata
```
```bash
python structured_output.py
```
# Study Scout Agent
Source: https://docs.phidata.com/examples/agents/study-scout-agent
Study Scout Agent is an agent that can help you learn about a topic with a detailed study plan and resources.
Create a file `study_scout_agent.py` with the following code:
```python study_scout_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.youtube_tools import YouTubeTools
from phi.tools.exa import ExaTools
study_partner = Agent(
name="StudyScout", # Fixed typo in name
model=OpenAIChat(id="gpt-4o"),
tools=[ExaTools(), YouTubeTools()],
markdown=True,
description="You are a study partner who assists users in finding resources, answering questions, and providing explanations on various topics.",
instructions=[
"Use Exa to search for relevant information on the given topic and verify information from multiple reliable sources.",
"Break down complex topics into digestible chunks and provide step-by-step explanations with practical examples.",
"Share curated learning resources including documentation, tutorials, articles, research papers, and community discussions.",
"Recommend high-quality YouTube videos and online courses that match the user's learning style and proficiency level.",
"Suggest hands-on projects and exercises to reinforce learning, ranging from beginner to advanced difficulty.",
"Create personalized study plans with clear milestones, deadlines, and progress tracking.",
"Provide tips for effective learning techniques, time management, and maintaining motivation.",
"Recommend relevant communities, forums, and study groups for peer learning and networking.",
],
)
study_partner.print_response(
"I want to learn about Postgres in depth. I know the basics, have 2 weeks to learn, and can spend 3 hours daily. Please share some resources and a study plan.",
stream=True,
)
```
## Usage
```bash
pip install phi openai exa_py
```
```bash
export EXA_API_KEY=****
```
```bash
python study_scout_agent.py
```
# Weekend Planner Agent
Source: https://docs.phidata.com/examples/agents/timeout-agent
## Overview
The Weekend Planner Agent, TimeOut, creates personalized itineraries with events, activities, and dining options tailored to the user’s preferences and location.
## Implementation
Create a file `weekend_planner_agent.py` with the following code:
```python weekend_planner_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.exa import ExaTools
agent = Agent(
description="you help the user plan their weekends",
name="TimeOut",
model=OpenAIChat(id="gpt-4o"),
instructions=[
"You are a weekend planning assistant that helps users create a personalized weekend itinerary.",
"Always mention the timeframe, location, and year provided by the user (e.g., '16–17 December 2023 in Bangalore'). Recommendations should align with the specified dates.",
"Provide responses in these sections: Events, Activities, Dining Options.",
"- **Events**: Include name, date, time, location, a brief description, and booking links from platforms like BookMyShow or Insider.in.",
"- **Activities**: Suggest engaging options with estimated time required, location, and additional tips (e.g., best time to visit).",
"- **Dining Options**: Recommend restaurants or cafés with cuisine highlights and links to platforms like Zomato or Google Maps.",
"Ensure all recommendations are for the current or future dates relevant to the query. Avoid past events.",
"If no specific data is available for the dates, suggest general activities or evergreen attractions in the city.",
"Keep responses concise, clear, and formatted for easy reading.",
],
tools=[ExaTools()],
)
agent.print_response(
"I want to plan my coming weekend filled with fun activities and christmas themed activities in Bangalore for 21 and 22 Dec 2024."
)
```
## Usage
```bash
pip install phidata openai exa_py
```
```bash
export OPENAI_API_KEY=****
export EXA_API_KEY=****
```
```bash
python weekend_planner_agent.py
```
# Web Search Agent
Source: https://docs.phidata.com/examples/agents/web-search
Create a file `web_search.py` with the following code:
```python web_search.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.duckduckgo import DuckDuckGo
web_agent = Agent(
name="Web Agent",
model=OpenAIChat(id="gpt-4o"),
tools=[DuckDuckGo()],
instructions=["Always include sources"],
show_tool_calls=True,
markdown=True,
)
web_agent.print_response("Whats happening in France?", stream=True)
```
## Usage
```bash
pip install openai duckduckgo-search phidata
```
```bash
python web_search.py
```
# Youtube Timestamp Agent
Source: https://docs.phidata.com/examples/agents/youtube-timestamp-agent
Youtube Timestamp Agent is an agent that can extract the timestamp from a Youtube video.
Create a file `youtube_timestamp_agent.py` with the following code:
```python youtube_timestamp_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.youtube_tools import YouTubeTools
agent = Agent(
name="YouTube Timestamps Agent",
model=OpenAIChat(id="gpt-4o"),
tools=[YouTubeTools()],
show_tool_calls=True,
instructions=[
"You are a YouTube agent. First check the length of the video. Then get the detailed timestamps for a YouTube video corresponding to correct timestamps.",
"Don't hallucinate timestamps.",
"Make sure to return the timestamps in the format of `[start_time, end_time, summary]`.",
],
)
agent.print_response(
"Get the detailed timestamps for this video https://www.youtube.com/watch?v=M5tx7VI-LFA", markdown=True
)
```
## Usage
```bash
pip install openai youtube_transcript_api
```
```bash
python youtube_timestamp_agent.py
```
# Clone Cookbook
Source: https://docs.phidata.com/examples/how-to/use-cookbook
The [phidata cookbook](https://github.com/agno-agi/phidata/tree/main/cookbook) contains in-depth examples and code. From basic **agents, function calling, structured output** to advanced **fine-tuning and evaluations**.
## Clone the cookbook
We recommend forking the [phidata](https://github.com/agno-agi/phidata) repo first so you can customize the cookbooks, and contribute your own recipes back to the repo.
Fork & clone the [phidata](https://github.com/agno-agi/phidata) repo
```bash
git clone https://github.com/agno-agi/phidata
```
`cd` into the `phidata` directory
```bash
cd phidata
```
Create a virtual environment with the required libraries and install the project in editable mode. You can use a helper script or run these steps manually.
```bash Mac
./scripts/create_venv.sh
source phienv/bin/activate
```
```bash Manual (Mac)
python3 -m venv phienv
source phienv/bin/activate
pip install -r requirements.txt
pip install --editable .
```
```bash Windows
python3 -m venv phienv
phienv/scripts/activate
pip install -r requirements.txt
pip install --editable .
```
Set your `OPENAI_API_KEY`
```bash Mac
export OPENAI_API_KEY=sk-***
```
```bash Windows
setx OPENAI_API_KEY sk-***
```
Install `openai` and `duckduckgo-search`
```bash
pip install openai duckduckgo-search
```
Run the `agents/web_search.py` recipe
```bash
python cookbook/agents/01_web_search.py
```
# ChromaDB Integration
Source: https://docs.phidata.com/examples/integrations/chroma
## Example
```python
import typer
from rich.prompt import Prompt
from typing import Optional
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.chroma import ChromaDb
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=ChromaDb(collection="recipes"),
)
# Comment out after first run
knowledge_base.load(recreate=False)
def pdf_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge_base=knowledge_base,
use_tools=True,
show_tool_calls=True,
debug_mode=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if __name__ == "__main__":
typer.run(pdf_agent)
```
## Usage
```bash
pip install -U chromadb pypdf openai phidata
```
```bash Mac
python cookbook/integrations/chromadb/agent.py
```
```bash Windows
python cookbook/integrations/chromadb/agent.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/integrations/chromadb/agent.py)
# Composio
Source: https://docs.phidata.com/examples/integrations/composio
[**ComposioTools**](https://docs.composio.dev/framework/phidata) enables an Agent to work with sofware tools like Gmail, Salesforce, Github, etc.
## Example
The following agent will use Github Tool from Composio Toolkit to star a repo.
```bash Run the following commands to setup the agent
pip install composio-phidata
composio add github # Launches GitHub login in browser
```
```python
from phi.agent import Agent
from composio_phidata import Action, ComposioToolSet
toolset = ComposioToolSet()
composio_tools = toolset.get_tools(
actions=[Action.GITHUB_STAR_A_REPOSITORY_FOR_THE_AUTHENTICATED_USER]
) # get starring action for Github
agent = Agent(tools=composio_tools, show_tool_calls=True)
agent.print_response("Can you star agno-agi/phidata repo?")
```
## Toolkit Params
The following parameters are used when calling the GitHub star repository action:
| Parameter | Type | Default | Description |
| --------- | ----- | ------- | ------------------------------------ |
| `owner` | `str` | - | The owner of the repository to star. |
| `repo` | `str` | - | The name of the repository to star. |
## Toolkit Functions
Composio Toolkit provides 1000+ functions to connect to different software tools.
Open this [link](https://composio.dev/tools) to view the complete list of functions.
# LanceDB Integration
Source: https://docs.phidata.com/examples/integrations/lancedb
## Example
```python
import typer
from typing import Optional
from rich.prompt import Prompt
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.lancedb import LanceDb
from phi.vectordb.search import SearchType
# LanceDB Vector DB
vector_db = LanceDb(
table_name="recipes",
uri="/tmp/lancedb",
search_type=SearchType.keyword,
)
# Knowledge Base
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=vector_db,
)
# Comment out after first run
knowledge_base.load(recreate=True)
def lancedb_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge=knowledge_base,
show_tool_calls=True,
debug_mode=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if __name__ == "__main__":
typer.run(lancedb_agent)
```
## Usage
```bash
pip install -U lancedb pypdf pandas openai phidata
```
```bash Mac
python cookbook/integrations/lancedb/agent.py
```
```bash Windows
python cookbook/integrations/lancedb/agent.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/integrations/lancedb/agent.py)
# PgVector
Source: https://docs.phidata.com/examples/integrations/pgvector
The PgVector Agent uses PgVector as Knowledge Base and Storage for the Agent.
```python
from phi.agent import Agent
from phi.storage.agent.postgres import PgAgentStorage
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
agent = Agent(
storage=PgAgentStorage(table_name="recipe_agent", db_url=db_url),
knowledge_base=PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector(table_name="recipe_documents", db_url=db_url),
),
# Show tool calls in the response
show_tool_calls=True,
# Enable the agent to search the knowledge base
search_knowledge=True,
# Enable the agent to read the chat history
read_chat_history=True,
)
# Comment out after first run
agent.knowledge_base.load(recreate=False) # type: ignore
agent.print_response("How do I make pad thai?", markdown=True)
```
## Usage
```bash
pip install -U pgvector pypdf "psycopg[binary]" sqlalchemy phidata
```
```bash Mac
python cookbook/integrations/pgvector/agent.py
```
```bash Windows
python cookbook/integrations/pgvector/agent.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/integrations/pgvector/agent.py)
# Pinecone Integration
Source: https://docs.phidata.com/examples/integrations/pinecone
## Example
```python
import os
import typer
from typing import Optional
from rich.prompt import Prompt
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pineconedb import PineconeDB
api_key = os.getenv("PINECONE_API_KEY")
index_name = "thai-recipe-hybrid-search"
vector_db = PineconeDB(
name=index_name,
dimension=1536,
metric="cosine",
spec={"serverless": {"cloud": "aws", "region": "us-east-1"}},
api_key=api_key,
use_hybrid_search=True,
hybrid_alpha=0.5,
)
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=vector_db,
)
# Comment out after first run
knowledge_base.load(recreate=True, upsert=True)
def pinecone_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge=knowledge_base,
show_tool_calls=True,
debug_mode=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if __name__ == "__main__":
typer.run(pinecone_agent)
```
## Usage
```bash
pip install -U pinecone pypdf openai phidata
```
```bash Mac
python cookbook/integrations/pinecone/agent.py
```
```bash Windows
python cookbook/integrations/pinecone/agent.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/integrations/pinecone/agent.py)
# Portkey
Source: https://docs.phidata.com/examples/integrations/portkey
Enhance your Phidata agents with Portkey for reliability, efficiency, and advanced features
# Portkey Integration with Phidata
 [Portkey](https://portkey.ai) is a 2-line upgrade to make your Phidata agents reliable, cost-efficient, and fast.
Portkey adds 4 core production capabilities to any Phidata agent:
1. Routing to 200+ LLMs
2. Making each LLM call more robust
3. Full-stack tracing & cost, performance analytics
4. Real-time guardrails to enforce behavior
## Getting Started
1. **Install Required Packages:**
```bash
pip install phidata portkey-ai
```
2. **Configure Phidata with Portkey:**
```python
from phi.llm.openai import OpenAIChat
from portkey_ai import PORTKEY_GATEWAY_URL, createHeaders
llm = OpenAIChat(
base_url=PORTKEY_GATEWAY_URL,
api_key="OPENAI_API_KEY", #Replace with Your OpenAI Key
default_headers=createHeaders(
provider="openai",
api_key=PORTKEY_API_KEY # Replace with your Portkey API key
)
)
```
Generate your API key in the [Portkey Dashboard](https://app.portkey.ai/).
And, that's it! With just this, you can start logging all of your Phidata requests and make them reliable.
3. **Let's Run your Agent**
```python
from phi.agent import Agent
agent = Agent(
llm=llm,
description="You help people with their health and fitness goals.",
instructions=["Recipes should be under 5 ingredients"],
)
# -*- Print a response to the client
agent.print_response("Share a breakfast recipe.", markdown=True)
```
Here's the output from your Agent's run on Portkey's dashboard.
 ## Key Features
Portkey offers a range of advanced features to enhance your Phidata agents. Here's an overview:
| Feature | Description |
| -------------------------------------------------------- | ------------------------------------------------------------------ |
| 🌐 [Multi-LLM Integration](#interoperability) | Access 200+ LLMs with simple configuration changes |
| 🛡️ [Enhanced Reliability](#reliability) | Implement fallbacks, load balancing, retries, and much more |
| 📊 [Advanced Metrics](#metrics) | Track costs, tokens, latency, and 40+ custom metrics effortlessly |
| 🔍 [Detailed Traces and Logs](#comprehensive-logging) | Gain insights into every agent action and decision |
| 🚧 [Guardrails](#guardrails) | Enforce agent behavior with real-time checks on inputs and outputs |
| 🔄 [Continuous Optimization](#continuous-improvement) | Capture user feedback for ongoing agent improvements |
| 💾 [Smart Caching](#caching) | Reduce costs and latency with built-in caching mechanisms |
| 🔐 [Enterprise-Grade Security](#security-and-compliance) | Set budget limits and implement fine-grained access controls |
## Colab Notebook
For a hands-on example of integrating Portkey with Phidata, check out our notebook:
[](https://git.new/Phidata-docs)
## Advanced Features
### Interoperability
Easily switch between **200+ LLMs** by changing the `provider` and API key in your configuration.
#### Example: Switching from OpenAI to Azure OpenAI
```python
config = [
{
"api_key": "api-key",
"model": "gpt-3.5-turbo",
"base_url": PORTKEY_GATEWAY_URL,
"api_type": "openai",
"default_headers": createHeaders(
api_key="YOUR_PORTKEY_API_KEY",
provider="azure-openai",
virtual_key="AZURE_VIRTUAL_KEY"
)
}
]
```
### Reliability
Implement fallbacks, load balancing, and automatic retries to make your agents more resilient.
```python
portkey_config = {
"retry": {
"attempts": 5
},
"strategy": {
"mode": "loadbalance" # Options: "loadbalance" or "fallback"
},
"targets": [
{
"provider": "openai",
"api_key": "OpenAI_API_Key"
},
{
"provider": "anthropic",
"api_key": "Anthropic_API_Key"
}
]
}
```
### Metrics
Agent runs are complex. Portkey automatically logs **40+ comprehensive metrics** for your AI agents, including cost, tokens used, latency, etc. Whether you need a broad overview or granular insights into your agent runs, Portkey's customizable filters provide the metrics you need.
### Comprehensive Logging
Access detailed logs and traces of agent activities, function calls, and errors. Filter logs based on multiple parameters for in-depth analysis.
 ### Guardrails
Phidata agents, while powerful, can sometimes produce unexpected or undesired outputs. Portkey's Guardrails feature helps enforce agent behavior in real-time, ensuring your Phidata agents operate within specified parameters. Verify both the **inputs** to and *outputs* from your agents to ensure they adhere to specified formats and content guidelines.
Learn more about Portkey's Guardrails
[here](https://docs.portkey.ai/product/guardrails).
### Continuous Improvement
Capture qualitative and quantitative user feedback on your requests to continuously enhance your agent performance.
### Caching
Reduce costs and latency with Portkey's built-in caching system.
```python
portkey_config = {
"cache": {
"mode": "semantic" # Options: "simple" or "semantic"
}
}
```
### Security and Compliance
Set budget limits on provider API keys and implement fine-grained user roles and permissions for both your application and the Portkey APIs.
## Additional Resources
* [📘 Portkey Documentation](https://docs.portkey.ai)
* [🐦 Twitter](https://twitter.com/portkeyai)
* [💬 Discord Community](https://discord.gg/DD7vgKK299)
* [📊 Portkey App](https://app.portkey.ai)
For more information on using these features and setting up your Config, please refer to the [Portkey documentation](https://docs.portkey.ai).
# Qdrant Integration
Source: https://docs.phidata.com/examples/integrations/qdrant
## Example
```python
import os
import typer
from typing import Optional
from rich.prompt import Prompt
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.qdrant import Qdrant
api_key = os.getenv("QDRANT_API_KEY")
qdrant_url = os.getenv("QDRANT_URL")
collection_name = "thai-recipe-index"
vector_db = Qdrant(
collection=collection_name,
url=qdrant_url,
api_key=api_key,
)
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=vector_db,
)
# Comment out after first run
knowledge_base.load(recreate=True, upsert=True)
def qdrant_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge_base=knowledge_base,
tool_calls=True,
use_tools=True,
show_tool_calls=True,
debug_mode=True,
# Uncomment the following line to use traditional RAG
# add_references_to_prompt=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if __name__ == "__main__":
typer.run(qdrant_agent)
```
## Usage
```bash
pip install -U qdrant-client pypdf openai phidata
```
```bash Mac
python cookbook/integrations/qdrant/agent.py
```
```bash Windows
python cookbook/integrations/qdrant/agent.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/integrations/qdrant/agent.py)
# SingleStore
Source: https://docs.phidata.com/examples/integrations/singlestore
This guide is in the works
# Introduction
Source: https://docs.phidata.com/examples/introduction
Here you'll find examples that'll help you use phidata, from basic **agents and workflows** to advanced **fine-tuning and evaluations**. If you have more, please [contribute](https://github.com/agno-agi/phidata-docs) to this list.
You can run each recipe individually or clone the [phidata cookbook](https://github.com/agno-agi/phidata/tree/main/cookbook) and run it from there.
## Agents
An Agent that can search the web.
An Agent that can recommend recipes.
An Agent that gives personalised book recommendations to read.
An Agent that helps you shop online.
An Agent to plan out your weekend with fun activities.
A Team of Agents that can work together.
An Agent that can reason and provide a step-by-step solution.
An Agent that can write and run python code.
An Agent that can analyze data using DuckDB.
An Agent that can respond with pydantic objects.
An Agent that can call python functions.
An Agent that can use an image as input.
An Agent that can generate an image.
An Agent that can use Cal.com to schedule meetings.
An Agent that takes an input image and generates results.
An Agent that can research and write articles.
An Agent that can generate videos using ModelsLabs.
An Agent that can interact with Slack.
An Agent that can interact with Discord.
An Agent that can search the web using Firecrawl.
An Agent that can interact with Github.
An Agent that can use a knowledge base to answer questions.
An Agent that can recommend movies.
An Agent that can plan travel itineraries.
An Agent that can search the web using Baidu.
An Agent that can extract the timestamps with summary from a Youtube video.
An Agent that can help you learn about a topic with a detailed study plan
and resources.
# AWS Bedrock
Source: https://docs.phidata.com/examples/provider/aws_bedrock
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.aws.claude import Claude
agent = Agent(
model=Claude(id="anthropic.claude-3-5-sonnet-20240620-v1:0")
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response on the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your keys from [here](https://us-west-2.console.aws.amazon.com/bedrock/home?region=us-west-2#/models).
```bash
pip install -U boto3 phidata
```
```bash
export AWS_ACCESS_KEY_ID=***
export AWS_SECRET_ACCESS_KEY=***
export AWS_DEFAULT_REGION=***
```
```bash
python cookbook/providers/bedrock/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/bedrock/basic.py)
# Azure
Source: https://docs.phidata.com/examples/provider/azure
## Example
```python agent.py
import os
from typing import Iterator
from phi.agent import Agent, RunResponse
from phi.model.azure import AzureOpenAIChat
azure_model = AzureOpenAIChat(
id=os.getenv("AZURE_OPENAI_MODEL_NAME"),
api_key=os.getenv("AZURE_OPENAI_API_KEY"),
azure_endpoint=os.getenv("AZURE_OPENAI_ENDPOINT"),
azure_deployment=os.getenv("AZURE_OPENAI_DEPLOYMENT"),
)
agent = Agent(
model=azure_model,
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response on the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
```bash
pip install -U openai phidata
```
```bash
export AZURE_OPENAI_API_KEY=***
export AZURE_OPENAI_ENDPOINT=***
export AZURE_OPENAI_MODEL_NAME=***
export AZURE_OPENAI_DEPLOYMENT=***
# Optional:
# export AZURE_OPENAI_API_VERSION=***
```
```bash
python cookbook/providers/azure_openai/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/azure_openai/basic.py)
# Claude
Source: https://docs.phidata.com/examples/provider/claude
## Example
Use `Claude` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.anthropic import Claude
agent = Agent(
model=Claude(id="claude-3-5-sonnet-20240620"),
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response on the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
You can get your API key [from Anthropic here](https://anthropic.com/).
```bash
pip install -U anthropic phidata
```
```bash
export ANTHROPIC_API_KEY=xxx
```
```bash
python cookbook/providers/claude/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/claude/basic.py)
# Cohere
Source: https://docs.phidata.com/examples/provider/cohere
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.cohere import CohereChat
agent = Agent(
model=CohereChat(id="command-r-08-2024"),
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your key from [here](https://dashboard.cohere.com/api-keys).
```bash
pip install -U cohere phidata
```
```bash
export CO_API_KEY=xxx
```
```bash
python cookbook/providers/cohere/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/cohere/basic.py)
# DeepSeek
Source: https://docs.phidata.com/examples/provider/deepseek
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.deepseek import DeepSeekChat
agent = Agent(model=DeepSeekChat(), markdown=True)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your key from [here](https://platform.deepseek.com/api_keys).
```bash
pip install -U openai phidata
```
```bash
export DEEPSEEK_API_KEY=***
```
```bash
python cookbook/providers/deepseek/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/deepseek/basic.py)
# Fireworks
Source: https://docs.phidata.com/examples/provider/fireworks
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.fireworks import Fireworks
agent = Agent(
model=Fireworks(id="accounts/fireworks/models/firefunction-v2"),
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your key from [here](https://fireworks.ai/account/api-keys).
```bash
pip install -U fireworks phidata
```
```bash
export FIREWORKS_API_KEY=xxx
```
```bash
python cookbook/providers/fireworks/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/fireworks/basic.py)
# Gemini
Source: https://docs.phidata.com/examples/provider/gemini
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.google import Gemini
agent = Agent(
model=Gemini(id="gemini-1.5-flash"),
show_tool_calls=True,
markdown=True,
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your key [from Google here](https://ai.google.dev/aistudio).
```bash
pip install -U google-generativeai phidata
```
```bash
export GOOGLE_API_KEY=***
```
```bash
python cookbook/providers/google/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/google/basic.py)
# Groq
Source: https://docs.phidata.com/examples/provider/groq
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.groq import Groq
agent = Agent(
model=Groq(id="llama3-groq-70b-8192-tool-use-preview"),
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your key from [here](https://console.groq.com/keys).
```bash
pip install -U groq phidata
```
```bash
export GROQ_API_KEY=xxx
```
```bash
python cookbook/providers/groq/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/groq/basic.py)
# HuggingFace
Source: https://docs.phidata.com/examples/provider/huggingface
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.huggingface import HuggingFaceChat
agent = Agent(
model=HuggingFaceChat(
id="meta-llama/Meta-Llama-3-8B-Instruct",
max_tokens=4096,
),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response on the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your API key [from HuggingFace here](https://huggingface.co/settings/tokens).
```bash
pip install -U huggingface_hub phidata
```
```bash
export HF_TOKEN=***
```
```bash
python cookbook/providers/huggingface/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/huggingface/basic.py)
# Mistral
Source: https://docs.phidata.com/examples/provider/mistral
## Example
```python agent.py
import os
from phi.agent import Agent, RunResponse
from phi.model.mistral import MistralChat
mistral_api_key = os.getenv("MISTRAL_API_KEY")
agent = Agent(
model=MistralChat(
id="mistral-large-latest",
api_key=mistral_api_key,
),
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your key from [here](https://console.mistral.ai/api-keys/).
```bash
pip install -U mistralai phidata
```
```bash
export MISTRAL_API_KEY=xxx
```
```bash
python cookbook/providers/mistral/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/mistral/basic.py)
# Nvidia
Source: https://docs.phidata.com/examples/provider/nvidia
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.nvidia import Nvidia
agent = Agent(model=Nvidia(), markdown=True)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story")
```
## Usage
Get your key [from Nvidia here](https://build.nvidia.com/explore/discover).
```bash
pip install -U openai phidata
```
```bash
export NVIDIA_API_KEY=xxx
```
```bash
python cookbook/providers/nvidia/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/nvidia/basic.py)
# Ollama
Source: https://docs.phidata.com/examples/provider/ollama
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.ollama import Ollama
agent = Agent(
model=Ollama(id="llama3.1")
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Install [ollama](https://ollama.com) and run a model.
```bash
ollama run llama3.1
```
Message `/bye` to exit the chat model
```bash
pip install -U ollama phidata
```
```bash
python cookbook/providers/ollama/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/ollama/basic.py)
# OpenAI
Source: https://docs.phidata.com/examples/provider/openai
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.openai import OpenAIChat
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your key [from OpenAI here](https://platform.openai.com/account/api-keys).
```bash
pip install -U openai phidata
```
```bash
export OPENAI_API_KEY=sk-xxx
```
```bash
python cookbook/providers/openai/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/openai/basic.py)
# OpenRouter
Source: https://docs.phidata.com/examples/provider/openrouter
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.openrouter import OpenRouter
agent = Agent(
model=OpenRouter(id="gpt-4o"),
show_tool_calls=True,
markdown=True,
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your key from [here](https://openrouter.ai/settings/keys).
```bash
pip install -U openai phidata
```
```bash
export OPENROUTER_API_KEY=***
```
```bash
python cookbook/providers/openrouter/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/openrouter/basic.py)
# Sambanova
Source: https://docs.phidata.com/examples/provider/sambanova
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.sambanova import Sambanova
agent = Agent(model=Sambanova(), markdown=True)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story")
```
## Usage
Get your key from [here](https://cloud.sambanova.ai/apis).
```bash
pip install -U openai phidata
```
```bash
export SAMBANOVA_API_KEY=***
```
```bash
python cookbook/providers/sambanova/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/sambanova/basic.py)
# Together
Source: https://docs.phidata.com/examples/provider/together
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.together import Together
agent = Agent(
model=Together(id="meta-llama/Meta-Llama-3.1-8B-Instruct-Turbo"),
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your key [from Together here](https://api.together.xyz/settings/api-keys).
```bash
pip install -U together openai phidata
```
```bash
export TOGETHER_API_KEY=xxx
```
```bash
python cookbook/providers/together/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/together/basic.py)
# xAI
Source: https://docs.phidata.com/examples/provider/xai
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.xai import xAI
agent = Agent(
model=xAI(id="grok-beta"),
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Usage
Get your API key [from xAI here](https://console.x.ai/).
```bash
pip install -U openai phidata
```
```bash
export XAI_API_KEY=***
```
```bash
python cookbook/providers/xai/basic.py
```
## Information
* View on [Github](https://github.com/agno-agi/phidata/tree/main/cookbook/providers/xai/basic.py)
# Hackernews Team
Source: https://docs.phidata.com/examples/teams/hackernews
This guide is in the works
# Investment Team
Source: https://docs.phidata.com/examples/teams/investment
This guide is in the works
# Journalist Team
Source: https://docs.phidata.com/examples/teams/journalist
This guide is in the works
# Research Team
Source: https://docs.phidata.com/examples/teams/research
This guide is in the works
# ArXiv Research Agent
Source: https://docs.phidata.com/examples/use-case/arxiv-research
This guide is in the works
# Sql Agent
Source: https://docs.phidata.com/examples/use-case/sql
This guide is in the works
# World Building
Source: https://docs.phidata.com/examples/use-case/worldbuilding
This guide is in the works
# Connecting to Tableplus
Source: https://docs.phidata.com/faq/connecting-to-tableplus
If you want to inspect your pgvector container to explore your storage or knowledge base, you can use TablePlus. Follow these steps:
## Step 1: Start Your `pgvector` Container
Run the following command to start a `pgvector` container locally:
```bash
docker run -d \
-e POSTGRES_DB=ai \
-e POSTGRES_USER=ai \
-e POSTGRES_PASSWORD=ai \
-e PGDATA=/var/lib/postgresql/data/pgdata \
-v pgvolume:/var/lib/postgresql/data \
-p 5532:5432 \
--name pgvector \
phidata/pgvector:16
```
* `POSTGRES_DB=ai` sets the default database name.
* `POSTGRES_USER=ai` and `POSTGRES_PASSWORD=ai` define the database credentials.
* The container exposes port `5432` (mapped to `5532` on your local machine).
## Step 2: Configure TablePlus
1. **Open TablePlus**: Launch the TablePlus application.
2. **Create a New Connection**: Click on the `+` icon to add a new connection.
3. **Select `PostgreSQL`**: Choose PostgreSQL as the database type.
Fill in the following connection details:
* **Host**: `localhost`
* **Port**: `5532`
* **Database**: `ai`
* **User**: `ai`
* **Password**: `ai`
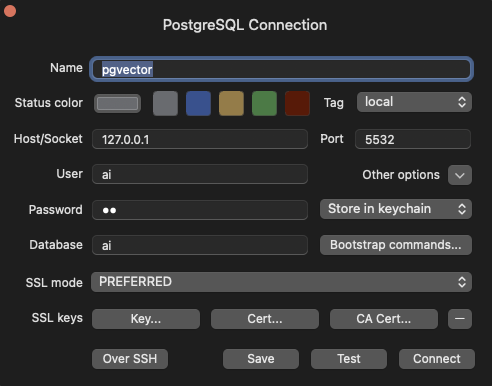 # Could Not Connect To Docker
Source: https://docs.phidata.com/faq/could-not-connect-to-docker
If you have Docker up and running and get the following error, please read on:
```bash
ERROR Could not connect to docker. Please confirm docker is installed and running
ERROR Error while fetching server API version: ('Connection aborted.', FileNotFoundError(2, 'No such file or directory'))
```
## Quick fix
Create the `/var/run/docker.sock` symlink using:
```shell
sudo ln -s "$HOME/.docker/run/docker.sock" /var/run/docker.sock
```
In 99% of the cases, this should work. If it doesnt, try:
```shell
sudo chown $USER /var/run/docker.sock
```
## Full details
Phidata uses [docker-py](https://github.com/docker/docker-py) to run containers, and if the `/var/run/docker.sock` is missing or has incorrect permissions, it cannot connect to docker.
**To fix, please create the `/var/run/docker.sock` file using:**
```shell
sudo ln -s "$HOME/.docker/run/docker.sock" /var/run/docker.sock
```
If that does not work, check the permissions using `ls -l /var/run/docker.sock`.
If the `/var/run/docker.sock` does not exist, check if the `$HOME/.docker/run/docker.sock` file is missing. If its missing, please reinstall Docker.
**If none of this works and the `/var/run/docker.sock` exists:**
* Give your user permissions to the `/var/run/docker.sock` file:
```shell
sudo chown $USER /var/run/docker.sock
```
* Give your user permissions to the docker group:
```shell
sudo usermod -a -G docker $USER
```
## More info
* [Docker-py Issue](https://github.com/docker/docker-py/issues/3059#issuecomment-1294369344)
* [Stackoverflow answer](https://stackoverflow.com/questions/48568172/docker-sock-permission-denied/56592277#56592277)
# Setting Environment Variables
Source: https://docs.phidata.com/faq/environment_variables
To configure your environment for applications, you may need to set environment variables. This guide provides instructions for setting environment variables in both macOS (Shell) and Windows (PowerShell and Windows Command Prompt).
## macOS
### Setting Environment Variables in Shell
#### Temporary Environment Variables
These environment variables will only be available in the current shell session.
```shell
export VARIABLE_NAME="value"
```
To display the environment variable:
```shell
echo $VARIABLE_NAME
```
#### Permanent Environment Variables
To make environment variables persist across sessions, add them to your shell configuration file (e.g., `.bashrc`, `.bash_profile`, `.zshrc`).
For Zsh:
```shell
echo 'export VARIABLE_NAME="value"' >> ~/.zshrc
source ~/.zshrc
```
To display the environment variable:
```shell
echo $VARIABLE_NAME
```
## Windows
### Setting Environment Variables in PowerShell
#### Temporary Environment Variables
These environment variables will only be available in the current PowerShell session.
```powershell
$env:VARIABLE_NAME = "value"
```
To display the environment variable:
```powershell
echo $env:VARIABLE_NAME
```
#### Permanent Environment Variables
To make environment variables persist across sessions, add them to your PowerShell profile script (e.g., `Microsoft.PowerShell_profile.ps1`).
```powershell
notepad $PROFILE
```
Add the following line to the profile script:
```powershell
$env:VARIABLE_NAME = "value"
```
Save and close the file, then reload the profile:
```powershell
. $PROFILE
```
To display the environment variable:
```powershell
echo $env:VARIABLE_NAME
```
### Setting Environment Variables in Windows Command Prompt
#### Temporary Environment Variables
These environment variables will only be available in the current Command Prompt session.
```cmd
set VARIABLE_NAME=value
```
To display the environment variable:
```cmd
echo %VARIABLE_NAME%
```
#### Permanent Environment Variables
To make environment variables persist across sessions, you can use the `setx` command:
```cmd
setx VARIABLE_NAME "value"
```
Note: After setting an environment variable using `setx`, you need to restart the Command Prompt or any applications that need to read the new environment variable.
To display the environment variable in a new Command Prompt session:
```cmd
echo %VARIABLE_NAME%
```
By following these steps, you can effectively set and display environment variables in macOS Shell, Windows Command Prompt, and PowerShell. This will ensure your environment is properly configured for your applications.
# Command line authentication
Source: https://docs.phidata.com/faq/phi-auth
If you run `phi auth` and you get the error: `CLI authentication failed` or your CLI gets stuck on
```
Waiting for a response from browser...
```
It means that your CLI was not able to authenticate with your Phidata account on [phidata.app](https://phidata.app)
The quickest fix for this is to export your `PHI_API_KEY` environment variable. You can do this by running the following command:
```bash
export PHI_API_KEY=
```
Your API key can be found on [phidata.app](https://phidata.app) in the sidebar under `API Key`.
 Reason for CLI authentication failure:
* Some browsers like Safari and Brave block connection to the localhost domain. Browsers like Chrome work great with `phi auth`.
# Getting Help
Source: https://docs.phidata.com/getting-help
Thank you for building with phidata. If you need help, please come chat with us on [discord](https://discord.gg/phidata) or post your questions on the [community forum](https://community.phidata.com).
## Looking for dedicated support?
We've helped many companies build AI products, the general workflow is:
1. **Build agents** to perform tasks specific to your product.
2. **Serve your agents** via an API and connect them to your product.
3. **Monitor, evaluate and improve** your AI product.
We provide dedicated support and development, [book a call](https://cal.com/phidata/intro) to get started. Our prices start at **\$20k/month** and we specialize in taking companies from idea to production within 3 months.
# Install & Upgrade
Source: https://docs.phidata.com/how-to/install
## Install phidata
We recommend installing `phidata` using `pip` in a python virtual environment
Open the `Terminal` and create a python virtual environment.
```bash Mac
python3 -m venv ~/.venvs/aienv
source ~/.venvs/aienv/bin/activate
```
```bash Windows
python3 -m venv aienv
aienv/scripts/activate
```
Install the latest version of `phidata`
```bash Mac
pip install -U phidata
```
```bash Windows
pip install -U phidata
```
If you encounter errors, try updating pip using `python -m pip install --upgrade pip`
***
## Upgrade phidata
To upgrade `phidata`, run this inside your virtual environment
```bash
pip install -U phidata --no-cache-dir
```
# Introduction
Source: https://docs.phidata.com/introduction
**Build agents and workflows to automate intelligent work.**
Phidata is now Agno! We've moved! Check out our new home at [Agno
AGI](https://github.com/agno-agi/agno)
## What is Phidata?
**Phidata is a framework for building multi-modal agents and workflows.**
* **Build agents with memory, knowledge, tools and reasoning.**
* **Build teams of agents that can work together to solve problems.**
* **Interact with your agents and workflows using a beautiful Agent UI.**
## Key Features
* [Simple & Elegant](#simple-and-elegant)
* [Powerful & Flexible](#powerful-and-flexible)
* [Multi-Modal by default](#multi-modal-by-default)
* [Multi-Agent orchestration](#multi-agent-orchestration)
* [A beautiful Agent UI to chat with your agents](/agent-ui)
* [Agentic RAG built-in](/more-examples#agentic-rag)
* [Structured outputs](/more-examples#structured-outputs)
* [Reasoning built-in](/more-examples#reasoning-agent)
* [Monitoring & Debugging built-in](/monitoring)
## Install
```shell
pip install -U phidata
```
## Simple & Elegant
Phidata Agents are simple and elegant, resulting in minimal, beautiful code.
For example, you can create a web search agent in 10 lines of code.
```python web_search.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.duckduckgo import DuckDuckGo
web_agent = Agent(
name="Web Agent",
model=OpenAIChat(id="gpt-4o"),
tools=[DuckDuckGo()],
instructions=["Always include sources"],
show_tool_calls=True,
markdown=True,
)
web_agent.print_response("Tell me about OpenAI Sora?", stream=True)
```
### Setup
```bash Mac
python3 -m venv ~/.venvs/aienv
source ~/.venvs/aienv/bin/activate
```
```bash Windows
python3 -m venv aienv
aienv/scripts/activate
```
```bash Mac
pip install -U phidata openai duckduckgo-search
```
```bash Windows
pip install -U phidata openai duckduckgo-search
```
Phidata works with most model providers but for these examples let's use OpenAI.
```bash Mac
export OPENAI_API_KEY=sk-***
```
```bash Windows
setx OPENAI_API_KEY sk-***
```
You can get an API key from [here](https://platform.openai.com/account/api-keys).
```shell
python web_search.py
```
## Powerful & Flexible
Phidata agents can use multiple tools and follow instructions to achieve complex tasks.
For example, you can create a finance agent with tools to query financial data.
```python finance_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
finance_agent = Agent(
name="Finance Agent",
model=OpenAIChat(id="gpt-4o"),
instructions=["Use tables to display data"],
show_tool_calls=True,
markdown=True,
)
finance_agent.print_response("Summarize analyst recommendations for NVDA", stream=True)
```
Install libraries
```shell
pip install openai
```
Run the agent
```shell
python finance_agent.py
```
## Multi-Modal by default
Phidata agents support text, images, audio and video.
For example, you can create an image agent that can understand images and make tool calls as needed
```python image_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.duckduckgo import DuckDuckGo
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
tools=[DuckDuckGo()],
markdown=True,
)
agent.print_response(
"Tell me about this image and give me the latest news about it.",
images=["https://upload.wikimedia.org/wikipedia/commons/b/bf/Krakow_-_Kosciol_Mariacki.jpg"],
stream=True,
)
```
```shell
python image_agent.py
```
## Multi-Agent orchestration
Phidata agents can work together as a team to achieve complex tasks.
```python agent_team.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.duckduckgo import DuckDuckGo
web_agent = Agent(
name="Web Agent",
role="Search the web for information",
model=OpenAIChat(id="gpt-4o"),
tools=[DuckDuckGo()],
instructions=["Always include sources"],
show_tool_calls=True,
markdown=True,
)
finance_agent = Agent(
name="Finance Agent",
role="Get financial data",
model=OpenAIChat(id="gpt-4o"),
instructions=["Use tables to display data"],
show_tool_calls=True,
markdown=True,
)
agent_team = Agent(
team=[web_agent, finance_agent],
instructions=["Always include sources", "Use tables to display data"],
show_tool_calls=True,
markdown=True,
)
agent_team.print_response("Summarize analyst recommendations and share the latest news for NVDA", stream=True)
```
Run the agent team
```shell
python agent_team.py
```
## Continue reading
* Chat with your Agents using a beautiful [Agent UI](/agent-ui).
* [More examples](/more-examples)
* [Monitoring & Debugging](/monitoring)
# ArXiv Knowledge Base
Source: https://docs.phidata.com/knowledge/arxiv
The **ArxivKnowledgeBase** reads Arxiv articles, converts them into vector embeddings and loads them to a vector databse.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```shell
pip install arxiv
```
```python knowledge_base.py
from phi.knowledge.arxiv import ArxivKnowledgeBase
from phi.vectordb.pgvector import PgVector
knowledge_base = ArxivKnowledgeBase(
queries=["Generative AI", "Machine Learning"],
# Table name: ai.arxiv_documents
vector_db=PgVector(
table_name="arxiv_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an `Agent`:
```python agent.py
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | --------------------------------------------------------------------------------------------------- |
| `queries` | `List[str]` | - | Queries to search |
| `reader` | `ArxivReader` | `ArxivReader()` | A `ArxivReader` that reads the articles and converts them into `Documents` for the vector database. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# Combined KnowledgeBase
Source: https://docs.phidata.com/knowledge/combined
The **CombinedKnowledgeBase** combines multiple knowledge bases into 1 and is used when your app needs information using multiple sources.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```shell
pip install pypdf bs4
```
```python knowledge_base.py
from phi.knowledge.combined import CombinedKnowledgeBase
from phi.vectordb.pgvector import PgVector
url_pdf_knowledge_base = PDFUrlKnowledgeBase(
urls=["pdf_url"],
# Table name: ai.pdf_documents
vector_db=PgVector(
table_name="pdf_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
website_knowledge_base = WebsiteKnowledgeBase(
urls=["https://docs.phidata.com/introduction"],
# Number of links to follow from the seed URLs
max_links=10,
# Table name: ai.website_documents
vector_db=PgVector(
table_name="website_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
local_pdf_knowledge_base = PDFKnowledgeBase(
path="data/pdfs",
# Table name: ai.pdf_documents
vector_db=PgVector(
table_name="pdf_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
reader=PDFReader(chunk=True),
)
knowledge_base = CombinedKnowledgeBase(
sources=[
url_pdf_knowledge_base,
website_knowledge_base,
local_pdf_knowledge_base,
],
vector_db=PgVector(
# Table name: ai.combined_documents
table_name="combined_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an Agent:
```python agent.py
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ---------------------- | ------------------- | ----------------------------------------------------------------------------------------------- |
| `sources` | `List[AgentKnowledge]` | - | List of Agent knowledge bases. |
| `reader` | `Reader` | - | A `Reader` that converts the content of the documents into `Documents` for the vector database. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# CSV Knowledge Base
Source: https://docs.phidata.com/knowledge/csv
The **CSVKnowledgeBase** reads **local CSV** files, converts them into vector embeddings and loads them to a vector databse.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```python
from phi.knowledge.csv import CSVKnowledgeBase
from phi.vectordb.pgvector import PgVector
knowledge_base = CSVKnowledgeBase(
path="data/csv",
# Table name: ai.csv_documents
vector_db=PgVector(
table_name="csv_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an `Agent`:
```python
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | ----------------------------------------------------------------------------------- |
| `path` | `Union[str, Path]` | - | Path to docx files. Can point to a single docx file or a directory of docx files. |
| `reader` | `CSVReader` | `CSVReader()` | A `CSVReader` that converts the CSV files into `Documents` for the vector database. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# CSV URL Knowledge Base
Source: https://docs.phidata.com/knowledge/csv-url
The **CSVUrlKnowledgeBase** reads **CSVs from urls**, converts them into vector embeddings and loads them to a vector database.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```python knowledge_base.py
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector
knowledge_base = CSVUrlKnowledgeBase(
urls=["csv_url"],
# Table name: ai.csv_documents
vector_db=PgVector(
table_name="csv_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an Agent:
```python agent.py
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | ----------------------------------------------------------------------------------- |
| `urls` | `List[str]` | - | URLs for `PDF` files. |
| `reader` | `CSVUrlReader` | `CSVUrlReader()` | A `CSVUrlReader` that converts the `CSVs` into `Documents` for the vector database. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# Document Knowledge Base
Source: https://docs.phidata.com/knowledge/document
The **DocumentKnowledgeBase** reads **local docs** files, converts them into vector embeddings and loads them to a vector databse.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```shell
pip install textract
```
```python
from phi.knowledge.document import DocumentKnowledgeBase
from phi.vectordb.pgvector import PgVector
knowledge_base = DocumentKnowledgeBase(
path="data/docs",
# Table name: ai.documents
vector_db=PgVector(
table_name="documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an `Agent`:
```python
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | ----------------------------------------------------------------------------------------------- |
| `documents` | `List[Document]` | - | List of documents to load into the vector database. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `reader` | `Reader` | - | A `Reader` that converts the content of the documents into `Documents` for the vector database. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# Docx Knowledge Base
Source: https://docs.phidata.com/knowledge/docx
The **DocxKnowledgeBase** reads **local docx** files, converts them into vector embeddings and loads them to a vector databse.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```shell
pip install textract
```
```python
from phi.knowledge.docx import DocxKnowledgeBase
from phi.vectordb.pgvector import PgVector
knowledge_base = DocxKnowledgeBase(
path="data/docs",
# Table name: ai.docx_documents
vector_db=PgVector(
table_name="docx_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an `Agent`:
```python
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | ------------------------------------------------------------------------------------- |
| `path` | `Union[str, Path]` | - | Path to docx files. Can point to a single docx file or a directory of docx files. |
| `formats` | `List[str]` | `[".doc", ".docx"]` | Formats accepted by this knowledge base. |
| `reader` | `DocxReader` | `DocxReader()` | A `DocxReader` that converts the docx files into `Documents` for the vector database. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# Introduction
Source: https://docs.phidata.com/knowledge/introduction
A **knowledge base** is a database of information that an agent can search to improve its responses. This information is stored in a vector database and provides agents with business context, helping them respond in a context-aware manner. The general syntax is:
```python
from phi.agent import Agent, AgentKnowledge
# Create a knowledge base for the Agent
knowledge_base = AgentKnowledge(vector_db=...)
# Add information to the knowledge base
knowledge_base.load_text("The sky is blue")
# Add the knowledge base to the Agent and
# give it a tool to search the knowledge base as needed
agent = Agent(knowledge=knowledge_base, search_knowledge=True)
```
## Vector Databases
While any type of storage can act as a knowledge base, vector databases offer the best solution for retrieving relevant results from dense information quickly. Here's how vector databases are used with Agents:
Break down the knowledge into smaller chunks to ensure our search query
returns only relevant results.
Convert the chunks into embedding vectors and store them in a vector
database.
When the user sends a message, we convert the input message into an
embedding and "search" for nearest neighbors in the vector database.
## Loading the Knowledge Base
Before you can use a knowledge base, it needs to be loaded with embeddings that will be used for retrieval. Use one of the following knowledge bases to simplify the chunking, loading, searching and optimization process:
* [ArXiv knowledge base](/knowledge/arxiv): Load ArXiv papers to a knowledge base
* [Combined knowledge base](/knowledge/combined): Combine multiple knowledge bases into 1
* [CSV knowledge base](/knowledge/csv): Load CSV files to a knowledge base
* [Document knowledge base](/knowledge/document): Load local docx files to a knowledge base
* [JSON knowledge base](/knowledge/json): Load JSON files to a knowledge base
* [LangChain knowledge base](/knowledge/langchain): Use a Langchain retriever as a knowledge base
* [PDF knowledge base](/knowledge/pdf): Load local PDF files to a knowledge base
* [PDF URL knowledge base](/knowledge/pdf-url): Load PDF files from a URL to a knowledge base
* [S3 PDF knowledge base](/knowledge/s3_pdf): Load PDF files from S3 to a knowledge base
* [S3 Text knowledge base](/knowledge/s3_text): Load text files from S3 to a knowledge base
* [Text knowledge base](/knowledge/text): Load text/docx files to a knowledge base
* [Website knowledge base](/knowledge/website): Load website data to a knowledge base
* [Wikipedia knowledge base](/knowledge/wikipedia): Load wikipedia articles to a knowledge base
# JSON Knowledge Base
Source: https://docs.phidata.com/knowledge/json
The **JSONKnowledgeBase** reads **local JSON** files, converts them into vector embeddings and loads them to a vector databse.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```python knowledge_base.py
from phi.knowledge.json import JSONKnowledgeBase
from phi.vectordb.pgvector import PgVector
knowledge_base = JSONKnowledgeBase(
path="data/json",
# Table name: ai.json_documents
vector_db=PgVector(
table_name="json_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an `Agent`:
```python agent.py
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | --------------------------------------------------------------------------------------- |
| `path` | `Union[str, Path]` | - | Path to `JSON` files. Can point to a single JSON file or a directory of JSON files. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `reader` | `JSONReader` | `JSONReader()` | A `JSONReader` that converts the `JSON` files into `Documents` for the vector database. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# LangChain Knowledge Base
Source: https://docs.phidata.com/knowledge/langchain
The **LangchainKnowledgeBase** allows us to use a LangChain retriever or vector store as a knowledge base.
## Usage
```shell
pip install langchain
```
```python langchain_kb.py
from phi.agent import Agent
from phi.knowledge.langchain import LangChainKnowledgeBase
from langchain.embeddings import OpenAIEmbeddings
from langchain.document_loaders import TextLoader
from langchain.text_splitter import CharacterTextSplitter
from langchain.vectorstores import Chroma
chroma_db_dir = "./chroma_db"
def load_vector_store():
state_of_the_union = ws_settings.ws_root.joinpath("data/demo/state_of_the_union.txt")
# -*- Load the document
raw_documents = TextLoader(str(state_of_the_union)).load()
# -*- Split it into chunks
text_splitter = CharacterTextSplitter(chunk_size=1000, chunk_overlap=0)
documents = text_splitter.split_documents(raw_documents)
# -*- Embed each chunk and load it into the vector store
Chroma.from_documents(documents, OpenAIEmbeddings(), persist_directory=str(chroma_db_dir))
# -*- Get the vectordb
db = Chroma(embedding_function=OpenAIEmbeddings(), persist_directory=str(chroma_db_dir))
# -*- Create a retriever from the vector store
retriever = db.as_retriever()
# -*- Create a knowledge base from the vector store
knowledge_base = LangChainKnowledgeBase(retriever=retriever)
agent = Agent(knowledge_base=knowledge_base, add_references_to_prompt=True)
conv.print_response("What did the president say about technology?")
```
## Params
| Parameter | Type | Default | Description |
| --------------- | ------ | ------- | ------------------------------------------------------------------------- |
| `retriever` | `Any` | `None` | LangChain retriever. |
| `vectorstore` | `Any` | `None` | LangChain vector store used to create a retriever. |
| `search_kwargs` | `dict` | `None` | Search kwargs when creating a retriever using the langchain vector store. |
# LlamaIndex Knowledge Base
Source: https://docs.phidata.com/knowledge/llamaindex
The **LlamaIndexKnowledgeBase** allows us to use a LlamaIndex retriever or vector store as a knowledge base.
## Usage
```shell
pip install llama-index-core llama-index-readers-file llama-index-embeddings-openai
```
```python llamaindex_kb.py
from pathlib import Path
from shutil import rmtree
import httpx
from phi.agent import Agent
from phi.knowledge.llamaindex import LlamaIndexKnowledgeBase
from llama_index.core import (
SimpleDirectoryReader,
StorageContext,
VectorStoreIndex,
)
from llama_index.core.retrievers import VectorIndexRetriever
from llama_index.core.node_parser import SentenceSplitter
data_dir = Path(__file__).parent.parent.parent.joinpath("wip", "data", "paul_graham")
if data_dir.is_dir():
rmtree(path=data_dir, ignore_errors=True)
data_dir.mkdir(parents=True, exist_ok=True)
url = "https://raw.githubusercontent.com/run-llama/llama_index/main/docs/docs/examples/data/paul_graham/paul_graham_essay.txt"
file_path = data_dir.joinpath("paul_graham_essay.txt")
response = httpx.get(url)
if response.status_code == 200:
with open(file_path, "wb") as file:
file.write(response.content)
print(f"File downloaded and saved as {file_path}")
else:
print("Failed to download the file")
documents = SimpleDirectoryReader(str(data_dir)).load_data()
splitter = SentenceSplitter(chunk_size=1024)
nodes = splitter.get_nodes_from_documents(documents)
storage_context = StorageContext.from_defaults()
index = VectorStoreIndex(nodes=nodes, storage_context=storage_context)
retriever = VectorIndexRetriever(index)
# Create a knowledge base from the vector store
knowledge_base = LlamaIndexKnowledgeBase(retriever=retriever)
# Create an agent with the knowledge base
agent = Agent(knowledge_base=knowledge_base, search_knowledge=True, debug_mode=True, show_tool_calls=True)
# Use the agent to ask a question and print a response.
agent.print_response("Explain what this text means: low end eats the high end", markdown=True)
```
## Params
| Parameter | Type | Default | Description |
| ----------- | -------------------- | ------- | --------------------------------------------------------------------- |
| `retriever` | `BaseRetriever` | `None` | LlamaIndex retriever used for querying the knowledge base. |
| `loader` | `Optional[Callable]` | `None` | Optional callable function to load documents into the knowledge base. |
# PDF Knowledge Base
Source: https://docs.phidata.com/knowledge/pdf
The **PDFKnowledgeBase** reads **local PDF** files, converts them into vector embeddings and loads them to a vector databse.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```shell
pip install pypdf
```
```python knowledge_base.py
from phi.knowledge.pdf import PDFKnowledgeBase, PDFReader
from phi.vectordb.pgvector import PgVector
pdf_knowledge_base = PDFKnowledgeBase(
path="data/pdfs",
# Table name: ai.pdf_documents
vector_db=PgVector(
table_name="pdf_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
reader=PDFReader(chunk=True),
)
```
Then use the `knowledge_base` with an Agent:
```python agent.py
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ---------------------------------- | ------------------- | ---------------------------------------------------------------------------------------------- |
| `path` | `Union[str, Path]` | - | Path to `PDF` files. Can point to a single PDF file or a directory of PDF files. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. Example: `PgVector` |
| `reader` | `Union[PDFReader, PDFImageReader]` | `PDFReader()` | A `PDFReader` that converts the `PDFs` into `Documents` for the vector database. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. For Example: Create an index for `PgVector`. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# PDF URL Knowledge Base
Source: https://docs.phidata.com/knowledge/pdf-url
The **PDFUrlKnowledgeBase** reads **PDFs from urls**, converts them into vector embeddings and loads them to a vector database.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```shell
pip install pypdf
```
```python knowledge_base.py
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector
knowledge_base = PDFUrlKnowledgeBase(
urls=["pdf_url"],
# Table name: ai.pdf_documents
vector_db=PgVector(
table_name="pdf_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an Agent:
```python agent.py
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ---------------------------------------- | ------------------- | ----------------------------------------------------------------------------------- |
| `urls` | `List[str]` | - | URLs for `PDF` files. |
| `reader` | `Union[PDFUrlReader, PDFUrlImageReader]` | `PDFUrlReader()` | A `PDFUrlReader` that converts the `PDFs` into `Documents` for the vector database. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# S3 PDF Knowledge Base
Source: https://docs.phidata.com/knowledge/s3_pdf
The **S3PDFKnowledgeBase** reads **PDF** files from an S3 bucket, converts them into vector embeddings and loads them to a vector databse.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```python
from phi.knowledge.s3.pdf import S3PDFKnowledgeBase
from phi.vectordb.pgvector import PgVector
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = S3PDFKnowledgeBase(
bucket_name="phi-public",
key="recipes/ThaiRecipes.pdf",
vector_db=PgVector(table_name="recipes", db_url=db_url),
)
```
Then use the `knowledge_base` with an `Agent`:
```python
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("How to make Thai curry?")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | ---------------------------------------------------------------------------------- |
| `reader` | `S3PDFReader` | `S3PDFReader()` | A `S3PDFReader` that converts the `PDFs` into `Documents` for the vector database. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# S3 Text Knowledge Base
Source: https://docs.phidata.com/knowledge/s3_text
The **S3TextKnowledgeBase** reads **text** files from an S3 bucket, converts them into vector embeddings and loads them to a vector databse.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```shell
pip install textract
```
```python
from phi.knowledge.s3.text import S3TextKnowledgeBase
from phi.vectordb.pgvector import PgVector
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = S3TextKnowledgeBase(
bucket_name="phi-public",
key="recipes/recipes.docx",
vector_db=PgVector(table_name="recipes", db_url=db_url),
)
```
Then use the `knowledge_base` with an `Agent`:
```python
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("How to make Hummus?")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | ----------------------------------------------------------------------------------------- |
| `formats` | `List[str]` | `[".doc", ".docx"]` | Formats accepted by this knowledge base. |
| `reader` | `S3TextReader` | `S3TextReader()` | A `S3TextReader` that converts the `Text` files into `Documents` for the vector database. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# Text Knowledge Base
Source: https://docs.phidata.com/knowledge/text
The **TextKnowledgeBase** reads **local txt** files, converts them into vector embeddings and loads them to a vector databse.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```python knowledge_base.py
from phi.knowledge.text import TextKnowledgeBase
from phi.vectordb.pgvector import PgVector
knowledge_base = TextKnowledgeBase(
path="data/txt_files",
# Table name: ai.text_documents
vector_db=PgVector(
table_name="text_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an Agent:
```python agent.py
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge_base=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | ------------------------------------------------------------------------------------- |
| `path` | `Union[str, Path]` | - | Path to text files. Can point to a single txt file or a directory of txt files. |
| `formats` | `List[str]` | `[".txt"]` | Formats accepted by this knowledge base. |
| `reader` | `TextReader` | `TextReader()` | A `TextReader` that converts the text files into `Documents` for the vector database. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# Website Knowledge Base
Source: https://docs.phidata.com/knowledge/website
The **WebsiteKnowledgeBase** reads websites, converts them into vector embeddings and loads them to a `vector_db`.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](https://docs.phidata.com/vectordb/pgvector)
```shell
pip install bs4
```
```python knowledge_base.py
from phi.knowledge.website import WebsiteKnowledgeBase
from phi.vectordb.pgvector import PgVector
knowledge_base = WebsiteKnowledgeBase(
urls=["https://docs.phidata.com/introduction"],
# Number of links to follow from the seed URLs
max_links=10,
# Table name: ai.website_documents
vector_db=PgVector(
table_name="website_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an `Agent`:
```python agent.py
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | ------------------------------------------------------------------------------------------------- |
| `urls` | `List[str]` | - | URLs to read |
| `reader` | `WebsiteReader` | - | A `WebsiteReader` that reads the urls and converts them into `Documents` for the vector database. |
| `max_depth` | `int` | `3` | Maximum depth to crawl. |
| `max_links` | `int` | `10` | Number of links to crawl. |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# Wikipedia KnowledgeBase
Source: https://docs.phidata.com/knowledge/wikipedia
The **WikipediaKnowledgeBase** reads wikipedia topics, converts them into vector embeddings and loads them to a vector databse.
## Usage
We are using a local PgVector database for this example. [Make sure it's running](http://localhost:3333/vectordb/pgvector)
```shell
pip install wikipedia
```
```python knowledge_base.py
from phi.knowledge.wikipedia import WikipediaKnowledgeBase
from phi.vectordb.pgvector import PgVector
knowledge_base = WikipediaKnowledgeBase(
topics=["Manchester United", "Real Madrid"],
# Table name: ai.wikipedia_documents
vector_db=PgVector(
table_name="wikipedia_documents",
db_url="postgresql+psycopg://ai:ai@localhost:5532/ai",
),
)
```
Then use the `knowledge_base` with an Agent:
```python agent.py
from phi.agent import Agent
from knowledge_base import knowledge_base
agent = Agent(
knowledge=knowledge_base,
search_knowledge=True,
)
agent.knowledge.load(recreate=False)
agent.print_response("Ask me about something from the knowledge base")
```
## Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------ | ------------------- | -------------------------------------------------------------------------------------------- |
| `topics` | `List[str]` | - | Topics to read |
| `vector_db` | `VectorDb` | - | Vector Database for the Knowledge Base. |
| `reader` | `Reader` | - | A `Reader` that reads the topics and converts them into `Documents` for the vector database. |
| `num_documents` | `int` | `5` | Number of documents to return on search. |
| `optimize_on` | `int` | - | Number of documents to optimize the vector db on. |
| `chunking_strategy` | `ChunkingStrategy` | `FixedSizeChunking` | The chunking strategy to use. |
# Upgrade to v2.5.0
Source: https://docs.phidata.com/migration/2-5-0
This guide will help you migrate your code to v2.5.0
## Key Changes
1. Constructor: `Assistant()` -> `Agent()`
2. LLM/Model: `llm` -> `model`
3. Knowledge Base: `knowledge_base` -> `knowledge`
4. RunResponse: Pydantic model for string response
5. Structured Output: Changes in how structured output is handled
## Detailed Migration Steps
### 1. Update Import Statements
```python
# Version < 2.5.0
from phi.assistant import Assistant
from phi.llm.openai import OpenAIChat
from phi.storage.assistant.postgres import PgAssistantStorage
# Version >= 2.5.0
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.storage.agent.postgres import PgAgentStorage
```
### 2. Update Arguments
Replace `llm` with `model` and `model` with `id`.
```python
# Version < 2.5.0
from phi.assistant import Assistant
from phi.llm.openai import OpenAIChat
assistant = Assistant(
llm=OpenAIChat(model="gpt-4o"),
)
# Version >= 2.5.0
from phi.agent import Agent
from phi.model.openai import OpenAIChat
agent = Agent(
# Note: 'llm' is now 'model' and 'model' is now 'id'
model=OpenAIChat(id="gpt-4o"),
)
```
### 3. Update Knowledge Base
Replace `knowledge_base` with `knowledge`.
```python
# Version < 2.5.0
from phi.assistant import Assistant
from phi.storage.assistant.postgres import PgAssistantStorage
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector2
from phi.llm.openai import OpenAIChat
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector2(collection="recipes", db_url=db_url),
)
# Comment out after first run
knowledge_base.load()
storage = PgAssistantStorage(table_name="pdf_assistant", db_url=db_url)
assistant = Assistant(
llm=OpenAIChat(model="gpt-4o"),
knowledge_base=knowledge_base,
search_knowledge=True, # enables agent to search knowledge base
storage=storage,
)
res = assistant.run("What is the recipe for chicken curry?")
# Version >= 2.5.0
from phi.agent import Agent, RunResponse
from phi.storage.agent.postgres import PgAgentStorage
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector, SearchType
from phi.model.openai import OpenAIChat
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector(table_name="recipes", db_url=db_url, search_type=SearchType.hybrid),
)
# Comment out after first run
knowledge_base.load()
storage = PgAgentStorage(table_name="pdf_agent", db_url=db_url)
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
knowledge=knowledge_base,
storage=storage,
)
response: RunResponse = agent.run("What is the recipe for chicken curry?")
res = response.content
```
### 4. Output model response as a string
```python
# Version < 2.5.0
from phi.assistant import Assistant
from phi.llm.openai import OpenAIChat
assistant = Assistant(
llm=OpenAIChat(model="gpt-4o"),
)
res = assistant.run("What is the recipe for chicken curry?")
# Version >= 2.5.0
from phi.agent import Agent, RunResponse
from phi.model.openai import OpenAIChat
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
)
response: RunResponse = agent.run("What is the recipe for chicken curry?")
res = response.content
```
### 5. Handle structured outputs
Replace `output_model` with `response_model`.
If you are using OpenAI models, you can set `structured_outputs=True` to get a structured output.
```python
# Version < 2.5.0
from typing import List
from pydantic import BaseModel, Field
from rich.pretty import pprint
from phi.assistant import Assistant
from phi.llm.openai import OpenAIChat
class MovieScript(BaseModel):
setting: str = Field(..., description="Provide a nice setting for a blockbuster movie.")
ending: str = Field(..., description="Ending of the movie. If not available, provide a happy ending.")
genre: str = Field(
..., description="Genre of the movie. If not available, select action, thriller or romantic comedy."
)
name: str = Field(..., description="Give a name to this movie")
characters: List[str] = Field(..., description="Name of characters for this movie.")
storyline: str = Field(..., description="3 sentence storyline for the movie. Make it exciting!")
movie_assistant = Assistant(
llm=OpenAIChat(model="gpt-4-turbo-preview"),
description="You help people write movie ideas.",
output_model=MovieScript,
)
pprint(movie_assistant.run("New York"))
# Version >= 2.5.0
from typing import List
from rich.pretty import pprint
from pydantic import BaseModel, Field
from phi.agent import Agent, RunResponse
from phi.model.openai import OpenAIChat
class MovieScript(BaseModel):
setting: str = Field(..., description="Provide a nice setting for a blockbuster movie.")
ending: str = Field(..., description="Ending of the movie. If not available, provide a happy ending.")
genre: str = Field(
..., description="Genre of the movie. If not available, select action, thriller or romantic comedy."
)
name: str = Field(..., description="Give a name to this movie")
characters: List[str] = Field(..., description="Name of characters for this movie.")
storyline: str = Field(..., description="3 sentence storyline for the movie. Make it exciting!")
# Agent that uses JSON mode
json_mode_agent = Agent(
model=OpenAIChat(id="gpt-4o"),
description="You write movie scripts.",
response_model=MovieScript,
)
# Print the response
json_mode_agent.print_response("New York")
# Get the response in a variable
json_mode_response: RunResponse = json_mode_agent.run("New York")
pprint(json_mode_response.content)
# Agent that uses structured outputs
# Note: `structured_output` only works with OpenAI models
structured_output_agent = Agent(
model=OpenAIChat(id="gpt-4o-2024-08-06"),
description="You write movie scripts.",
response_model=MovieScript,
structured_outputs=True,
)
# Print the response
structured_output_agent.print_response("New York")
# Get the response in a variable
structured_output_response: RunResponse = structured_output_agent.run("New York")
pprint(structured_output_response.content)
```
# Anthropic Claude
Source: https://docs.phidata.com/models/anthropic
Claude is a family of foundational AI models by Anthropic that can be used in a variety of applications.
## Authentication
Set your `ANTHROPIC_API_KEY` environment. You can get one [from Anthropic here](https://anthropic.com/).
```bash Mac
export ANTHROPIC_API_KEY=***
```
```bash Windows
setx ANTHROPIC_API_KEY ***
```
## Example
Use `Claude` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.anthropic import Claude
agent = Agent(
model=Claude(id="claude-3-5-sonnet-20240620"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response on the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
# AWS Bedrock Claude
Source: https://docs.phidata.com/models/aws-bedrock
Use AWS Bedrock to access the Claude models.
## Authentication
Set your `AWS_ACCESS_KEY_ID`, `AWS_SECRET_ACCESS_KEY` and `AWS_DEFAULT_REGION` environment variables. Get your keys from [here](https://us-west-2.console.aws.amazon.com/bedrock/home?region=us-west-2#/models).
```bash Mac
export AWS_ACCESS_KEY_ID=***
export AWS_SECRET_ACCESS_KEY=***
export AWS_DEFAULT_REGION=***
```
```bash Windows
setx AWS_ACCESS_KEY_ID ***
setx AWS_SECRET_ACCESS_KEY ***
setx AWS_DEFAULT_REGION ***
```
## Example
Use `AWS BedrockClaude` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.aws.claude import Claude
agent = Agent(
model=Claude(id="anthropic.claude-3-5-sonnet-20240620-v1:0"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response on the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
# Azure
Source: https://docs.phidata.com/models/azure
Use the best in class GPT models using Azure's OpenAI API.
## Authentication
Set your environment variables.
```bash Mac
export AZURE_OPENAI_API_KEY=***
export AZURE_OPENAI_ENDPOINT=***
export AZURE_OPENAI_MODEL_NAME=***
export AZURE_OPENAI_DEPLOYMENT=***
# Optional:
# export AZURE_OPENAI_API_VERSION=***
```
```bash Windows
setx AZURE_OPENAI_API_KEY ***
setx AZURE_OPENAI_ENDPOINT ***
setx AZURE_OPENAI_MODEL_NAME ***
setx AZURE_OPENAI_DEPLOYMENT ***
# Optional:
# setx AZURE_OPENAI_API_VERSION ***
```
## Example
Use `AzureOpenAIChat` with your `Agent`:
```python agent.py
import os
from typing import Iterator
from phi.agent import Agent, RunResponse
from phi.model.azure import AzureOpenAIChat
azure_model = AzureOpenAIChat(
id=os.getenv("AZURE_OPENAI_MODEL_NAME"),
api_key=os.getenv("AZURE_OPENAI_API_KEY"),
azure_endpoint=os.getenv("AZURE_OPENAI_ENDPOINT"),
azure_deployment=os.getenv("AZURE_OPENAI_DEPLOYMENT"),
)
agent = Agent(
model=azure_model,
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response on the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
Azure also supports the params of [OpenAI](/models/openai).
# Cohere
Source: https://docs.phidata.com/models/cohere
Leverage Cohere's powerful command models and more.
## Authentication
Set your `CO_API_KEY` environment variable. Get your key from [here](https://dashboard.cohere.com/api-keys).
```bash Mac
export CO_API_KEY=***
```
```bash Windows
setx CO_API_KEY ***
```
## Example
Use `CohereChat` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.cohere import CohereChat
agent = Agent(
model=CohereChat(id="command-r-08-2024"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
# DeepSeek
Source: https://docs.phidata.com/models/deepseek
DeepSeek is a platform for providing endpoints for Large Language models.
## Authentication
Set your `DEEPSEEK_API_KEY` environment variable. Get your key from [here](https://platform.deepseek.com/api_keys).
```bash Mac
export DEEPSEEK_API_KEY=***
```
```bash Windows
setx DEEPSEEK_API_KEY ***
```
## Example
Use `DeepSeek` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.deepseek import DeepSeekChat
agent = Agent(model=DeepSeekChat(), markdown=True)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
DeepSeek also supports the params of [OpenAI](/models/openai).
# Fireworks
Source: https://docs.phidata.com/models/fireworks
Fireworks is a platform for providing endpoints for Large Language models.
## Authentication
Set your `FIREWORKS_API_KEY` environment variable. Get your key from [here](https://fireworks.ai/account/api-keys).
```bash Mac
export FIREWORKS_API_KEY=***
```
```bash Windows
setx FIREWORKS_API_KEY ***
```
## Example
Use `Fireworks` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.fireworks import Fireworks
agent = Agent(
model=Fireworks(id="accounts/fireworks/models/firefunction-v2"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
Fireworks also supports the params of [OpenAI](/models/openai).
# Gemini - AI Studio
Source: https://docs.phidata.com/models/google
Use Google's AI Studio to access the Gemini and Gemma models.
## Authentication
Set your `GOOGLE_API_KEY` environment variable. You can get one [from Google here](https://ai.google.dev/aistudio).
```bash Mac
export GOOGLE_API_KEY=***
```
```bash Windows
setx GOOGLE_API_KEY ***
```
## Example
Use `Gemini` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.google import Gemini
agent = Agent(
model=Gemini(id="gemini-1.5-flash"),
markdown=True,
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
# Groq
Source: https://docs.phidata.com/models/groq
Groq offers blazing-fast API endpoints for large language models
## Authentication
Set your `GROQ_API_KEY` environment variable. Get your key from [here](https://console.groq.com/keys).
```bash Mac
export GROQ_API_KEY=***
```
```bash Windows
setx GROQ_API_KEY ***
```
## Example
Use `Groq` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.groq import Groq
agent = Agent(
model=Groq(id="llama-3.3-70b-versatile"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
# HuggingFace
Source: https://docs.phidata.com/models/huggingface
## Authentication
Set your `HF_TOKEN` environment. You can get one [from HuggingFace here](https://huggingface.co/settings/tokens).
```bash Mac
export HF_TOKEN=***
```
```bash Windows
setx HF_TOKEN ***
```
## Example
Use `HuggingFace` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.huggingface import HuggingFaceChat
agent = Agent(
model=HuggingFaceChat(
id="meta-llama/Meta-Llama-3-8B-Instruct",
max_tokens=4096,
),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response on the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
# Introduction
Source: https://docs.phidata.com/models/introduction
Language Models are machine-learning programs that are trained to understand natural language and code. They provide reasoning and planning capabilities to Agents.
Use any `model` with an Agent like:
```python
from phi.agent import Agent
from phi.model.openai import OpenAIChat
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
description="Share 15 minute healthy recipes.",
markdown=True,
)
agent.print_response("Share a breakfast recipe.", stream=True)
```
Phidata supports the following model providers:
* [OpenAI](/models/openai)
* [Anthropic](/models/anthropic)
* [AWS Bedrock](/models/aws-bedrock)
* [Azure](/models/azure)
* [Cohere](/models/cohere)
* [DeepSeek](/models/deepseek)
* [Fireworks](/models/fireworks)
* [Google](/models/google)
* [Groq](/models/groq)
* [Mistral](/models/mistral)
* [Ollama](/models/ollama)
* [OpenAI Like](/models/openai-like)
* [OpenRouter](/models/openrouter)
* [Sambanova](/models/sambanova)
* [Together](/models/together)
* [VertexAI](/models/vertexai)
# Mistral
Source: https://docs.phidata.com/models/mistral
Mistral is a platform for providing endpoints for Large Language models.
## Authentication
Set your `MISTRAL_API_KEY` environment variable. Get your key from [here](https://console.mistral.ai/api-keys/).
```bash Mac
export MISTRAL_API_KEY=***
```
```bash Windows
setx MISTRAL_API_KEY ***
```
## Example
Use `Mistral` with your `Agent`:
```python agent.py
import os
from phi.agent import Agent, RunResponse
from phi.model.mistral import MistralChat
mistral_api_key = os.getenv("MISTRAL_API_KEY")
agent = Agent(
model=MistralChat(
id="mistral-large-latest",
api_key=mistral_api_key,
),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
# Nvidia
Source: https://docs.phidata.com/models/nvidia
## Authentication
Set your `NVIDIA_API_KEY` environment variable. Get your key [from Nvidia here](https://build.nvidia.com/explore/discover).
```bash Mac
export NVIDIA_API_KEY=***
```
```bash Windows
setx NVIDIA_API_KEY ***
```
## Example
Use `Nvidia` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.nvidia import Nvidia
agent = Agent(model=Nvidia(), markdown=True)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story")
```
## Params
Nvidia also supports the params of [OpenAI](/models/openai).
# Ollama
Source: https://docs.phidata.com/models/ollama
Run Large Language Models locally with Ollama
[Ollama](https://ollama.com) is a fantastic tool for running models locally. Install [ollama](https://ollama.com) and run a model using
```bash run model
ollama run llama3.1
```
```bash serve
ollama serve
```
After you have the local model running, use the `Ollama` model to access them
## Example
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.ollama import Ollama
agent = Agent(
model=Ollama(id="llama3.1"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
# OpenAI
Source: https://docs.phidata.com/models/openai
The GPT models are the best in class LLMs and used as the default LLM by **Agents**.
## Authentication
Set your `OPENAI_API_KEY` environment variable. You can get one [from OpenAI here](https://platform.openai.com/account/api-keys).
```bash Mac
export OPENAI_API_KEY=sk-***
```
```bash Windows
setx OPENAI_API_KEY sk-***
```
## Example
Use `OpenAIChat` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.openai import OpenAIChat
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
For more information, please refer to the [OpenAI docs](https://platform.openai.com/docs/api-reference/chat/create) as well.
# OpenAI Like
Source: https://docs.phidata.com/models/openai-like
Many providers like Together, Groq, Sambanova, etc support the OpenAI API format. Use the `OpenAILike` model to access them by replacing the `base_url`.
## Example
```python agent.py
from os import getenv
from phi.agent import Agent, RunResponse
from phi.model.openai.like import OpenAILike
agent = Agent(
model=OpenAILike(
id="mistralai/Mixtral-8x7B-Instruct-v0.1",
api_key=getenv("TOGETHER_API_KEY"),
base_url="https://api.together.xyz/v1",
)
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
`OpenAILike` also support all the params of [OpenAIChat](/models/openai)
# OpenRouter
Source: https://docs.phidata.com/models/openrouter
OpenRouter is a platform for providing endpoints for Large Language models.
## Authentication
Set your `OPENROUTER_API_KEY` environment variable. Get your key from [here](https://openrouter.ai/settings/keys).
```bash Mac
export OPENROUTER_API_KEY=***
```
```bash Windows
setx OPENROUTER_API_KEY ***
```
## Example
Use `OpenRouter` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.openrouter import OpenRouter
agent = Agent(
model=OpenRouter(id="gpt-4o"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
OpenRouter also supports the params of [OpenAI](/models/openai).
# Sambanova
Source: https://docs.phidata.com/models/sambanova
Sambanova is a platform for providing endpoints for Large Language models. Note that Sambanova currently does not support function calling.
## Authentication
Set your `SAMBANOVA_API_KEY` environment variable. Get your key from [here](https://cloud.sambanova.ai/apis).
```bash Mac
export SAMBANOVA_API_KEY=***
```
```bash Windows
setx SAMBANOVA_API_KEY ***
```
## Example
Use `Sambanova` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.sambanova import Sambanova
agent = Agent(model=Sambanova(), markdown=True)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
Sambanova also supports the params of [OpenAI](/models/openai).
# Together
Source: https://docs.phidata.com/models/together
Together is a platform for providing endpoints for Large Language models.
## Authentication
Set your `TOGETHER_API_KEY` environment variable. Get your key [from Together here](https://api.together.xyz/settings/api-keys).
```bash Mac
export TOGETHER_API_KEY=***
```
```bash Windows
setx TOGETHER_API_KEY ***
```
## Example
Use `Together` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.together import Together
agent = Agent(
model=Together(id="meta-llama/Meta-Llama-3.1-8B-Instruct-Turbo"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
Together also supports the params of [OpenAI](/models/openai).
# Gemini - VertexAI
Source: https://docs.phidata.com/models/vertexai
`VertexAI` is Google's cloud platform for building, training, and deploying machine learning models.
## Authentication
[Authenticate with Gcloud](https://cloud.google.com/vertex-ai/generative-ai/docs/start/quickstarts/quickstart-multimodal)
## Example
Use `Gemini` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.vertexai import Gemini
agent = Agent(
model=Gemini(id="gemini-1.5-flash"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response on the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
| Parameter | Type | Default | Description |
| ---------------- | --------------------------- | ------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `id` | `str` | `"claude-3-5-sonnet-20240620"` | The specific model ID used for generating responses. |
| `name` | `str` | `"Claude"` | The name identifier for the agent. |
| `provider` | `str` | `"Anthropic"` | The provider of the model. |
| `max_tokens` | `Optional[int]` | `1024` | The maximum number of tokens to generate in the response. |
| `temperature` | `Optional[float]` | - | The sampling temperature to use, between 0 and 2. Higher values like 0.8 make the output more random, while lower values like 0.2 make it more focused and deterministic. |
| `stop_sequences` | `Optional[List[str]]` | - | A list of sequences where the API will stop generating further tokens. |
| `top_p` | `Optional[float]` | - | Nucleus sampling parameter. The model considers the results of the tokens with top\_p probability mass. |
| `top_k` | `Optional[int]` | - | The number of highest probability vocabulary tokens to keep for top-k-filtering. |
| `request_params` | `Optional[Dict[str, Any]]` | - | Additional parameters to include in the request. |
| `api_key` | `Optional[str]` | - | The API key for authenticating requests to the service. |
| `client_params` | `Optional[Dict[str, Any]]` | - | Additional parameters for client configuration. |
| `client` | `Optional[AnthropicClient]` | - | A pre-configured instance of the Anthropic client. |
# xAI
Source: https://docs.phidata.com/models/xai
xAI is a platform for providing endpoints for Large Language models.
## Authentication
Set your `XAI_API_KEY` environment variable. You can get one [from xAI here](https://console.x.ai/).
```bash Mac
export XAI_API_KEY=sk-***
```
```bash Windows
setx XAI_API_KEY sk-***
```
## Example
Use `xAI` with your `Agent`:
```python agent.py
from phi.agent import Agent, RunResponse
from phi.model.xai import xAI
agent = Agent(
model=xAI(id="grok-beta"),
markdown=True
)
# Get the response in a variable
# run: RunResponse = agent.run("Share a 2 sentence horror story.")
# print(run.content)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story.")
```
## Params
For more information, please refer to the [xAI docs](https://docs.x.ai/docs) as well.
## Params
xAI also supports the params of [OpenAI](/models/openai).
# Monitoring
Source: https://docs.phidata.com/monitoring
Phidata comes with built-in monitoring and debugging.
You can set `monitoring=True` on any agent to log that agent's sessions or set `PHI_MONITORING=true` in your environment to log all agent sessions.
Create a file `monitoring.py` with the following code:
```python monitoring.py
from phi.agent import Agent
agent = Agent(markdown=True, monitoring=True)
agent.print_response("Share a 2 sentence horror story")
```
### Run the agent
Run the agent and view the session on [phidata.app/sessions](https://www.phidata.app/sessions)
```shell
python monitoring.py
```
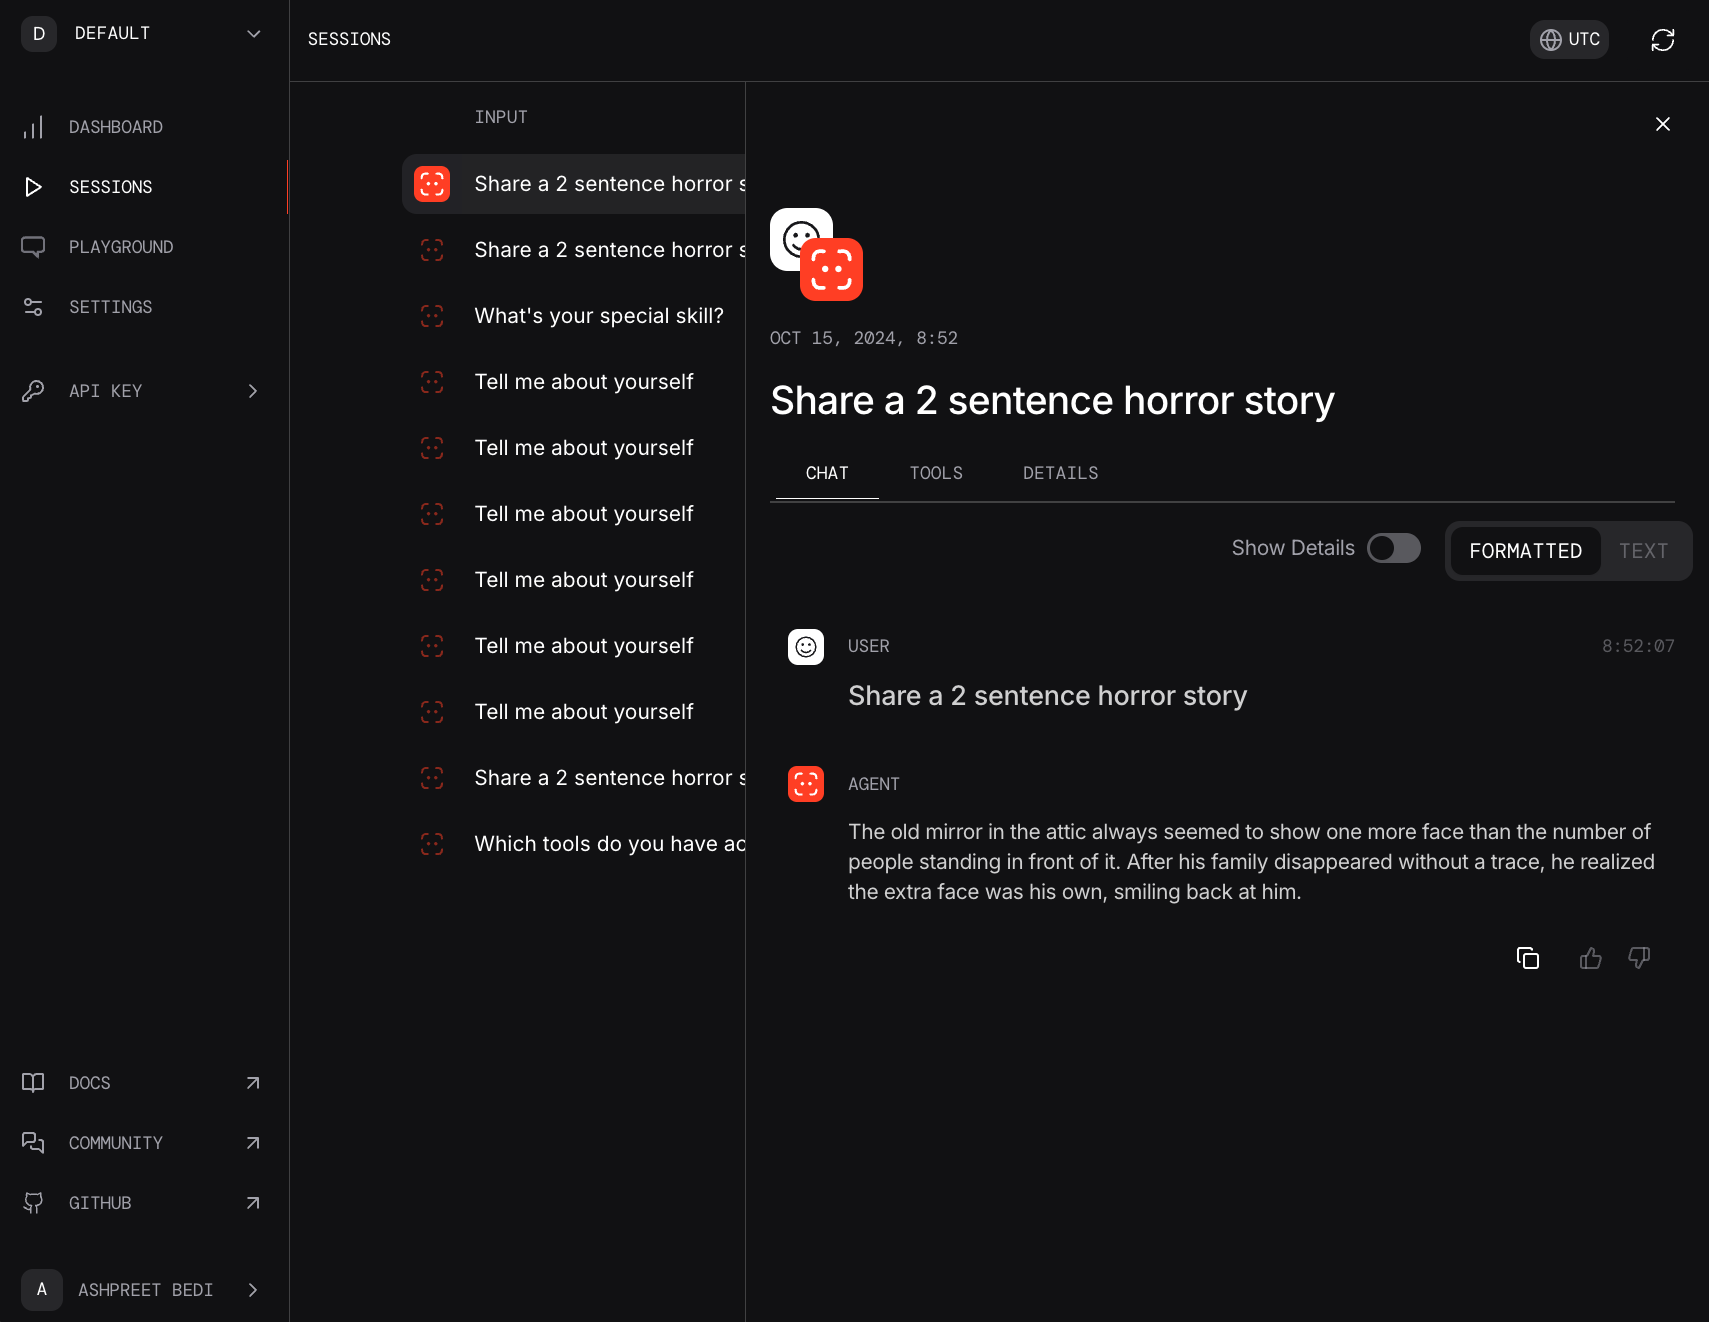 ## Debugging
Phidata also includes a built-in debugger that will show debug logs in the terminal. You can set `debug_mode=True` on any agent to view debug logs or set `PHI_DEBUG=true` in your environment.
```python debugging.py
from phi.agent import Agent
agent = Agent(markdown=True, debug_mode=True)
agent.print_response("Share a 2 sentence horror story")
```
Run the agent to view debug logs in the terminal:
```shell
python debugging.py
```
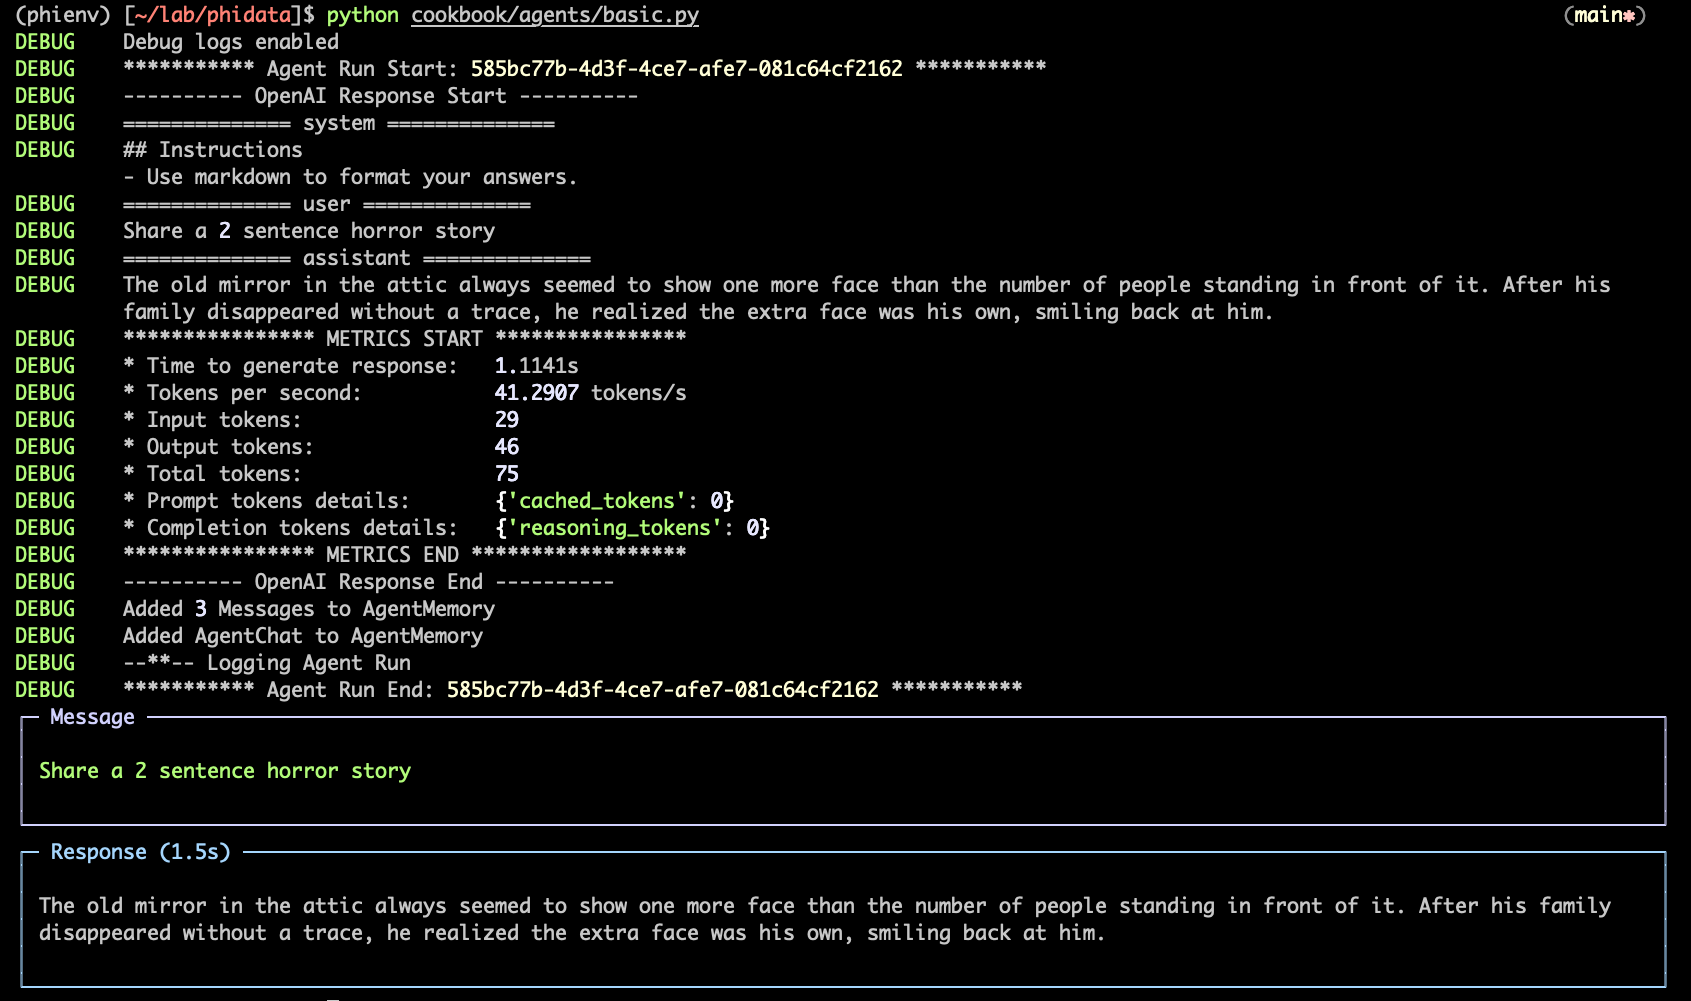 # Examples
Source: https://docs.phidata.com/more-examples
## Research Agent
Let's build a research agent to generate a report using Exa.
```python research_agent.py
from textwrap import dedent
from datetime import datetime
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.exa import ExaTools
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
tools=[ExaTools(start_published_date=datetime.now().strftime("%Y-%m-%d"), type="keyword")],
description="You are an advanced AI researcher writing a report on a topic.",
instructions=[
"For the provided topic, run 3 different searches.",
"Read the results carefully and prepare a NYT worthy report.",
"Focus on facts and make sure to provide references.",
],
expected_output=dedent("""\
An engaging, informative, and well-structured report in markdown format:
## Engaging Report Title
### Overview
{give a brief introduction of the report and why the user should read this report}
{make this section engaging and create a hook for the reader}
### Section 1
{break the report into sections}
{provide details/facts/processes in this section}
... more sections as necessary...
### Takeaways
{provide key takeaways from the article}
### References
- [Reference 1](link)
- [Reference 2](link)
- [Reference 3](link)
- published on {date} in dd/mm/yyyy
"""),
markdown=True,
show_tool_calls=True,
add_datetime_to_instructions=True,
save_response_to_file="tmp/{message}.md",
)
agent.print_response("Simulation theory", stream=True)
```
Install libraries
```shell
pip install openai exa-py phidata
```
Run the agent
```shell
python research_agent.py
```
View the report
```shell
cat tmp/Simulation theory.md
```
## Agentic RAG
We were the first to pioneer Agentic RAG using our Auto-RAG paradigm. With Agentic RAG (or auto-rag), the Agent can search its knowledge base (vector db) for the specific information it needs to achieve its task, instead of always inserting the "context" into the prompt.
This saves tokens and improves response quality.
```python rag_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.embedder.openai import OpenAIEmbedder
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.lancedb import LanceDb, SearchType
# Create a knowledge base from a PDF
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
# Use LanceDB as the vector database
vector_db=LanceDb(
table_name="recipes",
uri="tmp/lancedb",
search_type=SearchType.vector,
embedder=OpenAIEmbedder(model="text-embedding-3-small"),
),
)
# Comment out after first run as the knowledge base is loaded
knowledge_base.load()
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
# Add the knowledge base to the agent
knowledge=knowledge_base,
show_tool_calls=True,
markdown=True,
)
agent.print_response("How do I make chicken and galangal in coconut milk soup", stream=True)
```
Install libraries
```shell
pip install lancedb tantivy pypdf sqlalchemy
```
Run the agent
```shell
python rag_agent.py
```
## Structured Outputs
Agents can return their output in a structured format as a Pydantic model.
Create a file `structured_output.py`
```python structured_output.py
from typing import List
from pydantic import BaseModel, Field
from phi.agent import Agent
from phi.model.openai import OpenAIChat
# Define a Pydantic model to enforce the structure of the output
class MovieScript(BaseModel):
setting: str = Field(..., description="Provide a nice setting for a blockbuster movie.")
ending: str = Field(..., description="Ending of the movie. If not available, provide a happy ending.")
genre: str = Field(..., description="Genre of the movie. If not available, select action, thriller or romantic comedy.")
name: str = Field(..., description="Give a name to this movie")
characters: List[str] = Field(..., description="Name of characters for this movie.")
storyline: str = Field(..., description="3 sentence storyline for the movie. Make it exciting!")
# Agent that uses JSON mode
json_mode_agent = Agent(
model=OpenAIChat(id="gpt-4o"),
description="You write movie scripts.",
response_model=MovieScript,
)
# Agent that uses structured outputs
structured_output_agent = Agent(
model=OpenAIChat(id="gpt-4o"),
description="You write movie scripts.",
response_model=MovieScript,
structured_outputs=True,
)
json_mode_agent.print_response("New York")
structured_output_agent.print_response("New York")
```
```shell
python structured_output.py
```
## Reasoning Agent
Reasoning is an experimental feature that helps agents work through a problem step-by-step, backtracking and correcting as needed.
```python reasoning_agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
task = (
"Three missionaries and three cannibals need to cross a river. "
"They have a boat that can carry up to two people at a time. "
"If, at any time, the cannibals outnumber the missionaries on either side of the river, the cannibals will eat the missionaries. "
"How can all six people get across the river safely? Provide a step-by-step solution and show the solutions as an ascii diagram"
)
reasoning_agent = Agent(model=OpenAIChat(id="gpt-4o"), reasoning=True, markdown=True, structured_outputs=True)
reasoning_agent.print_response(task, stream=True, show_full_reasoning=True)
```
```shell
python reasoning_agent.py
```
Reasoning is an experimental feature and will break \~20% of the time. **It is not a replacement for o1.** It is an experiment that combines COT and tool use. Set your expectations very low for this initial release. For example: It will not be able to count ‘r’s in ‘strawberry’.
# Agent
Source: https://docs.phidata.com/reference/agent
The `Agent` class provides an easy to use interface to language models.
## Example
```python agent.py
from phi.agent import Agent
agent = Agent(description="You help people with their health and fitness goals.")
# -*- Print a response
agent.print_response('Share a quick healthy breakfast recipe.', markdown=True)
# -*- Get the response as a string
response = agent.run('Share a quick healthy breakfast recipe.', stream=False)
# -*- Get the response as a stream
response = ""
for delta in agent.run('Share a quick healthy breakfast recipe.'):
response += delta
```
## Agent Params
# DuckDb Agent
Source: https://docs.phidata.com/reference/agents/duckdb
## Example
```python duckdb_agent.py
import json
from phi.agent.duckdb import DuckDbAgent
tables = [
{
"name": "movies",
"description": "Contains information about movies from IMDB.",
"path": "s3://phidata-public/demo_data/IMDB-Movie-Data.csv",
},
]
duckdb_agent = DuckDbAgent(
show_function_calls=True,
semantic_model=json.dumps({"tables": tables}, indent=4),
)
duckdb_agent.print_response("What is the average rating of movies?")
```
## DuckDbAgent Params
| Parameter | Type | Default | Description |
| ------------------------- | ------------------------------------- | --------------- | ----------------------------------------------------------------------------------------------------------------------------------- |
| `name` | `str` | `"DuckDbAgent"` | Name of the agent. |
| `semantic_model` | `Optional[str]` | `None` | Semantic model for the agent. Use this to describe the available tables, their description, data path and relations between tables. |
| `add_history_to_messages` | `bool` | `True` | If the chat history should be added to the messages. |
| `followups` | `bool` | `False` | If the DuckDbAgent is allowed to run followup queries. |
| `read_tool_call_history` | `bool` | `True` | If the DuckDbAgent is allowed to read the tool call history. |
| `db_path` | `Optional[str]` | `None` | Path to the DuckDb database file. |
| `connection` | `Optional[duckdb.DuckDBPyConnection]` | `None` | Provide an existing duckdb connection. |
| `init_commands` | `Optional[List]` | `None` | Commands ran when the duckdb connection is initialized. |
| `read_only` | `bool` | `False` | If the database is read-only. |
| `config` | `Optional[dict]` | `None` | Database config used to initialize the duckdb connection. |
| `run_queries` | `bool` | `True` | If the DuckDbAgent is allowed to run queries. |
| `inspect_queries` | `bool` | `True` | If the DuckDbAgent is allowed to inspect queries. |
| `create_tables` | `bool` | `True` | If the DuckDbAgent is allowed to create tables. |
| `summarize_tables` | `bool` | `True` | If the DuckDbAgent is allowed to summarize tables. |
| `export_tables` | `bool` | `True` | If the DuckDbAgent is allowed to export tables. |
| `base_dir` | `Optional[Path]` | `None` | Where to save SQL files if needed. |
| `save_files` | `bool` | `True` | If the DuckDbAgent is allowed to save SQL files. |
| `read_files` | `bool` | `False` | If the DuckDbAgent is allowed to read SQL files. |
| `list_files` | `bool` | `False` | If the DuckDbAgent is allowed to list SQL files. |
## Agent Reference
`DuckDbAgent` is a subclass of the `Agent` class and has access to the same params
# PythonAgent
Source: https://docs.phidata.com/reference/agents/python
## Example
```python python_agent.py
from phi.agent.python import PythonAgent
from phi.file.local.csv import CsvFile
python_agent = PythonAgent(
files=[
CsvFile(
path="https://phidata-public.s3.amazonaws.com/demo_data/IMDB-Movie-Data.csv",
description="Contains information about movies from IMDB.",
)
],
pip_install=True,
show_function_calls=True,
)
python_agent.print_response("What is the average rating of movies?")
```
## PythonAgent Params
| Parameter | Type | Default | Description |
| ------------------------------ | ------------ | ------------------------------------- | ---------------------------------------------------------------------------------------------------- |
| `name` | `str` | `"PythonAgent"` | Name of the PythonAgent. |
| `files` | `List[File]` | `None` | List of Files available for the PythonAgent. |
| `file_information` | `str` | `None` | Provide information about Files as a string. |
| `charting_libraries` | `List[str]` | `['plotly', 'matplotlib', 'seaborn']` | List of charting libraries the PythonAgent can use. |
| `followups` | `bool` | `False` | If the PythonAgent is allowed to ask follow-up questions. |
| `read_tool_call_history` | `bool` | `True` | If the DuckDbAgent is allowed to read the tool call history. |
| `base_dir` | `Path` | `.` | Where to save files if needed. |
| `save_and_run` | `bool` | `True` | If the PythonAgent is allowed to save and run python code. |
| `pip_install` | `bool` | `False` | If the PythonAgent is allowed to `pip install` libraries. Disabled by default for security reasons. |
| `run_code` | `bool` | `False` | If the PythonAgent is allowed to run python code directly. Disabled by default for security reasons. |
| `list_files` | `bool` | `False` | If the PythonAgent is allowed to list files. |
| `run_files` | `bool` | `True` | If the PythonAgent is allowed to run files. |
| `read_files` | `bool` | `False` | If the PythonAgent is allowed to read files. |
| `safe_globals` | `dict` | `None` | Provide a list of global variables to for the PythonAgent. |
| `safe_locals` | `dict` | `None` | Provide a list of local variables to for the PythonAgent. |
| `add_chat_history_to_messages` | `bool` | `True` | If the chat history should be added to the messages. |
| `num_history_messages` | `int` | `6` | Number of history messages to add to the response. |
## Agent Reference
`PythonAgent` is a subclass of the `Agent` class and has access to the same params
# phi auth
Source: https://docs.phidata.com/reference/cli/phi/auth
Authenticate with phidata.com
## Params
Print debug logs. `--debug` `-d`
# phi config
Source: https://docs.phidata.com/reference/cli/phi/config
Print phi config
## Params
Print debug logs. `--debug` `-d`
Show all workspaces `--all` `-a`
# phi init
Source: https://docs.phidata.com/reference/cli/phi/init
Initialize phidata, use -r to reset
## Params
Reset phidata `--reset` `-r`
Print debug logs. `--debug` `-d`
Login with phidata.com `--login` `-l`
# phi patch
Source: https://docs.phidata.com/reference/cli/phi/patch
Update resources defined in a resources.py file
## Params
Path to workspace file.
Filter the environment to deploy `--env` `-e`
Filter the infra to deploy. `--infra` `-i`
Filter the config to deploy. `--config` `-c`
Filter resources using group name. `--group` `-g`
Filter resource using name. `--name` `-n`
Filter resource using type `--type` `-t`
Print resources and exit. `--dry-run` `-dr`
Skip the confirmation before deploying resources. `--yes` `-y`
Print debug logs. `--debug` `-d`
Force `--force` `-f`
# phi reset
Source: https://docs.phidata.com/reference/cli/phi/reset
Reset phi installation
## Params
Print debug logs. `--debug` `-d`
# phi restart
Source: https://docs.phidata.com/reference/cli/phi/restart
Restart resources defined in a resources.py file
## Params
Path to workspace file.
Filter the environment to deploy `--env` `-e`
Filter the infra to deploy. `--infra` `-i`
Filter the config to deploy. `--config` `-c`
Filter resources using group name. `--group` `-g`
Filter resource using name. `--name` `-n`
Filter resource using type `--type` `-t`
Print resources and exit. `--dry-run` `-dr`
Skip the confirmation before deploying resources. `--yes` `-y`
Print debug logs. `--debug` `-d`
Force `--force` `-f`
# phi set
Source: https://docs.phidata.com/reference/cli/phi/set
Set current directory as active workspace
## Params
Active workspace name `--ws`
Print debug logs. `--debug` `-d`
# phi start
Source: https://docs.phidata.com/reference/cli/phi/start
Start resources defined in a resources.py file
## Params
Path to workspace file.
Filter the environment to deploy `--env` `-e`
Filter the infra to deploy. `--infra` `-i`
Filter the config to deploy. `--config` `-c`
Filter resources using group name. `--group` `-g`
Filter resource using name. `--name` `-n`
Filter resource using type `--type` `-t`
Print resources and exit. `--dry-run` `-dr`
Skip the confirmation before deploying resources. `--yes` `-y`
Print debug logs. `--debug` `-d`
Force `--force` `-f`
# phi stop
Source: https://docs.phidata.com/reference/cli/phi/stop
Stop resources defined in a resources.py file
## Params
Path to workspace file.
Filter the environment to deploy `--env` `-e`
Filter the infra to deploy. `--infra` `-i`
Filter the config to deploy. `--config` `-c`
Filter resources using group name. `--group` `-g`
Filter resource using name. `--name` `-n`
Filter resource using type `--type` `-t`
Print resources and exit. `--dry-run` `-dr`
Skip the confirmation before deploying resources. `--yes` `-y`
Print debug logs. `--debug` `-d`
Force `--force` `-f`
# phi ws config
Source: https://docs.phidata.com/reference/cli/ws/config
Prints active workspace config
## Params
Print debug logs. `--debug` `-d`
# phi ws create
Source: https://docs.phidata.com/reference/cli/ws/create
Create a new workspace in the current directory.
## Params
Name of the new workspace. `--name` `-n`
Starter template for the workspace. `--template` `-t`
URL of the starter template. `--url` `-u`
Print debug logs. `--debug` `-d`
# phi ws delete
Source: https://docs.phidata.com/reference/cli/ws/delete
Delete workspace record
## Params
Name of the workspace to delete `-ws`
Delete all workspaces from phidata `--all` `-a`
Print debug logs. `--debug` `-d`
# phi ws down
Source: https://docs.phidata.com/reference/cli/ws/down
Delete resources for active workspace
## Params
Resource filter. Format - ENV:INFRA:GROUP:NAME:TYPE
Filter the environment to deploy `--env` `-e`
Filter the infra to deploy. `--infra` `-i`
Filter the config to deploy. `--config` `-c`
Filter resources using group name. `--group` `-g`
Filter resource using name. `--name` `-n`
Filter resource using type `--type` `-t`
Print resources and exit. `--dry-run` `-dr`
Skip the confirmation before deploying resources. `--yes` `-y`
Print debug logs. `--debug` `-d`
Force `--force` `-f`
# phi ws patch
Source: https://docs.phidata.com/reference/cli/ws/patch
Update resources for active workspace
## Params
Resource filter. Format - ENV:INFRA:GROUP:NAME:TYPE
Filter the environment to deploy `--env` `-e`
Filter the infra to deploy. `--infra` `-i`
Filter the config to deploy. `--config` `-c`
Filter resources using group name. `--group` `-g`
Filter resource using name. `--name` `-n`
Filter resource using type `--type` `-t`
Print resources and exit. `--dry-run` `-dr`
Skip the confirmation before deploying resources. `--yes` `-y`
Print debug logs. `--debug` `-d`
Force `--force` `-f`
Pull `--pull` `-p`
# phi ws restart
Source: https://docs.phidata.com/reference/cli/ws/restart
Restart resources for active workspace
## Params
Resource filter. Format - ENV:INFRA:GROUP:NAME:TYPE
Filter the environment to deploy `--env` `-e`
Filter the infra to deploy. `--infra` `-i`
Filter the config to deploy. `--config` `-c`
Filter resources using group name. `--group` `-g`
Filter resource using name. `--name` `-n`
Filter resource using type `--type` `-t`
Print resources and exit. `--dry-run` `-dr`
Skip the confirmation before deploying resources. `--yes` `-y`
Print debug logs. `--debug` `-d`
Force `--force` `-f`
Pull `--pull` `-p`
# phi ws setup
Source: https://docs.phidata.com/reference/cli/ws/setup
Setup workspace from the current directory
## Params
Path to workspace \[default: current directory]
Print debug logs. `--debug` `-d`
# phi ws up
Source: https://docs.phidata.com/reference/cli/ws/up
Create resources for the active workspace
## Params
Resource filter. Format - ENV:INFRA:GROUP:NAME:TYPE
Filter the environment to deploy `--env` `-e`
Filter the infra to deploy. `--infra` `-i`
Filter the config to deploy. `--config` `-c`
Filter resources using group name. `--group` `-g`
Filter resource using name. `--name` `-n`
Filter resource using type `--type` `-t`
Print resources and exit. `--dry-run` `-dr`
Skip the confirmation before deploying resources. `--yes` `-y`
Print debug logs. `--debug` `-d`
Force `--force` `-f`
Pull `--pull` `-p`
# Arxiv KnowledgeBase
Source: https://docs.phidata.com/reference/kb/arxiv
## Example
Install `arxiv` using [this guide](/how-to/install)
```python knowledge_base.py
from phi.knowledge.arxiv import ArxivKnowledgeBase
from phi.vectordb.pgvector import PgVector
from resources import vector_db
knowledge_base = ArxivKnowledgeBase(
queries=["Generative AI", "Machine Learning"],
# Table name: llm.arxiv_documents
vector_db=PgVector(
table_name="arxiv_documents",
db_url=vector_db.get_db_connection_local(),
),
)
```
## ArxivKnowledgeBase Params
| Parameter | Type | Default | Description |
| --------- | ------------- | --------------- | -------------------------------------------------------------------------------------------------- |
| `queries` | `List[str]` | `[]` | Queries to search |
| `reader` | `ArxivReader` | `ArxivReader()` | A `ArxivReader` that reads the articles and converts them into `Documents` for the vector database |
## AgentKnowledge Params
`ArxivKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# AgentKnowledge
Source: https://docs.phidata.com/reference/kb/base
## AgentKnowledge Params
# Combined KnowledgeBase
Source: https://docs.phidata.com/reference/kb/combined
## Example
```python knowledge_base.py
from phi.knowledge.combined import CombinedKnowledgeBase
from phi.vectordb.pgvector import PgVector
from resources import vector_db
knowledge_base = CombinedKnowledgeBase(
sources=[
url_pdf_knowledge_base,
website_knowledge_base,
local_pdf_knowledge_base,
],
vector_db=PgVector(
# Table name: llm.combined_documents
table_name="combined_documents",
db_url=vector_db.get_db_connection_local(),
),
)
```
## CombinedKnowledgeBase Params
| Parameter | Type | Default | Description |
| --------- | ---------------------- | ------- | ------------------------ |
| `sources` | `List[AgentKnowledge]` | `[]` | List of knowledge bases. |
## AgentKnowledge Params
`CombinedKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# CSV KnowledgeBase
Source: https://docs.phidata.com/reference/kb/csv
## CSVKnowledgeBase Params
| Parameter | Type | Default | Description |
| --------- | ------------------ | ------------- | ---------------------------------------------------------------------------------------------- |
| `path` | `Union[str, Path]` | - | Path to the CSV file |
| `reader` | `CSVReader` | `CSVReader()` | A `CSVReader` that reads the CSV file and converts it into `Documents` for the vector database |
## AgentKnowledge Params
`CSVKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# Document KnowledgeBase
Source: https://docs.phidata.com/reference/kb/document
## DocumentKnowledgeBase Params
| Parameter | Type | Default | Description |
| ----------- | ---------------- | ------- | --------------------------------------------------------- |
| `documents` | `List[Document]` | - | List of Document objects to be used as the knowledge base |
## AgentKnowledge Params
`DocumentKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# Docx KnowledgeBase
Source: https://docs.phidata.com/reference/kb/docx
## Example
```python knowledge_base.py
from phi.knowledge.text import DocxKnowledgeBase
from phi.vectordb.pgvector import PgVector
from resources import vector_db
knowledge_base = DocxKnowledgeBase(
path="data/docs",
# Table name: ai.docx_documents
vector_db=PgVector(
table_name="docx_documents",
db_url=vector_db.get_db_connection_local(),
),
)
```
## DocxKnowledgeBase Params
| Parameter | Type | Default | Description |
| --------- | ------------------ | ------------------- | ------------------------------------------------------------------------------------- |
| `path` | `Union[str, Path]` | - | Path to text files. Can point to a single docx file or a directory of docx files. |
| `formats` | `List[str]` | `[".doc", ".docx"]` | Formats accepted by this knowledge base. |
| `reader` | `DocxReader` | `DocxReader()` | A `DocxReader` that converts the docx files into `Documents` for the vector database. |
## AgentKnowledge Params
`DocxKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# JSON KnowledgeBase
Source: https://docs.phidata.com/reference/kb/json
## Example
```python knowledge_base.py
from phi.knowledge.json import JSONKnowledgeBase
from phi.vectordb.pgvector import PgVector
from resources import vector_db
knowledge_base = JSONKnowledgeBase(
path="data/json",
# Table name: llm.json_documents
vector_db=PgVector(
table_name="json_documents",
db_url=vector_db.get_db_connection_local(),
),
)
```
## JSONKnowledgeBase Params
| Parameter | Type | Default | Description |
| --------- | ------------------ | -------------- | ---------------------------------------------------------------------------------------- |
| `path` | `Union[str, Path]` | - | Path to `JSON` files.
Can point to a single JSON file or a directory of JSON files. |
| `reader` | `JSONReader` | `JSONReader()` | A `JSONReader` that converts the `JSON` files into `Documents` for the vector database. |
## AgentKnowledge Params
`JSONKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# LangChain KnowledgeBase
Source: https://docs.phidata.com/reference/kb/langchain
## Example
```python langchain_kb.py
from phi.agent import Agent
from phi.knowledge.langchain import LangChainKnowledgeBase
from langchain.embeddings import OpenAIEmbeddings
from langchain.document_loaders import TextLoader
from langchain.text_splitter import CharacterTextSplitter
from langchain.vectorstores import Chroma
chroma_db_dir = "./chroma_db"
def load_vector_store():
state_of_the_union = ws_settings.ws_root.joinpath("data/demo/state_of_the_union.txt")
# -*- Load the document
raw_documents = TextLoader(str(state_of_the_union)).load()
# -*- Split it into chunks
text_splitter = CharacterTextSplitter(chunk_size=1000, chunk_overlap=0)
documents = text_splitter.split_documents(raw_documents)
# -*- Embed each chunk and load it into the vector store
Chroma.from_documents(documents, OpenAIEmbeddings(), persist_directory=str(chroma_db_dir))
# -*- Get the vectordb
db = Chroma(embedding_function=OpenAIEmbeddings(), persist_directory=str(chroma_db_dir))
# -*- Create a retriever from the vector store
retriever = db.as_retriever()
# -*- Create a knowledge base from the vector store
knowledge_base = LangChainKnowledgeBase(retriever=retriever)
agent = Agent(knowledge_base=knowledge_base, add_references_to_prompt=True)
conv.print_response("What did the president say about technology?")
```
## LangChainKnowledgeBase Params
| Parameter | Type | Default | Description |
| --------------- | -------------------- | ------- | ------------------------------------------------------------------------- |
| `loader` | `Optional[Callable]` | `None` | LangChain loader. |
| `vectorstore` | `Optional[Any]` | `None` | LangChain vector store used to create a retriever. |
| `search_kwargs` | `Optional[dict]` | `None` | Search kwargs when creating a retriever using the langchain vector store. |
| `retriever` | `Optional[Any]` | `None` | LangChain retriever. |
## AgentKnowledge Params
`LangChainKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# LlamaIndex KnowledgeBase
Source: https://docs.phidata.com/reference/kb/llamaindex
```python agent.py
"""
Import necessary modules
pip install llama-index-core llama-index-readers-file llama-index-embeddings-openai phidata
"""
from pathlib import Path
from shutil import rmtree
import httpx
from phi.agent import Agent
from phi.knowledge.llamaindex import LlamaIndexKnowledgeBase
from llama_index.core import (
SimpleDirectoryReader,
StorageContext,
VectorStoreIndex,
)
from llama_index.core.retrievers import VectorIndexRetriever
from llama_index.core.node_parser import SentenceSplitter
data_dir = Path(__file__).parent.parent.parent.joinpath("wip", "data", "paul_graham")
if data_dir.is_dir():
rmtree(path=data_dir, ignore_errors=True)
data_dir.mkdir(parents=True, exist_ok=True)
url = "https://raw.githubusercontent.com/run-llama/llama_index/main/docs/docs/examples/data/paul_graham/paul_graham_essay.txt"
file_path = data_dir.joinpath("paul_graham_essay.txt")
response = httpx.get(url)
if response.status_code == 200:
with open(file_path, "wb") as file:
file.write(response.content)
print(f"File downloaded and saved as {file_path}")
else:
print("Failed to download the file")
documents = SimpleDirectoryReader(str(data_dir)).load_data()
splitter = SentenceSplitter(chunk_size=1024)
nodes = splitter.get_nodes_from_documents(documents)
storage_context = StorageContext.from_defaults()
index = VectorStoreIndex(nodes=nodes, storage_context=storage_context)
retriever = VectorIndexRetriever(index)
# Create a knowledge base from the vector store
knowledge_base = LlamaIndexKnowledgeBase(retriever=retriever)
# Create an agent with the knowledge base
agent = Agent(knowledge_base=knowledge_base, search_knowledge=True, debug_mode=True, show_tool_calls=True)
# Use the agent to ask a question and print a response.
agent.print_response("Explain what this text means: low end eats the high end", markdown=True)
```
## LlamaIndexKnowledgeBase Params
| Parameter | Type | Default | Description |
| ----------- | -------------------- | ------- | ------------------------------------------------------------------ |
| `retriever` | `BaseRetriever` | - | LlamaIndex retriever used for querying the knowledge base |
| `loader` | `Optional[Callable]` | `None` | Optional loader function to load documents into the knowledge base |
## AgentKnowledge Params
`LlamaIndexKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# PDF KnowledgeBase
Source: https://docs.phidata.com/reference/kb/pdf
## Example
Install `pypdf` if needed using [this guide](/how-to/install)
```python knowledge_base.py
from phi.knowledge.pdf import PDFKnowledgeBase, PDFReader
from phi.vectordb.pgvector import PgVector
from resources import vector_db
pdf_knowledge_base = PDFKnowledgeBase(
path="data/pdfs",
# Table name: llm.pdf_documents
vector_db=PgVector(
table_name="pdf_documents",
db_url=vector_db.get_db_connection_local(),
),
reader=PDFReader(chunk=True),
)
```
## PDFKnowledgeBase Params
| Parameter | Type | Default | Description |
| --------- | ---------------------------------- | ------------- | ---------------------------------------------------------------------------------------------------- |
| `path` | `Union[str, Path]` | - | Path to `PDF` files. Can point to a single PDF file or a directory of PDF files. |
| `reader` | `Union[PDFReader, PDFImageReader]` | `PDFReader()` | A `PDFReader` or `PDFImageReader` that converts the `PDFs` into `Documents` for the vector database. |
## AgentKnowledge Params
`PDFKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# PDF Url KnowledgeBase
Source: https://docs.phidata.com/reference/kb/pdf-url
## Example
Install `pypdf` if needed using [this guide](/how-to/install)
```python knowledge_base.py
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector
from resources import vector_db
knowledge_base = PDFUrlKnowledgeBase(
urls=["pdf_url"],
# Table name: llm.pdf_documents
vector_db=PgVector(
table_name="pdf_documents",
db_url=vector_db.get_db_connection_local(),
),
)
```
## PDFUrlKnowledgeBase Params
| Parameter | Type | Default | Description |
| --------- | -------------- | ------- | ----------------------------------------------------------------------------------- |
| `urls` | `List[str]` | - | URLs for `PDF` files. |
| `reader` | `PDFUrlReader` | - | A `PDFUrlReader` that converts the `PDFs` into `Documents` for the vector database. |
## AgentKnowledge Params
`PDFUrlKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# Text KnowledgeBase
Source: https://docs.phidata.com/reference/kb/text
## Example
Install `textract` if needed using [this guide](/how-to/install)
```python knowledge_base.py
from phi.knowledge.text import TextKnowledgeBase
from phi.vectordb.pgvector import PgVector
from resources import vector_db
knowledge_base = TextKnowledgeBase(
path="data/docs",
# Table name: ai.text_documents
vector_db=PgVector(
table_name="text_documents",
db_url=vector_db.get_db_connection_local(),
),
)
```
## TextKnowledgeBase Params
| Parameter | Type | Default | Description |
| --------- | ------------------ | -------------- | ------------------------------------------------------------------------------------- |
| `path` | `Union[str, Path]` | - | Path to text files. Can point to a single text file or a directory of text files. |
| `formats` | `List[str]` | `[".txt"]` | Formats accepted by this knowledge base. |
| `reader` | `TextReader` | `TextReader()` | A `TextReader` that converts the text files into `Documents` for the vector database. |
## AgentKnowledge Params
`TextKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# Website KnowledgeBase
Source: https://docs.phidata.com/reference/kb/website
## Example
Install `beautifulsoup4` using [this guide](/how-to/install)
```python knowledge_base.py
from phi.knowledge.website import WebsiteKnowledgeBase
from phi.vectordb.pgvector import PgVector
from resources import vector_db
knowledge_base = WebsiteKnowledgeBase(
urls=["https://docs.phidata.com/introduction"],
# Number of links to follow from the seed URLs
max_links=10,
# Table name: ai.website_documents
vector_db=PgVector(
table_name="website_documents",
db_url=vector_db.get_db_connection_local(),
),
)
```
## WebsiteKnowledgeBase Params
| Parameter | Type | Default | Description |
| ----------- | ------------------------- | ------- | ------------------------------------------------------------------------------------------------- |
| `urls` | `List[str]` | `[]` | URLs to read |
| `reader` | `Optional[WebsiteReader]` | `None` | A `WebsiteReader` that reads the urls and converts them into `Documents` for the vector database. |
| `max_depth` | `int` | `3` | Maximum depth to crawl. |
| `max_links` | `int` | `10` | Number of links to crawl. |
## AgentKnowledge Params
`WebsiteKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# Wikipedia KnowledgeBase
Source: https://docs.phidata.com/reference/kb/wikipedia
## Example
Install `wikipedia` if needed using [this guide](/how-to/install)
```python knowledge_base.py
from phi.knowledge.wikipedia import WikipediaKnowledgeBase
from phi.vectordb.pgvector import PgVector
from resources import vector_db
knowledge_base = WikipediaKnowledgeBase(
topics=["Manchester United", "Real Madrid"],
# Table name: ai.wikipedia_documents
vector_db=PgVector(
table_name="wikipedia_documents",
db_url=vector_db.get_db_connection_local(),
),
)
```
## WikipediaKnowledgeBase Params
| Parameter | Type | Default | Description |
| --------- | ----------- | ------- | -------------- |
| `topics` | `List[str]` | \[] | Topics to read |
## AgentKnowledge Params
`WikipediaKnowledgeBase` is a subclass of the `AgentKnowledge` class and has access to the same params
# Aws Bedrock
Source: https://docs.phidata.com/reference/model/aws
```python agent.py
from phi.agent import Agent
from phi.model.aws.claude import Claude
agent = Agent(
model=Claude(id="anthropic.claude-3-5-sonnet-20240620-v1:0"),
show_tool_calls=True,
markdown=True,
debug_mode=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## AWS Bedrock Params
`AwsBedrock` is a subclass of the [Model](/reference/model/base) class and has access to the same params.
# Azure
Source: https://docs.phidata.com/reference/model/azure
## Example
```python agent.py
from phi.agent import Agent
from phi.model.azure import AzureOpenAIChat
agent = Agent(
model=AzureOpenAIChat(),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## Azure Params
`Azure` is a subclass of the [OpenAILike](/reference/model/openai-like) class and has access to the same params.
# Model Base
Source: https://docs.phidata.com/reference/model/base
## Base Params
# Anthropic Claude
Source: https://docs.phidata.com/reference/model/claude
## Example
```python agent.py
from phi.agent import Agent
from phi.model.anthropic import Claude
agent = Agent(
model=Claude(id="claude-3-5-sonnet-20240620"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## Claude Params
`Claude` is a subclass of the [Model](/reference/model/base) class and has access to the same params.
# Cohere
Source: https://docs.phidata.com/reference/model/cohere
## Example
```python agent.py
from phi.agent import Agent
from phi.model.cohere import CohereChat
agent = Agent(
model=CohereChat(id="command-r-08-2024"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("Give me in-depth analysis of NVDA and TSLA")
```
## Cohere Params
`Cohere` is a subclass of the [Model](/reference/model/base) class and has access to the same params.
# DeepSeek
Source: https://docs.phidata.com/reference/model/deepseek
## Example
```python agent.py
from phi.agent import Agent
from phi.model.deepseek import DeepSeekChat
agent = Agent(
model=DeepSeekChat(),
show_tool_calls=True,
markdown=True,
)
agent.print_response("Give me in-depth analysis of NVDA and TSLA")
```
## DeepSeek Params
## Model Params
`DeepSeek` is a subclass of the [OpenAILike](/reference/model/openai-like) class and has access to the same params.
# Fireworks
Source: https://docs.phidata.com/reference/model/fireworks
## Example
```python agent.py
from phi.agent import Agent
from phi.model.fireworks import Fireworks
agent = Agent(
model=Fireworks(id="accounts/fireworks/models/firefunction-v2"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## Fireworks Params
`Fireworks` is a subclass of the [OpenAILike](/reference/model/openai-like) class and has access to the same params.
# Gemini - Google AI Studio
Source: https://docs.phidata.com/reference/model/gemini
## Example
```python agent.py
from phi.agent import Agent
from phi.model.google import Gemini
agent = Agent(
model=Gemini(id="gemini-1.5-flash"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## Gemini Params
`Gemini` is a subclass of the [Model](/reference/model/base) class and has access to the same params.
# Groq
Source: https://docs.phidata.com/reference/model/groq
## Example
```python agent.py
from phi.agent import Agent
from phi.model.groq import Groq
agent = Agent(
model=Groq(id="llama3-groq-70b-8192-tool-use-preview"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## Groq Params
`Groq` is a subclass of the [Model](/reference/model/base) class and has access to the same params.
# HuggingFace
Source: https://docs.phidata.com/reference/model/huggingface
## Example
```python agent.py
from phi.agent import Agent
from phi.model.huggingface import HuggingFaceChat
agent = Agent(
model=HuggingFaceChat(
id="meta-llama/Meta-Llama-3-8B-Instruct",
max_tokens=4096,
),
markdown=True
)
agent.print_response("Share a 2 sentence horror story")
```
## HuggingFace Params
`HuggingFaceChat` is a subclass of the [Model](/reference/model/base) class and has access to the same params.
# Mistral
Source: https://docs.phidata.com/reference/model/mistral
## Example
```python agent.py
from phi.agent import Agent
from phi.model.mistral import MistralChat
agent = Agent(
model=MistralChat(id="mistral-large-latest"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## Mistral Params
`MistralChat` is a subclass of the [Model](/reference/model/base) class and has access to the same params.
# Nvidia
Source: https://docs.phidata.com/reference/model/nvidia
## Example
```python agent.py
from phi.agent import Agent
from phi.model.nvidia import Nvidia
agent = Agent(model=Nvidia(id="nvidia/llama-3.1-nemotron-70b-instruct"), markdown=True)
agent.print_response("Share a 2 sentence horror story")
```
## Nvidia Params
`Nvidia` is a subclass of the [OpenAILike](/reference/model/openai-like) class and has access to the same params.
# Ollama
Source: https://docs.phidata.com/reference/model/ollama
## Example
```python agent.py
from phi.agent import Agent
from phi.model.ollama import Ollama
agent = Agent(
model=Ollama(id="llama3.2"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## Ollama Params
`Ollama` is a subclass of the [Model](/reference/model/base) class and has access to the same params.
# OpenAI
Source: https://docs.phidata.com/reference/model/openai
## Example
```python agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## OpenAI Params
For more information, please refer to the [OpenAI docs](https://platform.openai.com/docs/api-reference/chat/create) as well.
`OpenAIChat` is a subclass of the [Model](/reference/model/base) class and has access to the same params.
# OpenAILike
Source: https://docs.phidata.com/reference/model/openai-like
## Example
```python agent.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## OpenAI Params
For more information, please refer to the [OpenAI docs](https://platform.openai.com/docs/api-reference/chat/create) as well.
`OpenAILike` is a subclass of the [OpenAI](/reference/model/openai) class and has access to the same params.
# OpenRouter
Source: https://docs.phidata.com/reference/model/openrouter
## Example
```python agent.py
from phi.agent import Agent
from phi.model.openrouter import OpenRouter
agent = Agent(
model=OpenRouter(id="gpt-4o"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## OpenRouter Params
`OpenRouter` is a subclass of the [OpenAILike](/reference/model/openai-like) class and has access to the same params.
# Sambanova
Source: https://docs.phidata.com/reference/model/sambanova
## Example
```python agent.py
from phi.agent import Agent
from phi.model.sambanova import Sambanova
agent = Agent(model=Sambanova(), markdown=True)
# Print the response in the terminal
agent.print_response("Share a 2 sentence horror story")
```
## Sambanova Params
`Sambanova` is a subclass of the [OpenAILike](/reference/model/openai-like) class and has access to the same params.
# Together
Source: https://docs.phidata.com/reference/model/together
## Example
```python agent.py
from phi.agent import Agent
from phi.model.together import Together
agent = Agent(
model=Together(id="meta-llama/Meta-Llama-3.1-8B-Instruct-Turbo"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## Together Params
`Together` is a subclass of the [OpenAILike](/reference/model/openai-like) class and has access to the same params.
# Gemini - VertexAI
Source: https://docs.phidata.com/reference/model/vertexai
## Example
```python agent.py
from phi.agent import Agent
from phi.model.vertexai import Gemini
agent = Agent(
model=Gemini(id="gemini-1.5-flash"),
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## Gemini Params
`VertexAI` is a subclass of the [Model](/reference/model/base) class and has access to the same params.
# xAI
Source: https://docs.phidata.com/reference/model/xai
## Example
```python agent.py
from phi.agent import Agent
from phi.model.xai import xAI
agent = Agent(
model=xAI(id="grok-beta"),
instructions=["Use tables to display data."],
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is the stock price of NVDA and TSLA")
```
## xAI Params
`xAI` is a subclass of the [OpenAILike](/reference/model/openai-like) class and has access to the same params.
# DynamoDB Agent Storage
Source: https://docs.phidata.com/reference/storage/dynamodb
## Example
```python storage.py
from phi.storage.agent.dynamodb import DynamoDbAgentStorage
# Create a storage backend using the DynamoDB database
storage = DynamoDbAgentStorage(
# store sessions in the ai.sessions table
table_name="agent_sessions",
# region_name: AWS region name
region_name="us-east-1",
)
# Add storage to the Agent
agent = Agent(storage=storage)
```
## Params
# PostgreSQL Agent Storage
Source: https://docs.phidata.com/reference/storage/postgres
## Example
```python storage.py
from phi.storage.agent.postgres import PgAgentStorage
# Create a storage backend using the Postgres database
storage = PgAgentStorage(
# store sessions in the ai.sessions table
table_name="agent_sessions",
# db_url: Postgres database URL
db_url=db_url,
)
# Add storage to the Agent
agent = Agent(storage=storage)
```
## Params
# Single Store Agent Storage
Source: https://docs.phidata.com/reference/storage/singlestore
## Example
```python storage.py
from phi.storage.agent.singlestore import S2AgentStorage
# Create a storage backend using the SingleStore database
storage = S2AgentStorage(
# store sessions in the ai.sessions table
table_name="agent_sessions",
# db_engine: SingleStore database engine
db_engine=db_engine,
# schema: SingleStore schema
schema="ai",
)
# Add storage to the Agent
agent = Agent(storage=storage)
```
## Params
# Sqlite Agent Storage
Source: https://docs.phidata.com/reference/storage/sqlite
## Example
```python storage.py
from phi.storage.agent.sqlite import SqlAgentStorage
# Create a storage backend using the Sqlite database
storage = SqlAgentStorage(
# store sessions in the ai.sessions table
table_name="agent_sessions",
# db_file: Sqlite database file
db_file=db_file,
)
# Add storage to the Agent
agent = Agent(storage=storage)
```
## Params
# ChromaDb
Source: https://docs.phidata.com/reference/vectordb/chromadb
```python agent.py
import typer
from rich.prompt import Prompt
from typing import Optional
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.chroma import ChromaDb
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=ChromaDb(collection="recipes"),
)
# Comment out after first run
knowledge_base.load(recreate=False)
def pdf_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge_base=knowledge_base,
use_tools=True,
show_tool_calls=True,
debug_mode=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if __name__ == "__main__":
typer.run(pdf_agent)
```
## ChromaDb Params
# LanceDb
Source: https://docs.phidata.com/reference/vectordb/lancedb
```python agent.py
import typer
from rich.prompt import Prompt
from typing import Optional
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.lancedb import LanceDb
# type: ignore
db_url = "/tmp/lancedb"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=LanceDb(table_name="recipes", uri=db_url),
)
# Comment out after first run
knowledge_base.load(recreate=False)
def pdf_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge_base=knowledge_base,
use_tools=True,
show_tool_calls=True,
# Uncomment the following line to use traditional RAG
# add_references_to_prompt=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if __name__ == "__main__":
typer.run(pdf_agent)
```
## LanceDb Params
# PgVector
Source: https://docs.phidata.com/reference/vectordb/pgvector
```python agent.py
from phi.agent import Agent
from phi.storage.agent.postgres import PgAgentStorage
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector2
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
agent = Agent(
storage=PgAgentStorage(table_name="recipe_agent", db_url=db_url),
knowledge_base=PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector2(collection="recipe_documents", db_url=db_url),
), # Show tool calls in the response
show_tool_calls=True, # Enable the agent to search the knowledge base
search_knowledge=True, # Enable the agent to read the chat history
read_chat_history=True,
)
# Comment out after first run
agent.knowledge_base.load(recreate=False) # type: ignore
agent.print_response("How do I make pad thai?", markdown=True)
```
## PgVectorDb Params
# PgVector
Source: https://docs.phidata.com/reference/vectordb/pgvector2
## PgVectorDb Params
# PineconeDB
Source: https://docs.phidata.com/reference/vectordb/pineconedb
```python agent.py
import os
import typer
from typing import Optional
from rich.prompt import Prompt
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pineconedb import PineconeDB
api_key = os.getenv("PINECONE_API_KEY")
index_name = "thai-recipe-index"
vector_db = PineconeDB(
name=index_name,
dimension=1536,
metric="cosine",
spec={"serverless": {"cloud": "aws", "region": "us-east-1"}},
api_key=api_key,
)
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=vector_db,
)
# Comment out after first run
knowledge_base.load(recreate=False, upsert=True)
def pinecone_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge_base=knowledge_base,
use_tools=True,
show_tool_calls=True,
debug_mode=True,
# Uncomment the following line to use traditional RAG
# add_references_to_prompt=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if **name** == "**main**":
typer.run(pinecone_agent)
```
## PineconeDB Params
# Qdrant
Source: https://docs.phidata.com/reference/vectordb/qdrant
```python agent.py
import os
import typer
from typing import Optional
from rich.prompt import Prompt
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.qdrant import Qdrant
api_key = os.getenv("QDRANT_API_KEY")
qdrant_url = os.getenv("QDRANT_URL")
collection_name = "thai-recipe-index"
vector_db = Qdrant(
collection=collection_name,
url=qdrant_url,
api_key=api_key,
)
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=vector_db,
)
# Comment out after first run
knowledge_base.load(recreate=True, upsert=True)
def qdrant_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge_base=knowledge_base,
tool_calls=True,
use_tools=True,
show_tool_calls=True,
debug_mode=True,
# Uncomment the following line to use traditional RAG
# add_references_to_prompt=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if **name** == "**main**":
typer.run(qdrant_agent)
```
## Qdrant Params
# Single Store
Source: https://docs.phidata.com/reference/vectordb/singlestore
```python agent.py
import typer
from typing import Optional
from os import getenv
from sqlalchemy.engine import create_engine
from phi.assistant import Assistant
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.singlestore import S2VectorDb
USERNAME = getenv("SINGLESTORE_USERNAME")
PASSWORD = getenv("SINGLESTORE_PASSWORD")
HOST = getenv("SINGLESTORE_HOST")
PORT = getenv("SINGLESTORE_PORT")
DATABASE = getenv("SINGLESTORE_DATABASE")
SSL_CERT = getenv("SINGLESTORE_SSL_CERT", None)
db_url = f"mysql+pymysql://{USERNAME}:{PASSWORD}@{HOST}:{PORT}/{DATABASE}?charset=utf8mb4"
if SSL_CERT:
db_url += f"&ssl_ca={SSL_CERT}&ssl_verify_cert=true"
db_engine = create_engine(db_url)
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=S2VectorDb(
collection="recipes",
db_engine=db_engine,
schema=DATABASE,
),
)
# Comment out after first run
knowledge_base.load(recreate=False)
def pdf_assistant(user: str = "user"):
run_id: Optional[str] = None
assistant = Assistant(
run_id=run_id,
user_id=user,
knowledge_base=knowledge_base,
use_tools=True,
show_tool_calls=True,
# Uncomment the following line to use traditional RAG
# add_references_to_prompt=True,
)
if run_id is None:
run_id = assistant.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
assistant.cli_app(markdown=True)
if **name** == "**main**":
typer.run(pdf_assistant)
```
## Single Store Params
# DynamoDB Agent Storage
Source: https://docs.phidata.com/storage/dynamodb
Phidata supports using DynamoDB as a storage backend for Agents using the `DynamoDbAgentStorage` class.
## Usage
You need to provide `aws_access_key_id` and `aws_secret_access_key` parameters to the `DynamoDbAgentStorage` class.
```python storage.py
from phi.storage.agent.dynamodb import DynamoDbAgentStorage
# AWS Credentials
AWS_ACCESS_KEY_ID = getenv("AWS_ACCESS_KEY_ID")
AWS_SECRET_ACCESS_KEY = getenv("AWS_SECRET_ACCESS_KEY")
storage = DynamoDbAgentStorage(
# store sessions in the ai.sessions table
table_name="agent_sessions",
# region_name: DynamoDB region name
region_name="us-east-1",
# aws_access_key_id: AWS access key id
aws_access_key_id=AWS_ACCESS_KEY_ID,
# aws_secret_access_key: AWS secret access key
aws_secret_access_key=AWS_SECRET_ACCESS_KEY,
)
# Add storage to the Agent
agent = Agent(storage=storage)
```
## Params
# Introduction
Source: https://docs.phidata.com/storage/introduction
Agents come with built-in memory but it only lasts while the session is active. To continue conversations across sessions, we store Agent sessions in a database like PostgreSQL.
Storage is a necessary component when building user facing AI products as any production application will require users to be able to "continue" their conversation with the Agent.
The general syntax for adding storage to an Agent looks like:
```python storage.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.duckduckgo import DuckDuckGo
from phi.storage.agent.postgres import PgAgentStorage
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
storage=PgAgentStorage(table_name="agent_sessions", db_url="postgresql+psycopg://ai:ai@localhost:5532/ai"),
tools=[DuckDuckGo()],
show_tool_calls=True,
add_history_to_messages=True,
)
agent.print_response("How many people live in Canada?")
agent.print_response("What is their national anthem called?")
agent.print_response("Which country are we speaking about?")
```
The following databases are supported as a storage backend:
* [PostgreSQL](/storage/postgres)
* [Sqlite](/storage/sqlite)
* [SingleStore](/storage/singlestore)
* [DynamoDB](/storage/dynamodb)
* [MongoDB](/storage/mongodb)
# JSON Agent Storage
Source: https://docs.phidata.com/storage/json
Phidata supports using local JSON files as a storage backend for Agents using the `JsonFileAgentStorage` class.
## Usage
```python storage.py
from phi.agent import Agent
from phi.tools.duckduckgo import DuckDuckGo
from phi.storage.agent.json import JsonFileAgentStorage
agent = Agent(
storage=JsonFileAgentStorage(path="tmp/agent_sessions_json"),
tools=[DuckDuckGo()],
add_history_to_messages=True,
)
agent.print_response("How many people live in Canada?")
agent.print_response("What is their national anthem called?")
```
## Params
# Postgres Agent Storage
Source: https://docs.phidata.com/storage/postgres
Phidata supports using PostgreSQL as a storage backend for Agents using the `PgAgentStorage` class.
## Usage
## Run PgVector
Install [docker desktop](https://docs.docker.com/desktop/install/mac-install/) and run **PgVector** on port **5532** using:
```bash
docker run -d \
-e POSTGRES_DB=ai \
-e POSTGRES_USER=ai \
-e POSTGRES_PASSWORD=ai \
-e PGDATA=/var/lib/postgresql/data/pgdata \
-v pgvolume:/var/lib/postgresql/data \
-p 5532:5432 \
--name pgvector \
phidata/pgvector:16
```
```python storage.py
from phi.storage.agent.postgres import PgAgentStorage
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
# Create a storage backend using the Postgres database
storage = PgAgentStorage(
# store sessions in the ai.sessions table
table_name="agent_sessions",
# db_url: Postgres database URL
db_url=db_url,
)
# Add storage to the Agent
agent = Agent(storage=storage)
```
## Params
# Singlestore Agent Storage
Source: https://docs.phidata.com/storage/singlestore
Phidata supports using Singlestore as a storage backend for Agents using the `S2AgentStorage` class.
## Usage
Obtain the credentials for Singlestore from [here](https://portal.singlestore.com/)
```python storage.py
from phi.storage.agent.singlestore import S2AgentStorage
# SingleStore Configuration
USERNAME = getenv("SINGLESTORE_USERNAME")
PASSWORD = getenv("SINGLESTORE_PASSWORD")
HOST = getenv("SINGLESTORE_HOST")
PORT = getenv("SINGLESTORE_PORT")
DATABASE = getenv("SINGLESTORE_DATABASE")
SSL_CERT = getenv("SINGLESTORE_SSL_CERT", None)
# SingleStore DB URL
db_url = f"mysql+pymysql://{USERNAME}:{PASSWORD}@{HOST}:{PORT}/{DATABASE}?charset=utf8mb4"
if SSL_CERT:
db_url += f"&ssl_ca={SSL_CERT}&ssl_verify_cert=true"
# Create a database engine
db_engine = create_engine(db_url)
# Create a storage backend using the Singlestore database
storage = S2AgentStorage(
# store sessions in the ai.sessions table
table_name="agent_sessions",
# db_engine: Singlestore database engine
db_engine=db_engine,
# schema: Singlestore schema
schema=DATABASE,
)
# Add storage to the Agent
agent = Agent(storage=storage)
```
## Params
# Sqlite Agent Storage
Source: https://docs.phidata.com/storage/sqlite
Phidata supports using Sqlite as a storage backend for Agents using the `SqlAgentStorage` class.
## Usage
You need to provide either `db_url`, `db_file` or `db_engine`. The following example uses `db_file`.
```python storage.py
from phi.storage.agent.sqlite import SqlAgentStorage
# Create a storage backend using the Sqlite database
storage = SqlAgentStorage(
# store sessions in the ai.sessions table
table_name="agent_sessions",
# db_file: Sqlite database file
db_file="tmp/data.db",
)
# Add storage to the Agent
agent = Agent(storage=storage)
```
## Params
# YAML Agent Storage
Source: https://docs.phidata.com/storage/yaml
Phidata supports using local YAML files as a storage backend for Agents using the `YamlFileAgentStorage` class.
## Usage
```python storage.py
from phi.agent import Agent
from phi.tools.duckduckgo import DuckDuckGo
from phi.storage.agent.yaml import YamlFileAgentStorage
agent = Agent(
storage=YamlFileAgentStorage(path="tmp/agent_sessions_yaml"),
tools=[DuckDuckGo()],
add_history_to_messages=True,
)
agent.print_response("How many people live in Canada?")
agent.print_response("What is their national anthem called?")
```
## Params
# Run on AWS
Source: https://docs.phidata.com/templates/agent-api/run-aws
Let's run the **Agent API** in production on AWS.
## Next
Congratulations on running your Agent API on AWS. Next Steps:
* Read how to [update workspace settings](/templates/how-to/workspace-settings)
* Read how to [create a git repository for your workspace](/templates/how-to/git-repo)
* Read how to [manage the production application](/templates/how-to/production-app)
* Read how to [format and validate your code](/templates/how-to/format-and-validate)
* Read how to [add python libraries](/templates/how-to/install)
* Read how to [add a custom domain and HTTPS](/templates/how-to/domain-https)
* Read how to [implement CI/CD](/templates/how-to/ci-cd)
* Chat with us on [discord](https://discord.gg/4MtYHHrgA8)
# Building an Agent API
Source: https://docs.phidata.com/templates/agent-api/run-local
The Agent Api let's us serve agents using a [FastApi](https://fastapi.tiangolo.com/) server and store memory and knowledge in a Postgres database. Run it locally using docker or deploy to production on AWS.
## Next
Congratulations on running your AI API locally. Next Steps:
* [Run your Agent API on AWS](/templates/agent-api/run-aws)
* Read how to [update workspace settings](/templates/how-to/workspace-settings)
* Read how to [create a git repository for your workspace](/templates/how-to/git-repo)
* Read how to [manage the development application](/templates/how-to/development-app)
* Read how to [format and validate your code](/templates/how-to/format-and-validate)
* Read how to [add python libraries](/templates/how-to/install)
* Chat with us on [discord](https://discord.gg/4MtYHHrgA8)
# Run on AWS
Source: https://docs.phidata.com/templates/agent-app/run-aws
Let's run the **Agent App** in production on AWS.
## Next
Congratulations on running your Agent App on AWS. Next Steps:
* Read how to [update workspace settings](/templates/how-to/workspace-settings)
* Read how to [create a git repository for your workspace](/templates/how-to/git-repo)
* Read how to [manage the production application](/templates/how-to/production-app)
* Read how to [format and validate your code](/templates/how-to/format-and-validate)
* Read how to [add python libraries](/templates/how-to/install)
* Read how to [add a custom domain and HTTPS](/templates/how-to/domain-https)
* Read how to [implement CI/CD](/templates/how-to/ci-cd)
* Chat with us on [discord](https://discord.gg/4MtYHHrgA8)
# Building an Agent App
Source: https://docs.phidata.com/templates/agent-app/run-local
The Agent App let's us serve agents using a [FastApi](https://fastapi.tiangolo.com/) server, test them using a [Streamlit](https://streamlit.io/) UI and store memory and knowledge in a Postgres database. Run it locally using docker or deploy to production on AWS.
## Next
Congratulations on running your AI App locally. Next Steps:
* [Run your Agent App on AWS](/templates/agent-app/run-aws)
* Read how to [update workspace settings](/templates/how-to/workspace-settings)
* Read how to [create a git repository for your workspace](/templates/how-to/git-repo)
* Read how to [manage the development application](/templates/how-to/development-app)
* Read how to [format and validate your code](/templates/how-to/format-and-validate)
* Read how to [add python libraries](/templates/how-to/install)
* Chat with us on [discord](https://discord.gg/4MtYHHrgA8)
# Examples
Source: https://docs.phidata.com/templates/apps/examples
## Run Jupyter on Docker
A jupyter notebook is a must have for AI development. Update the `resources.py` file to:
```python resources.py
from os import getenv
from phi.docker.app.jupyter import Jupyter
from phi.docker.app.postgres import PgVectorDb
from phi.docker.resources import DockerResources
# -*- PgVector running on port 5432:5432
vector_db = PgVectorDb(
pg_user="ai",
pg_password="ai",
pg_database="ai",
debug_mode=True,
)
# -*- Jupyter running on port 8888:8888
jupyter = Jupyter(
mount_workspace=True,
env_vars={"OPENAI_API_KEY": getenv("OPENAI_API_KEY")},
)
# -*- DockerResources
dev_docker_resources = DockerResources(
apps=[vector_db, jupyter],
)
```
Start resources using:
```bash Mac
phi start resources.py
```
```bash Windows
phi start resources.py
```
### View Jupyterlab UI
* Open [localhost:8888](http://localhost:8888) to view the Jupyterlab UI. Password: **admin**
* The directory is automatically mounted in the notebook.
## Stop resources
```bash Mac
phi stop resources.py
```
```bash Windows
phi stop resources.py
```
# Features
Source: https://docs.phidata.com/templates/apps/features
## Install requirements on startup
Apps can install requirements on container startup. Update the `Jupyter` app to:
```python resources.py
...
# -*- Jupyter running on port 8888:8888
jupyter = Jupyter(
mount_workspace=True,
install_requirements=True,
requirements_file="requirements.txt",
env_vars={"OPENAI_API_KEY": getenv("OPENAI_API_KEY")},
)
...
```
Create a `requirements.txt` file in the same directory
```python requirements.txt
openai
```
## Patch resources
```bash terminal
phi patch resources.py -y
```
```bash full options
phi patch resources.py --yes
```
# Introduction
Source: https://docs.phidata.com/templates/apps/introduction
Apps are tools like `FastApi`, `PgVector`, `Streamlit`, `Jupyter`, `Django` that we define as python classes and run using `phi start` or `phi ws up`.
When running Apps using phidata, think of them as infrastructure as code but at a higher level of abstraction. Instead of defining containers, volumes etc. we define the application we want to run. We run **Applications as Code** instead of Infrastructure as Code.
The same `App` can run on docker, AWS (ECS) or Kubernetes (EKS). The App creates the underlying resources like LoadBalancers, Services, Deployments. As the underlying resources become more complex, the concept of Apps become more appealing.
## Example
Lets run a Jupyter notebook and PgVector on docker.
Copy the following contents to a file `resources.py` and run `phi start resources.py`
```python resources.py
from phi.docker.app.jupyter import Jupyter
from phi.docker.app.postgres import PgVectorDb
from phi.docker.resources import DockerResources
# -*- PgVector running on port 5432:5432
vector_db = PgVectorDb(pg_user="ai", pg_password="ai", pg_database="ai")
# -*- Jupyter running on port 8888:8888
jupyter = Jupyter(mount_workspace=True)
# -*- DockerResources
dev_docker_resources = DockerResources(apps=[vector_db, jupyter])
```
* Each App is a pydantic object providing input and type validation.
* Note how the `mount_workspace` automatically mounts the directory
* Note how `PgVectorDb` sets the required settings and creates the volume.
While this is a simple example, these concepts become very powerful for complex applications.
## Motivation
Apps provide the **"Application Layer"** for our AI products.
The software we write needs to be served by an Application, and this Application needs to **run the same** locally for development and in the cloud for production. By defining **Applications as Code**, we bring the benefits of **Infrastructure as Code** to the software layer.
Defining **Applications as Code** also allows us to package "software systems" into templates. Meaning every phidata template can run locally using docker or on AWS with 1 command.
Finally, defining **Applications as python objects** means we can import them in our code like regular objects making the following code possible:
```python
from resources import vector_db
db_url=vector_db.get_db_connection_local()
```
Checkout some example apps you can run on docker:
* [PgVector](/examples/integrations/pgvector)
* [Jupyter](/templates/apps/examples)
Defining **Applications as Code** offers many benefits, such as:
* [Install requirements on startup](/templates/apps/features#install-requirements-on-startup)
# CI/CD
Source: https://docs.phidata.com/templates/how-to/ci-cd
Phidata templates come pre-configured with [Github Actions](https://docs.github.com/en/actions) for CI/CD. We can
1. [Test and Validate on every PR](#test-and-validate-on-every-pr)
2. [Build Docker Images with Github Releases](#build-docker-images-with-github-releases)
3. [Build ECR Images with Github Releases](#build-ecr-images-with-github-releases)
## Test and Validate on every PR
Whenever a PR is opened against the `main` branch, a validate script runs that ensures
1. The changes are formatted using ruff
2. All unit-tests pass
3. The changes don't have any typing or linting errors.
Checkout the `.github/workflows/validate.yml` file for more information.
 ## Build Docker Images with Github Releases
If you're using [Dockerhub](https://hub.docker.com/) for images, you can buld and push the images throug a Github Release. This action is defined in the `.github/workflows/docker-images.yml` file.
1. Create a [Docker Access Token](https://hub.docker.com/settings/security) for Github Actions
 2. Create secret variables `DOCKERHUB_REPO`, `DOCKERHUB_TOKEN` and `DOCKERHUB_USERNAME` in your github repo. These variables are used by the action in `.github/workflows/docker-images.yml`
 3. Run workflow using a Github Release
This workflow is configured to run when a release is created. Create a new release using:
Confirm the image name in the `.github/workflows/docker-images.yml` file before running
```bash Mac
gh release create v0.1.0 --title "v0.1.0" -n ""
```
```bash Windows
gh release create v0.1.0 --title "v0.1.0" -n ""
```
 You can also run the workflow using `gh workflow run`
## Build ECR Images with Github Releases
If you're using ECR for images, you can buld and push the images through a Github Release. This action is defined in the `.github/workflows/ecr-images.yml` file and uses the new OpenID Connect (OIDC) approach to request the access token, without using IAM access keys.
We will follow this [guide](https://aws.amazon.com/blogs/security/use-iam-roles-to-connect-github-actions-to-actions-in-aws/) to create an IAM role which will be used by the github action.
1. Open the IAM console.
2. In the left navigation menu, choose Identity providers.
3. In the Identity providers pane, choose Add provider.
4. For Provider type, choose OpenID Connect.
5. For Provider URL, enter the URL of the GitHub OIDC IdP: [https://token.actions.githubusercontent.com](https://token.actions.githubusercontent.com)
6. Get thumbprint to verify the server certificate
7. For Audience, enter sts.amazonaws.com.
Verify the information matches the screenshot below and Add provider
 8. Assign a Role to the provider.
 9. Create a new role.
 10. Confirm that Web identity is already selected as the trusted entity and the Identity provider field is populated with the IdP. In the Audience list, select sts.amazonaws.com, and then select Next.
 11. Add the `AmazonEC2ContainerRegistryPowerUser` permission to this role.
12. Create the role with the name `GithubActionsRole`.
13. Find the role `GithubActionsRole` and copy the ARN.
 14. Create the ECR Repositories: `llm` and `jupyter-llm` which are built by the workflow.
 15. Update the workflow with the `GithubActionsRole` ARN and ECR Repository.
```yaml .github/workflows/ecr-images.yml
name: Build ECR Images
on:
release:
types: [published]
permissions:
# For AWS OIDC Token access as per https://docs.github.com/en/actions/deployment/security-hardening-your-deployments/configuring-openid-connect-in-amazon-web-services#updating-your-github-actions-workflow
id-token: write # This is required for requesting the JWT
contents: read # This is required for actions/checkout
env:
ECR_REPO: [YOUR_ECR_REPO]
# Create role using https://aws.amazon.com/blogs/security/use-iam-roles-to-connect-github-actions-to-actions-in-aws/
AWS_ROLE: [GITHUB_ACTIONS_ROLE_ARN]
AWS_REGION: us-east-1
```
16. Update the `docker-images` workflow to **NOT** run on a release
```yaml .github/workflows/docker-images.yml
name: Build Docker Images
on: workflow_dispatch
```
17. Run workflow using a Github Release
```bash Mac
gh release create v0.2.0 --title "v0.2.0" -n ""
```
```bash Windows
gh release create v0.2.0 --title "v0.2.0" -n ""
```
 You can also run the workflow using `gh workflow run`
# Database Tables
Source: https://docs.phidata.com/templates/how-to/database-tables
Phidata templates come pre-configured with [SqlAlchemy](https://www.sqlalchemy.org/) and [alembic](https://alembic.sqlalchemy.org/en/latest/) to manage databases. The general workflow to add a table is:
1. Add table definition to the `db/tables` directory.
2. Import the table class in the `db/tables/__init__.py` file.
3. Create a database migration.
4. Run database migration.
## Table Definition
Let's create a `UsersTable`, copy the following code to `db/tables/user.py`
```python db/tables/user.py
from datetime import datetime
from typing import Optional
from sqlalchemy.orm import Mapped, mapped_column
from sqlalchemy.sql.expression import text
from sqlalchemy.types import BigInteger, DateTime, String
from db.tables.base import Base
class UsersTable(Base):
"""Table for storing user data."""
__tablename__ = "dim_users"
id_user: Mapped[int] = mapped_column(
BigInteger, primary_key=True, autoincrement=True, nullable=False, index=True
)
email: Mapped[str] = mapped_column(String)
is_active: Mapped[bool] = mapped_column(default=True)
created_at: Mapped[datetime] = mapped_column(
DateTime(timezone=True), server_default=text("now()")
)
updated_at: Mapped[Optional[datetime]] = mapped_column(
DateTime(timezone=True), onupdate=text("now()")
)
```
Update the `db/tables/__init__.py` file:
```python db/tables/__init__.py
from db.tables.base import Base
from db.tables.user import UsersTable
```
## Creat a database revision
Run the alembic command to create a database migration in the dev container:
```bash
docker exec -it ai-api alembic -c db/alembic.ini revision --autogenerate -m "Initialize DB"
```
## Migrate dev database
Run the alembic command to migrate the dev database:
```bash
docker exec -it ai-api alembic -c db/alembic.ini upgrade head
```
### Optional: Add test user
Now lets's add a test user. Copy the following code to `db/tables/test_add_user.py`
```python db/tables/test_add_user.py
from typing import Optional
from sqlalchemy.orm import Session
from db.session import SessionLocal
from db.tables.user import UsersTable
from utils.log import logger
def create_user(db_session: Session, email: str) -> UsersTable:
"""Create a new user."""
new_user = UsersTable(email=email)
db_session.add(new_user)
return new_user
def get_user(db_session: Session, email: str) -> Optional[UsersTable]:
"""Get a user by email."""
return db_session.query(UsersTable).filter(UsersTable.email == email).first()
if __name__ == "__main__":
test_user_email = "test@test.com"
with SessionLocal() as sess, sess.begin():
logger.info(f"Creating user: {test_user_email}")
create_user(db_session=sess, email=test_user_email)
logger.info(f"Getting user: {test_user_email}")
user = get_user(db_session=sess, email=test_user_email)
if user:
logger.info(f"User created: {user.id_user}")
else:
logger.info(f"User not found: {test_user_email}")
```
Run the script to add a test adding a user:
```bash
docker exec -it ai-api python db/tables/test_add_user.py
```
## Migrate production database
We recommended migrating the production database by setting the environment variable `MIGRATE_DB = True` and restarting the production service. This runs `alembic -c db/alembic.ini upgrade head` from the entrypoint script at container startup.
### Update the `workspace/prd_resources.py` file
```python workspace/prd_resources.py
...
# -*- Build container environment
container_env = {
...
# Migrate database on startup using alembic
"MIGRATE_DB": ws_settings.prd_db_enabled,
}
...
```
### Update the ECS Task Definition
Because we updated the Environment Variables, we need to update the Task Definition:
```bash terminal
phi ws patch --env prd --infra aws --name td
```
```bash shorthand
phi ws patch -e prd -i aws -n td
```
### Update the ECS Service
After updating the task definition, redeploy the production application:
```bash terminal
phi ws patch --env prd --infra aws --name service
```
```bash shorthand
phi ws patch -e prd -i aws -n service
```
## Manually migrate prodution database
Another approach is to SSH into the production container to run the migration manually. Your ECS tasks are already enabled with SSH access. Run the alembic command to migrate the production database:
```bash
ECS_CLUSTER=ai-app-prd-cluster
TASK_ARN=$(aws ecs list-tasks --cluster ai-app-prd-cluster --query "taskArns[0]" --output text)
CONTAINER_NAME=ai-api-prd
aws ecs execute-command --cluster $ECS_CLUSTER \
--task $TASK_ARN \
--container $CONTAINER_NAME \
--interactive \
--command "alembic -c db/alembic.ini upgrade head"
```
***
## How the migrations directory was created
These commands have been run and are described for completeness
The migrations directory was created using:
```bash
docker exec -it ai-api cd db && alembic init migrations
```
* After running the above command, the `db/migrations` directory should be created.
* Update `alembic.ini`
* set `script_location = db/migrations`
* uncomment `black` hook in `[post_write_hooks]`
* Update `db/migrations/env.py` file following [this link](https://alembic.sqlalchemy.org/en/latest/autogenerate.html)
* Add the following function to `configure` to only include tables in the target\_metadata
```python db/migrations/env.py
# -*- Only include tables that are in the target_metadata
def include_name(name, type_, parent_names):
if type_ == "table":
return name in target_metadata.tables
else:
return True
...
```
# Development Application
Source: https://docs.phidata.com/templates/how-to/development-app
Your development application runs locally on docker and its resources are defined in the `workspace/dev_resources.py` file. This guide shows how to:
1. [Build a development image](#build-your-development-image)
2. [Restart all docker containers](#restart-all-containers)
3. [Recreate development resources](#recreate-development-resources)
## Workspace Settings
The `WorkspaceSettings` object in the `workspace/settings.py` file defines common settings used by your workspace apps and resources.
## Build your development image
Your application uses the `phidata` images by default. To use your own image:
* Open `workspace/settings.py` file
* Update the `image_repo` to your image repository
* Set `build_images=True`
```python workspace/settings.py
ws_settings = WorkspaceSettings(
...
# -*- Image Settings
# Repository for images
image_repo="local",
# Build images locally
build_images=True,
)
```
### Build a new image
Build the development image using:
```bash terminal
phi ws up --env dev --infra docker --type image
```
```bash short options
phi ws up -e dev -i docker -t image
```
To `force` rebuild images, use the `--force` or `-f` flag
```bash terminal
phi ws up --env dev --infra docker --type image --force
```
```bash short options
phi ws up -e dev -i docker -t image -f
```
***
## Restart all containers
Restart all docker containers using:
```bash terminal
phi ws restart --env dev --infra docker --type container
```
```bash short options
phi ws restart -e dev -c docker -t container
```
***
## Recreate development resources
To recreate all dev resources, use the `--force` flag:
```bash terminal
phi ws up -f
```
```bash full options
phi ws up --env dev --infra docker --force
```
```bash shorthand
phi ws up dev:docker -f
```
```bash short options
phi ws up -e dev -i docker -f
```
# Use Custom Domain and HTTPS
Source: https://docs.phidata.com/templates/how-to/domain-https
## Use a custom domain
1. Register your domain with [Route 53](https://us-east-1.console.aws.amazon.com/route53/).
2. Point the domain to the loadbalancer DNS.
### Custom domain for your Streamlit App
Create a record in the Route53 console to point `app.[YOUR_DOMAIN]` to the Streamlit App.
 You can visit the app at [http://app.aidev.run](http://app.aidev.run)
Note the `http` in the domain name.
### Custom domain for your FastApi App
Create a record in the Route53 console to point `api.[YOUR_DOMAIN]` to the FastApi App.
 You can access the api at [http://api.aidev.run](http://api.aidev.run)
Note the `http` in the domain name.
## Add HTTPS
To add HTTPS:
1. Create a certificate using [AWS ACM](https://us-east-1.console.aws.amazon.com/acm). Request a certificat for `*.[YOUR_DOMAIN]`
 2. Creating records in Route 53.
 3. Add the certificate ARN to Apps
Make sure the certificate is `Issued` before adding it to your Apps
Update the `llm-app/workspace/prd_resources.py` file and add the `load_balancer_certificate_arn` to the `FastApi` and `Streamlit` Apps.
```python workspace/prd_resources.py
# -*- Streamlit running on ECS
prd_streamlit = Streamlit(
...
# To enable HTTPS, create an ACM certificate and add the ARN below:
load_balancer_enable_https=True,
load_balancer_certificate_arn="arn:aws:acm:us-east-1:497891874516:certificate/6598c24a-d4fc-4f17-8ee0-0d3906eb705f",
...
)
# -*- FastApi running on ECS
prd_fastapi = FastApi(
...
# To enable HTTPS, create an ACM certificate and add the ARN below:
load_balancer_enable_https=True,
load_balancer_certificate_arn="arn:aws:acm:us-east-1:497891874516:certificate/6598c24a-d4fc-4f17-8ee0-0d3906eb705f",
...
)
```
4. Create new Loadbalancer Listeners
Create new listeners for the loadbalancer to pickup the HTTPs configuration.
```bash terminal
phi ws up --env prd --infra aws --name listener
```
```bash shorthand
phi ws up -e prd -i aws -n listener
```
The certificate should be `Issued` before applying it.
After this, `https` should be working on your custom domain.
5. Update existing listeners to redirect HTTP to HTTPS
```bash terminal
phi ws patch --env prd --infra aws --name listener
```
```bash shorthand
phi ws patch -e prd -i aws -n listener
```
After this, all HTTP requests should redirect to HTTPS automatically.
# Environment variables
Source: https://docs.phidata.com/templates/how-to/env-vars
Environment variables can be added to resources using the `env_vars` parameter or the `env_file` parameter pointing to a `yaml` file. Examples
```python dev_resources.py
dev_fastapi = FastApi(
...
env_vars={
"RUNTIME_ENV": "dev",
# Get the OpenAI API key from the local environment
"OPENAI_API_KEY": getenv("OPENAI_API_KEY"),
# Database configuration
"DB_HOST": dev_db.get_db_host(),
"DB_PORT": dev_db.get_db_port(),
"DB_USER": dev_db.get_db_user(),
"DB_PASS": dev_db.get_db_password(),
"DB_DATABASE": dev_db.get_db_database(),
# Wait for database to be available before starting the application
"WAIT_FOR_DB": ws_settings.dev_db_enabled,
# Migrate database on startup using alembic
# "MIGRATE_DB": ws_settings.prd_db_enabled,
},
...
)
```
```python prd_resources.py
prd_fastapi = FastApi(
...
env_vars={
"RUNTIME_ENV": "prd",
# Get the OpenAI API key from the local environment
"OPENAI_API_KEY": getenv("OPENAI_API_KEY"),
# Database configuration
"DB_HOST": AwsReference(prd_db.get_db_endpoint),
"DB_PORT": AwsReference(prd_db.get_db_port),
"DB_USER": AwsReference(prd_db.get_master_username),
"DB_PASS": AwsReference(prd_db.get_master_user_password),
"DB_DATABASE": AwsReference(prd_db.get_db_name),
# Wait for database to be available before starting the application
"WAIT_FOR_DB": ws_settings.prd_db_enabled,
# Migrate database on startup using alembic
# "MIGRATE_DB": ws_settings.prd_db_enabled,
},
...
)
```
The apps in your templates are already configured to read environment variables.
# Format & Validate
Source: https://docs.phidata.com/templates/how-to/format-and-validate
## Format
Formatting the codebase using a set standard saves us time and mental energy. Phidata templates are pre-configured with [ruff](https://docs.astral.sh/ruff/) that you can run using a helper script or directly.
```bash terminal
./scripts/format.sh
```
```bash ruff
ruff format .
```
## Validate
Linting and Type Checking add an extra layer of protection to the codebase. We highly recommending running the validate script before pushing any changes.
Phidata templates are pre-configured with [ruff](https://docs.astral.sh/ruff/) and [mypy](https://mypy.readthedocs.io/en/stable/) that you can run using a helper script or directly. Checkout the `pyproject.toml` file for the configuration.
```bash terminal
./scripts/validate.sh
```
```bash ruff
ruff check .
```
```bash mypy
mypy .
```
# Create Git Repo
Source: https://docs.phidata.com/templates/how-to/git-repo
Create a git repository to share your application with your team.
Create a new [git repository](https://github.com/new).
Push your code to the git repository.
```bash terminal
git init
git add .
git commit -m "Init LLM App"
git branch -M main
git remote add origin https://github.com/[YOUR_GIT_REPO].git
git push -u origin main
```
Ask your team to follow the [setup steps for new users](templates/how-to/new-users) to use this workspace.
# Install & Setup
Source: https://docs.phidata.com/templates/how-to/install
## Install phidata
We highly recommend:
* Installing `phidata` using `pip` in a python virtual environment.
* Creating an `ai` directory for your ai workspaces
Open the `Terminal` and create an `ai` directory with a python virtual environment.
```bash Mac
mkdir ai && cd ai
python3 -m venv aienv
source aienv/bin/activate
```
```bash Windows
mkdir ai; cd ai
python3 -m venv aienv
aienv/scripts/activate
```
Install `phidata` using pip
```bash Mac
pip install -U phidata
```
```bash Windows
pip install -U phidata
```
Install [docker desktop](https://docs.docker.com/desktop/install/mac-install/) to run apps locally
If you encounter errors, try updating pip using `python -m pip install --upgrade pip`
***
## Upgrade phidata
To upgrade `phidata`, run this in your virtual environment
```bash
pip install -U phidata --no-cache-dir
```
***
## Setup workspace
If you have an existing `phidata` workspace, set it up using
```bash
phi ws setup
```
***
## Reset phidata
To reset the phidata config, run
```bash
phi init -r
```
This does not delete any physical data
# Setup workspace for new users
Source: https://docs.phidata.com/templates/how-to/new-users
Follow these steps to setup an existing workspace:
Clone the git repo and `cd` into the workspace directory
```bash Mac
git clone https://github.com/[YOUR_GIT_REPO].git
cd your_workspace_directory
```
```bash Windows
git clone https://github.com/[YOUR_GIT_REPO].git
cd your_workspace_directory
```
```bash Mac
python3 -m venv aienv
source aienv/bin/activate
```
```bash Windows
python3 -m venv aienv
aienv/scripts/activate
```
```bash Mac
pip install -U phidata
```
```bash Windows
pip install -U phidata
```
```bash Mac
phi ws setup
```
```bash Windows
phi ws setup
```
Copy `workspace/example_secrets` to `workspace/secrets`
```bash Mac
cp -r workspace/example_secrets workspace/secrets
```
```bash Windows
cp -r workspace/example_secrets workspace/secrets
```
Install [docker desktop](https://docs.docker.com/desktop/install/mac-install/) if needed.
```bash terminal
phi ws up
```
```bash full options
phi ws up --env dev --infra docker
```
```bash shorthand
phi ws up dev:docker
```
```bash terminal
phi ws down
```
```bash full options
phi ws down --env dev --infra docker
```
```bash shorthand
phi ws down dev:docker
```
# Production Application
Source: https://docs.phidata.com/templates/how-to/production-app
Your production application runs on AWS and its resources are defined in the `workspace/prd_resources.py` file. This guide shows how to:
1. [Build a production image](#build-your-production-image)
2. [Update ECS Task Definitions](#ecs-task-definition)
3. [Update ECS Services](#ecs-service)
## Workspace Settings
The `WorkspaceSettings` object in the `workspace/settings.py` file defines common settings used by your workspace apps and resources.
## Build your production image
Your application uses the `phidata` images by default. To use your own image:
* Create a Repository in `ECR` and authenticate or use `Dockerhub`.
* Open `workspace/settings.py` file
* Update the `image_repo` to your image repository
* Set `build_images=True` and `push_images=True`
* Optional - Set `build_images=False` and `push_images=False` to use an existing image in the repository
### Create an ECR Repository
To use ECR, **create the image repo and authenticate with ECR** before pushing images.
**1. Create the image repository in ECR**
The repo name should match the `ws_name`. Meaning if you're using the default workspace name, the repo name would be `ai`.
**2. Authenticate with ECR**
```bash Authenticate with ECR
aws ecr get-login-password --region [region] | docker login --username AWS --password-stdin [account].dkr.ecr.[region].amazonaws.com
```
You can also use a helper script to avoid running the full command
Update the script with your ECR repo before running.
```bash Mac
./scripts/auth_ecr.sh
```
### Update the `WorkspaceSettings`
```python workspace/settings.py
ws_settings = WorkspaceSettings(
...
# Subnet IDs in the aws_region
subnet_ids=["subnet-xyz", "subnet-xyz"],
# -*- Image Settings
# Repository for images
image_repo="your-image-repo",
# Build images locally
build_images=True,
# Push images after building
push_images=True,
)
```
The `image_repo` defines the repo for your image.
* If using dockerhub it would be something like `phidata`.
* If using ECR it would be something like `[ACCOUNT_ID].dkr.ecr.us-east-1.amazonaws.com`
### Build a new image
Build the production image using:
```bash terminal
phi ws up --env prd --infra docker --type image
```
```bash shorthand
phi ws up -e prd -i docker -t image
```
To `force` rebuild images, use the `--force` or `-f` flag
```bash terminal
phi ws up --env prd --infra docker --type image --force
```
```bash shorthand
phi ws up -e prd -i docker -t image -f
```
Because the only docker resources in the production env are docker images, you can also use:
```bash Build Images
phi ws up prd:docker
```
```bash Force Build Images
phi ws up prd:docker -f
```
## ECS Task Definition
If you updated the Image, CPU, Memory or Environment Variables, update the Task Definition using:
```bash terminal
phi ws patch --env prd --infra aws --name td
```
```bash shorthand
phi ws patch -e prd -i aws -n td
```
## ECS Service
To redeploy the production application, update the ECS Service using:
```bash terminal
phi ws patch --env prd --infra aws --name service
```
```bash shorthand
phi ws patch -e prd -i aws -n service
```
If you **ONLY** rebuilt the image, you do not need to update the task definition and can just patch the service to pickup the new image.
# Add Secrets
Source: https://docs.phidata.com/templates/how-to/secrets
Secret management is a critical part of your application security and should be taken seriously.
Local secrets are defined in the `worspace/secrets` directory which is excluded from version control (see `.gitignore`). Its contents should be handled with the same security as passwords.
Production secrets are managed by [AWS Secrets Manager](https://docs.aws.amazon.com/secretsmanager/latest/userguide/intro.html).
Incase you're missing the secrets dir, copy `workspace/example_secrets`
## Development Secrets
Apps running locally can read secrets using a `yaml` file, for example:
```python dev_resources.py
dev_fastapi = FastApi(
...
# Read secrets from secrets/dev_app_secrets.yml
secrets_file=ws_settings.ws_root.joinpath("workspace/secrets/dev_app_secrets.yml"),
)
```
## Production Secrets
`AWS Secrets` are used to manage production secrets, which are read by the production apps.
```python prd_resources.py
# -*- Secrets for production application
prd_secret = SecretsManager(
...
# Create secret from workspace/secrets/prd_app_secrets.yml
secret_files=[
ws_settings.ws_root.joinpath("workspace/secrets/prd_app_secrets.yml")
],
)
# -*- Secrets for production database
prd_db_secret = SecretsManager(
...
# Create secret from workspace/secrets/prd_db_secrets.yml
secret_files=[ws_settings.ws_root.joinpath("workspace/secrets/prd_db_secrets.yml")],
)
```
Read the secret in production apps using:
```python FastApi
prd_fastapi = FastApi(
...
aws_secrets=[prd_secret],
...
)
```
```python RDS
prd_db = DbInstance(
...
aws_secret=prd_db_secret,
...
)
```
Production resources can also read secrets using yaml files but we highly recommend using [AWS Secrets](https://docs.aws.amazon.com/secretsmanager/latest/userguide/intro.html).
# SSH Access
Source: https://docs.phidata.com/templates/how-to/ssh-access
SSH Access is an important part of the developer workflow.
## Dev SSH Access
SSH into the dev containers using the `docker exec` command
```bash
docker exec -it ai-api zsh
```
## Production SSH Access
Your ECS tasks are already enabled with SSH access. SSH into the production containers using:
```bash
ECS_CLUSTER=ai-app-prd-cluster
TASK_ARN=$(aws ecs list-tasks --cluster ai-app-prd-cluster --query "taskArns[0]" --output text)
CONTAINER_NAME=ai-api-prd
aws ecs execute-command --cluster $ECS_CLUSTER \
--task $TASK_ARN \
--container $CONTAINER_NAME \
--interactive \
--command "zsh"
```
# Workspace Settings
Source: https://docs.phidata.com/templates/how-to/workspace-settings
The `WorkspaceSettings` object in the `workspace/settings.py` file defines common settings used by your apps and resources. Here are the settings we recommend updating:
```python workspace/settings.py
ws_settings = WorkspaceSettings(
# Update this to your project name
ws_name="ai",
# Add your AWS subnets
subnet_ids=["subnet-xyz", "subnet-xyz"],
# Add your image repository
image_repo="[ACCOUNT_ID].dkr.ecr.us-east-1.amazonaws.com",
# Set to True to build images locally
build_images=True,
# Set to True to push images after building
push_images=True,
)
```
`WorkspaceSettings` can also be updated using environment variables or the `.env` file.
Checkout the `example.env` file for an example.
### Workspace Name
The `ws_name` is used to name your apps and resources. Change it to your project or team name, for example:
* `ws_name="booking-ai"`
* `ws_name="reddit-ai"`
* `ws_name="vantage-ai"`
The `ws_name` is used to name:
* The image for your application
* Apps like db, streamlit app and fastapi server
* Resources like buckets, secrets and loadbalancers
Checkout the `workspace/dev_resources.py` and `workspace/prd_resources.py` file to see how its used.
## Image Repository
The `image_repo` defines the repo for your image.
* If using dockerhub it would be something like `phidata`.
* If using ECR it would be something like `[ACCOUNT_ID].dkr.ecr.us-east-1.amazonaws.com`
Checkout the `dev_image` in `workspace/dev_resources.py` and `prd_image` in `workspace/prd_resources.py` to see how its used.
## Build Images
Setting `build_images=True` will build images locally when running `phi ws up dev:docker` or `phi ws up prd:docker`.
Checkout the `dev_image` in `workspace/dev_resources.py` and `prd_image` in `workspace/prd_resources.py` to see how its used.
Read more about:
* [Building your development image](/templates/how-to/development-app#build-your-development-image)
* [Building your production image](/templates/how-to/production-app#build-your-production-image)
## Push Images
Setting `push_images=True` will push images after building when running `phi ws up dev:docker` or `phi ws up prd:docker`.
Checkout the `dev_image` in `workspace/dev_resources.py` and `prd_image` in `workspace/prd_resources.py` to see how its used.
Read more about:
* [Building your development image](/templates/how-to/development-app#build-your-development-image)
* [Building your production image](/templates/how-to/production-app#build-your-production-image)
## AWS Settings
The `aws_region` and `subnet_ids` provide values used for creating production resources. Checkout the `workspace/prd_resources.py` file to see how its used.
# Introduction
Source: https://docs.phidata.com/templates/introduction
To run agents in production, we need to:
1. Serve them using an application like **FastApi**, **Django** or **Streamlit**.
2. Manage their sessions, memory and knowlege in a database.
3. Monitor, evaluate and improve their performance.
Phidata not only makes building Agents easy but also provides templates that can be deployed to AWS with 1 command. Here's how they work:
* Create your codebase using a template: `phi ws create`
* Run your application locally: `phi ws up`
* Run your application on AWS: `phi ws up prd:aws`
We strongly believe that data used by AI applications should be stored securely inside your VPC.
We fully support BYOC (Bring Your Own Cloud) and encourage you to use your own AWS account.
## Templates
We recommend starting with the `agent-app` template and adding your own agents.
Run agents using FastApi, Streamlit and store memory and knowlege in Postgres
Run agents using FastApi and store memory and knowlege in Postgres
# ECS
Source: https://docs.phidata.com/templates/resources/aws/ecs
This guide is in the works
# AWS Resources
Source: https://docs.phidata.com/templates/resources/aws/introduction
AWS Resources enable us to create AWS services as pydantic objects, completing our vision of writing software, application and infrastructure code entirely in python.
## Examples
### S3 Bucket
Copy the following code to a file `resources.py` and run `phi start resources.py` to create a bucket called `my-bucket-885`.
```python resources.py
from phi.aws.resource.s3 import S3Bucket
# -*- S3 bucket called my-bucket-885
prd_bucket = S3Bucket(name="my-bucket-885")
```
Make sure to delete the bucket using `phi stop resources.py`
### Secret Manager
Copy the following code to a file `resources.py` and run `phi start resources.py` to create a secret called `my-secret`.
```python resources.py
import json
from phi.aws.resource.secret import SecretsManager
# -*- Secret called my-secret
prd_secret = SecretsManager(
name="my-secret",
secret_string=json.dumps({"mysecretkey": "mysecretvalue"}),
# Read secret variables from my_secrets.yml
# secret_files=[Path('my_secrets.yml')],
)
```
Read the secret in another file called `read_my_secret.py`
```python read_my_secret.py
from resources import my_secret
print(my_secret.get_secret_value("mysecretkey"))
```
Run this file using `python read_my_secret.py`.
Delete the secret using `phi stop resources.py`
# RDS
Source: https://docs.phidata.com/templates/resources/aws/rds
This guide is in the works
# Container
Source: https://docs.phidata.com/templates/resources/docker/container
This guide is in the works
# Docker
Source: https://docs.phidata.com/templates/resources/docker/introduction
[Docker](https://docs.docker.com/get-started/overview/) is a game-changing technology that enables us to run applications locally. We package our [Apps](templates/apps/introduction) into **Containers** that include everything needed to run the application
## Docker Resources
Phidata enables us to define docker resources as pydantic objects so we can build our application layer purely in python. In most cases you will not be creating the **Docker Resources** directly, instead we'll use [Apps](templates/apps/introduction) to create the resources for us.
Docker Compose is more mature and defines resources as a "yaml configuration" whereas phidata allows us to define resources as "python objects".
We still love docker-compose, just want to elevate the experience. With phidata we rarely define the resources directly, instead we use Apps to create the resources for us.
### Benefits
* Define containers and images as pydantic objects with input and type validation.
* Allows re-use and testing of resources.
* Import them in software layer like regular python objects.
* Package multiple resources into [Apps](templates/apps/introduction) so we can define **"Applications as Code"**.
* Enable AI features that interact with the resource from python code.
## Container
The `DockerContainer` class defines a container, for example use the following code to define a container running the [whoami](https://github.com/traefik/whoami) image. Start it using `phi start resources.py`
```python resources.py
from phi.docker.resource.container import DockerContainer
whoami = DockerContainer(
name='whoami',
image='traefik/whoami',
ports={'80': 80},
)
```
Test it by opening [http://localhost:80](http://localhost:80) or using:
```bash
curl -X POST http://localhost:80
```
The same can be defined as an `App`:
```python resources.py
from phi.docker.app.whoami import Whoami
whoami = Whoami()
```
Stop resources using `phi stop resources.py`
## Image
The `DockerImage` class defines an image, for example use the following code create your own python image and run it in a container. Build it using `phi start resources.py`
```python resources.py
from phi.docker.resource.container import DockerContainer
from phi.docker.resource.image import DockerImage
python_image = DockerImage(
name="my/python",
tag="3.11",
path=".",
# push_image=True,
)
python_container = DockerContainer(
name='python',
image=python_image.get_image_str(),
)
```
```docker Dockerfile
FROM phidata/python:3.11.5
CMD ["chill"]
```
Make sure to add the `Dockerfile` in the current directory.
# Introduction
Source: https://docs.phidata.com/templates/resources/introduction
Resources are the infrastructure components for your application. Similar to [Apps](/templates/apps/introduction), we define them as python classes and create using `phi start` or `phi ws up`.
## Examples
* **Local Resources**: Docker containers and images
* **Cloud Resources**: RDS database, S3 bucket, ECS services, task definitions, security groups
* **Kubernetes Resources**: Services, deployments
```python Docker Container
from phi.docker.resource.container import DockerContainer
whoami = DockerContainer(
name='whoami',
image='traefik/whoami',
ports={'80': 8080},
)
```
```python Docker Image
from phi.docker.resource.image import DockerImage
dev_image = DockerImage(
name="repo/image",
tag="latest",
push_image=True,,
)
```
```python S3 Bucket
from phi.aws.resource.s3 import S3Bucket
# -*- S3 bucket called my-bucket
prd_bucket = S3Bucket(name="my-bucket")
```
```python Secret
from pathlib import Path
from phi.aws.resource.secret import SecretsManager
# -*- Secret called my-secret
my_secret = SecretsManager(
name="my-secret",
# Read secret variables from my_secrets.yml
secret_files=[Path('my_secrets.yml')],
)
```
```python RDS Database
from pathlib import Path
from phi.aws.resource.secret import SecretsManager
# -*- Database Secret
db_secret = SecretsManager(
name="my-db-secret",
# Read secret variables from db_secrets.yml
secret_files=[Path('db_secrets.yml')],
)
# -*- Database Subnet Group
db_subnet_group = DbSubnetGroup(name="my-db-sg")
# -*- Database Instance
db = DbInstance(
name="my-db",
db_name="llm",
port=5423,
engine="postgres",
engine_version="16.1",
allocated_storage=64,
db_instance_class="db.t4g.medium",
db_subnet_group=db_subnet_group,
availability_zone="us-east-1a",
publicly_accessible=True,
aws_secret=db_secret,
)
```
Each Resource is a pydantic object providing input and type validation.
## Motivation
Resources provide the **"Infrastructure Layer"** for our AI products. The software we write needs to be served by an Application, which in turn needs to run on an Infrastructure Resoure.
Defining **Applications as Code** and **Infrastructure as Code** allows us completely write our application as python code - providing numerous benefits like re-usability, version control, unit testing, formatting.
Phidata currently provides:
* [Docker Resources](/templates/resources/docker/introduction)
* [AWS Resources](/templates/resources/aws/introduction)
# Introduction
Source: https://docs.phidata.com/templates/workspace/introduction
A phidata template creates a **Workspace**, which is just an umbrella term for your codebase.
## Create new workspace
Run `phi ws create` to create a new workspace using a phidata template
```bash Create Workspace
phi ws create
```
```bash Create AI App
phi ws create -t ai-app -n ai-app
```
```bash Create AI Api
phi ws create -t api-app -n api-app
```
```bash Create Django App
phi ws create -t django-app -n web-app
```
`phi` will ask for a workspace template and name if not provided.
## Setup existing workspace
Run `phi ws setup` to setup an existing directory as a phidata workspace
```bash terminal
phi ws setup
```
```bash with debug logs
phi ws setup -d
```
## Start workspace
Run `phi ws up` to create workspace resources
```bash terminal
phi ws up
```
```bash shorthand
phi ws up dev:docker
```
```bash full options
phi ws up --env dev --infra docker
```
```bash short options
phi ws up -e dev -i docker
```
## Stop workspace
Run `phi ws down` to delete workspace resources
```bash terminal
phi ws down
```
```bash shorthand
phi ws down dev:docker
```
```bash full options
phi ws down --env dev --infra docker
```
```bash short options
phi ws down -e dev -i docker
```
## Patch workspace
Run `phi ws patch` to update workspace resources
```bash terminal
phi ws patch
```
```bash shorthand
phi ws patch dev:docker
```
```bash full options
phi ws patch --env dev --infra docker
```
```bash short options
phi ws patch -e dev -i docker
```
The `patch` command in under development for some resources. Use `restart` if needed
## Restart workspace
Run `phi ws restart` to stop resources and start them again
```bash terminal
phi ws restart
```
```bash shorthand
phi ws restart dev:docker
```
```bash full options
phi ws restart --env dev --infra docker
```
```bash short options
phi ws restart -e dev -i docker
```
## Command Options
Run `phi ws up --help` to view all options
### Environment (`--env`)
Use the `--env` or `-e` flag to filter the environment (dev/prd)
```bash flag
phi ws up --env dev
```
```bash shorthand
phi ws up dev
```
```bash short options
phi ws up -e dev
```
### Infra (`--infra`)
Use the `--infra` or `-i` flag to filter the infra (docker/aws/k8s)
```bash flag
phi ws up --infra docker
```
```bash shorthand
phi ws up :docker
```
```bash short options
phi ws up -i docker
```
### Group (`--group`)
Use the `--group` or `-g` flag to filter by resource group.
```bash flag
phi ws up --group app
```
```bash full options
phi ws up \
--env dev \
--infra docker \
--group app
```
```bash shorthand
phi ws up dev:docker:app
```
```bash short options
phi ws up \
-e dev \
-i docker \
-g app
```
### Name (`--name`)
Use the `--name` or `-n` flag to filter by resource name
```bash flag
phi ws up --name app
```
```bash full options
phi ws up \
--env dev \
--infra docker \
--name app
```
```bash shorthand
phi ws up dev:docker::app
```
```bash short options
phi ws up \
-e dev \
-i docker \
-n app
```
### Type (`--type`)
Use the `--type` or `-t` flag to filter by resource type.
```bash flag
phi ws up --type container
```
```bash full options
phi ws up \
--env dev \
--infra docker \
--type container
```
```bash shorthand
phi ws up dev:docker:app::container
```
```bash short options
phi ws up \
-e dev \
-i docker \
-t container
```
### Dry Run (`--dry-run`)
The `--dry-run` or `-dr` flag can be used to **dry-run** the command. `phi ws up -dr` will only print resources, not create them.
```bash flag
phi ws up --dry-run
```
```bash full options
phi ws up \
--env dev \
--infra docker \
--dry-run
```
```bash shorthand
phi ws up dev:docker -dr
```
```bash short options
phi ws up \
-e dev \
-i docker \
-dr
```
### Show Debug logs (`--debug`)
Use the `--debug` or `-d` flag to show debug logs.
```bash flag
phi ws up -d
```
```bash full options
phi ws up \
--env dev \
--infra docker \
-d
```
```bash shorthand
phi ws up dev:docker -d
```
```bash short options
phi ws up \
-e dev \
-i docker \
-d
```
### Force recreate images & containers (`-f`)
Use the `--force` or `-f` flag to force recreate images & containers
```bash flag
phi ws up -f
```
```bash full options
phi ws up \
--env dev \
--infra docker \
-f
```
```bash shorthand
phi ws up dev:docker -f
```
```bash short options
phi ws up \
-e dev \
-i docker \
-f
```
# Workspace Resources
Source: https://docs.phidata.com/templates/workspace/resources
The `workspace` directory in a codebase contains the resources that are created/deleted using `phi ws up`/`phi ws down`.
Any `.py` file in the `workspace` containing a `DockerResources`, `AwsResources` or `K8sResources` object can be used to define the workspace resources.
To add your own resources, just create a python file, define resources and add them to a `DockerResources`, `AwsResources` or `K8sResources` object.
## Example
### DockerResources
```python workspace/dev_resources.py
from phi.docker.app.fastapi import FastApi
from phi.docker.app.postgres import PgVectorDb
from phi.docker.app.streamlit import Streamlit
from phi.docker.resources import DockerResources
#
# -*- Resources for the Development Environment
#
# -*- Dev image
dev_image = DockerImage(
...
)
# -*- Dev database running on port 5432:5432
dev_db = PgVectorDb(
...
)
# -*- Streamlit running on port 8501:8501
dev_streamlit = Streamlit(
...
)
# -*- FastApi running on port 8000:8000
dev_fastapi = FastApi(
...
)
# -*- Dev DockerResources
dev_docker_resources = DockerResources(
env=ws_settings.dev_env,
network=ws_settings.ws_name,
apps=[dev_db, dev_streamlit, dev_fastapi, dev_jupyter_app],
)
```
### AwsResources
```python workspace/prd_resources.py
from phi.aws.app.fastapi import FastApi
from phi.aws.app.streamlit import Streamlit
from phi.aws.resources import AwsResources
from phi.aws.resource.ecs import EcsCluster
from phi.aws.resource.ec2 import SecurityGroup, InboundRule
from phi.aws.resource.rds import DbInstance, DbSubnetGroup
from phi.aws.resource.reference import AwsReference
from phi.aws.resource.s3 import S3Bucket
from phi.aws.resource.secret import SecretsManager
from phi.docker.resources import DockerResources
from phi.docker.resource.image import DockerImage
#
# -*- Resources for the Production Environment
#
# -*- Production image
prd_image = DockerImage(
...
)
# -*- S3 bucket for production data
prd_bucket = S3Bucket(
...
)
# -*- Secrets for production application
prd_secret = SecretsManager(
...
)
# -*- Secrets for production database
prd_db_secret = SecretsManager(
...
)
# -*- Security Group for the load balancer
prd_lb_sg = SecurityGroup(
...
)
# -*- Security Group for the application
prd_sg = SecurityGroup(
...
)
# -*- Security Group for the database
prd_db_port = 5432
prd_db_sg = SecurityGroup(
...
)
# -*- RDS Database Subnet Group
prd_db_subnet_group = DbSubnetGroup(
...
)
# -*- RDS Database Instance
prd_db = DbInstance(
...
)
# -*- Streamlit running on ECS
prd_streamlit = Streamlit(
...
)
# -*- FastApi running on ECS
prd_fastapi = FastApi(
...
)
# -*- Production DockerResources
prd_docker_resources = DockerResources(
env=ws_settings.prd_env,
network=ws_settings.ws_name,
resources=[prd_image],
)
# -*- Production AwsResources
prd_aws_resources = AwsResources(
env=ws_settings.prd_env,
apps=[prd_streamlit, prd_fastapi],
resources=[prd_lb_sg, prd_sg, prd_db_sg, prd_secret, prd_db_secret, prd_db_subnet_group, prd_db, prd_bucket],
)
```
# Workspace Settings
Source: https://docs.phidata.com/templates/workspace/settings
The `WorkspaceSettings` object, usually defined in the `workspace/settings.py` file is used to defines common settings used by your workspace apps and resources.
Its not mandatory and doesn't serve any other purpose except to hold configuration used by workspace apps and resources. The values in the `WorkspaceSettings` object can also be set using Environment variables or a `.env` file.
## Example
An example `WorkspaceSettings` used by the `llm-app` template. View this file on [github](https://github.com/phidatahq/llm-app/blob/main/workspace/settings.py)
```python workspace/settings.py
from pathlib import Path
from phi.workspace.settings import WorkspaceSettings
#
# -*- Define workspace settings using a WorkspaceSettings object
# these values can also be set using environment variables or a .env file
#
ws_settings = WorkspaceSettings(
# Workspace name: used for naming resources
ws_name="ai",
# Path to the workspace root
ws_root=Path(__file__).parent.parent.resolve(),
# -*- Dev settings
dev_env="dev",
# -*- Dev Apps
dev_app_enabled=True,
dev_api_enabled=True,
dev_db_enabled=True,
# dev_jupyter_enabled=True,
# -*- Production settings
prd_env="prd",
# -*- Production Apps
prd_app_enabled=True,
prd_api_enabled=True,
prd_db_enabled=True,
# -*- AWS settings
# Region for AWS resources
aws_region="us-east-1",
# Availability Zones for AWS resources
aws_az1="us-east-1a",
aws_az2="us-east-1b",
# Subnet IDs in the aws_region
# subnet_ids=["subnet-xyz", "subnet-xyz"],
#
# -*- Image Settings
#
# Default repository for images
image_repo="phidata"
# Build images locally
build_images=False
# Push images after building
push_images=False
# Skip cache when building images
skip_image_cache=False
# Force pull images in FROM
force_pull_images=False
)
```
## Usage
Use the workspace settings to
* Name resources
* Get the workspace root path using `ws_settings.ws_root`
```python dev_resources.py
...
# -*- Streamlit running on port 8501:8501
dev_streamlit = Streamlit(
name=f"{ws_settings.dev_key}-app",
enabled=ws_settings.dev_app_enabled,
...
# Read secrets from secrets/dev_app_secrets.yml
secrets_file=ws_settings.ws_root.joinpath("workspace/secrets/dev_app_secrets.yml")
)
```
* Hold AWS constants like `availability zone` and `subnets`
```python prd_resources.py
# -*- FastApi running on ECS
prd_fastapi = FastApi(
name=f"{ws_settings.prd_key}-api",
enabled=ws_settings.prd_api_enabled,
...
subnets=ws_settings.subnet_ids,
...
)
# -*- RDS Database Instance
prd_db = DbInstance(
name=f"{ws_settings.prd_key}-db",
enabled=ws_settings.prd_db_enabled,
...
availability_zone=ws_settings.aws_az1,
...
)
```
# Airflow
Source: https://docs.phidata.com/tools/airflow
## Example
The following agent will use Airflow to save and read a DAG file.
```python cookbook/tools/airflow_tools.py
from phi.agent import Agent
from phi.tools.airflow import AirflowToolkit
agent = Agent(
tools=[AirflowToolkit(dags_dir="dags", save_dag=True, read_dag=True)], show_tool_calls=True, markdown=True
)
dag_content = """
from airflow import DAG
from airflow.operators.python import PythonOperator
from datetime import datetime, timedelta
default_args = {
'owner': 'airflow',
'depends_on_past': False,
'start_date': datetime(2024, 1, 1),
'email_on_failure': False,
'email_on_retry': False,
'retries': 1,
'retry_delay': timedelta(minutes=5),
}
# Using 'schedule' instead of deprecated 'schedule_interval'
with DAG(
'example_dag',
default_args=default_args,
description='A simple example DAG',
schedule='@daily', # Changed from schedule_interval
catchup=False
) as dag:
def print_hello():
print("Hello from Airflow!")
return "Hello task completed"
task = PythonOperator(
task_id='hello_task',
python_callable=print_hello,
dag=dag,
)
"""
agent.run(f"Save this DAG file as 'example_dag.py': {dag_content}")
agent.print_response("Read the contents of 'example_dag.py'")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ---------- | --------------- | ---------------- | ------------------------------------------------ |
| `dags_dir` | `Path` or `str` | `Path.cwd()` | Directory for DAG files |
| `save_dag` | `bool` | `True` | Whether to register the save\_dag\_file function |
| `read_dag` | `bool` | `True` | Whether to register the read\_dag\_file function |
| `name` | `str` | `"AirflowTools"` | The name of the tool |
## Toolkit Functions
| Function | Description |
| --------------- | -------------------------------------------------- |
| `save_dag_file` | Saves python code for an Airflow DAG to a file |
| `read_dag_file` | Reads an Airflow DAG file and returns the contents |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/airflow.py)
# Apify
Source: https://docs.phidata.com/tools/apify
**ApifyTools** enable an Agent to access the Apify API and run actors.
## Prerequisites
The following example requires the `apify-client` library and an API token which can be obtained from [Apify](https://apify.com/).
```shell
pip install -U apify-client
```
```shell
export MY_APIFY_TOKEN=***
```
## Example
The following agent will use Apify to crawl the webpage: [https://docs.phidata.com/introduction](https://docs.phidata.com/introduction) and summarize it.
```python cookbook/tools/apify_tools.py
from phi.agent import Agent
from phi.tools.apify import ApifyTools
agent = Agent(tools=[ApifyTools()], show_tool_calls=True)
agent.print_response("Tell me about https://docs.phidata.com/introduction", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------------- | ------ | ------- | --------------------------------------------------------------------------------- |
| `api_key` | `str` | - | API key for authentication purposes. |
| `website_content_crawler` | `bool` | `True` | Enables the functionality to crawl a website using website-content-crawler actor. |
| `web_scraper` | `bool` | `False` | Enables the functionality to crawl a website using web\_scraper actor. |
## Toolkit Functions
| Function | Description |
| ------------------------- | ------------------------------------------------------------- |
| `website_content_crawler` | Crawls a website using Apify's website-content-crawler actor. |
| `web_scrapper` | Scrapes a website using Apify's web-scraper actor. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/apify.py)
# Arxiv
Source: https://docs.phidata.com/tools/arxiv
**ArxivTools** enable an Agent to search for publications on Arxiv.
## Prerequisites
The following example requires the `arxiv` and `pypdf` libraries.
```shell
pip install -U arxiv pypdf
```
## Example
The following agent will run seach arXiv for "language models" and print the response.
```python cookbook/tools/arxiv_tools.py
from phi.agent import Agent
from phi.tools.arxiv_toolkit import ArxivToolkit
agent = Agent(tools=[ArxivToolkit()], show_tool_calls=True)
agent.print_response("Search arxiv for 'language models'", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------- | ------ | ------- | ------------------------------------------------------------------ |
| `search_arxiv` | `bool` | `True` | Enables the functionality to search the arXiv database. |
| `read_arxiv_papers` | `bool` | `True` | Allows reading of arXiv papers directly. |
| `download_dir` | `Path` | - | Specifies the directory path where downloaded files will be saved. |
## Toolkit Functions
| Function | Description |
| ---------------------------------------- | -------------------------------------------------------------------------------------------------- |
| `search_arxiv_and_update_knowledge_base` | This function searches arXiv for a topic, adds the results to the knowledge base and returns them. |
| `search_arxiv` | Searches arXiv for a query. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/arxiv_toolkit.py)
# AWS Lambda
Source: https://docs.phidata.com/tools/aws_lambda
## Prerequisites
The following example requires the `boto3` library.
```shell
pip install openai boto3
```
## Example
The following agent will use AWS Lambda to list all Lambda functions in our AWS account and invoke a specific Lambda function.
```python cookbook/tools/aws_lambda_tools.py
from phi.agent import Agent
from phi.tools.aws_lambda import AWSLambdaTool
# Create an Agent with the AWSLambdaTool
agent = Agent(
tools=[AWSLambdaTool(region_name="us-east-1")],
name="AWS Lambda Agent",
show_tool_calls=True,
)
# Example 1: List all Lambda functions
agent.print_response("List all Lambda functions in our AWS account", markdown=True)
# Example 2: Invoke a specific Lambda function
agent.print_response("Invoke the 'hello-world' Lambda function with an empty payload", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------- | ----- | ------------- | --------------------------------------------------- |
| `region_name` | `str` | `"us-east-1"` | AWS region name where Lambda functions are located. |
## Toolkit Functions
| Function | Description |
| ----------------- | --------------------------------------------------------------------------------------------------------------------- |
| `list_functions` | Lists all Lambda functions available in the AWS account. |
| `invoke_function` | Invokes a specific Lambda function with an optional payload. Takes `function_name` and optional `payload` parameters. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/aws_lambda.py)
# BaiduSearch
Source: https://docs.phidata.com/tools/baidusearch
**BaiduSearch** enables an Agent to search the web for information using the Baidu search engine.
## Prerequisites
The following example requires the `baidusearch` library. To install BaiduSearch, run the following command:
```shell
pip install -U baidusearch
```
## Example
```python cookbook/tools/baidusearch_tools.py
from phi.agent import Agent
from phi.tools.baidusearch import BaiduSearch
agent = Agent(
tools=[BaiduSearch()],
description="You are a search agent that helps users find the most relevant information using Baidu.",
instructions=[
"Given a topic by the user, respond with the 3 most relevant search results about that topic.",
"Search for 5 results and select the top 3 unique items.",
"Search in both English and Chinese.",
],
show_tool_calls=True,
)
agent.print_response("What are the latest advancements in AI?", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------- | ----- | ------- | ---------------------------------------------------------------------------------------------------- |
| `fixed_max_results` | `int` | - | Sets a fixed number of maximum results to return. No default is provided, must be specified if used. |
| `fixed_language` | `str` | - | Set the fixed language for the results. |
| `headers` | `Any` | - | Headers to be used in the search request. |
| `proxy` | `str` | - | Specifies a single proxy address as a string to be used for the HTTP requests. |
| `timeout` | `int` | `10` | Sets the timeout for HTTP requests, in seconds. |
## Toolkit Functions
| Function | Description |
| -------------- | ---------------------------------------------- |
| `baidu_search` | Use this function to search Baidu for a query. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/baidusearch.py)
# Cal.com
Source: https://docs.phidata.com/tools/calcom
## Prerequisites
The following example requires the `pytz` and `requests` libraries.
```shell
pip install requests pytz
```
```shell
export CALCOM_API_KEY="your_api_key"
export CALCOM_EVENT_TYPE_ID="your_event_type_id"
```
## Example
The following agent will use Cal.com to list all events in your Cal.com account for tomorrow.
```python cookbook/tools/calcom_tools.py
agent = Agent(
name="Calendar Assistant",
instructions=[
f"You're scheduing assistant. Today is {datetime.now()}.",
"You can help users by:",
"- Finding available time slots",
"- Creating new bookings",
"- Managing existing bookings (view, reschedule, cancel) ",
"- Getting booking details",
"- IMPORTANT: In case of rescheduling or cancelling booking, call the get_upcoming_bookings function to get the booking uid. check available slots before making a booking for given time",
"Always confirm important details before making bookings or changes.",
],
model=OpenAIChat(id="gpt-4"),
tools=[CalCom(user_timezone="America/New_York")],
show_tool_calls=True,
markdown=True,
)
agent.print_response("What are my bookings for tomorrow?")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ----------------------- | ------ | ------- | ------------------------------------------ |
| `api_key` | `str` | `None` | Cal.com API key |
| `event_type_id` | `int` | `None` | Event type ID for scheduling |
| `user_timezone` | `str` | `None` | User's timezone (e.g. "America/New\_York") |
| `get_available_slots` | `bool` | `True` | Enable getting available time slots |
| `create_booking` | `bool` | `True` | Enable creating new bookings |
| `get_upcoming_bookings` | `bool` | `True` | Enable getting upcoming bookings |
| `reschedule_booking` | `bool` | `True` | Enable rescheduling bookings |
| `cancel_booking` | `bool` | `True` | Enable canceling bookings |
## Toolkit Functions
| Function | Description |
| ----------------------- | ------------------------------------------------ |
| `get_available_slots` | Gets available time slots for a given date range |
| `create_booking` | Creates a new booking with provided details |
| `get_upcoming_bookings` | Gets list of upcoming bookings |
| `get_booking_details` | Gets details for a specific booking |
| `reschedule_booking` | Reschedules an existing booking |
| `cancel_booking` | Cancels an existing booking |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/calcom.py)
# Calculator
Source: https://docs.phidata.com/tools/calculator
**Calculator** enables an Agent to perform mathematical calculations.
## Example
The following agent will calculate the result of `10*5` and then raise it to the power of `2`:
```python cookbook/tools/calculator_tools.py
from phi.agent import Agent
from phi.tools.calculator import Calculator
agent = Agent(
tools=[
Calculator(
add=True,
subtract=True,
multiply=True,
divide=True,
exponentiate=True,
factorial=True,
is_prime=True,
square_root=True,
)
],
show_tool_calls=True,
markdown=True,
)
agent.print_response("What is 10*5 then to the power of 2, do it step by step")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| -------------- | ------ | ------- | ------------------------------------------------------------------- |
| `add` | `bool` | `True` | Enables the functionality to perform addition. |
| `subtract` | `bool` | `True` | Enables the functionality to perform subtraction. |
| `multiply` | `bool` | `True` | Enables the functionality to perform multiplication. |
| `divide` | `bool` | `True` | Enables the functionality to perform division. |
| `exponentiate` | `bool` | `False` | Enables the functionality to perform exponentiation. |
| `factorial` | `bool` | `False` | Enables the functionality to calculate the factorial of a number. |
| `is_prime` | `bool` | `False` | Enables the functionality to check if a number is prime. |
| `square_root` | `bool` | `False` | Enables the functionality to calculate the square root of a number. |
## Toolkit Functions
| Function | Description |
| -------------- | ---------------------------------------------------------------------------------------- |
| `add` | Adds two numbers and returns the result. |
| `subtract` | Subtracts the second number from the first and returns the result. |
| `multiply` | Multiplies two numbers and returns the result. |
| `divide` | Divides the first number by the second and returns the result. Handles division by zero. |
| `exponentiate` | Raises the first number to the power of the second number and returns the result. |
| `factorial` | Calculates the factorial of a number and returns the result. Handles negative numbers. |
| `is_prime` | Checks if a number is prime and returns the result. |
| `square_root` | Calculates the square root of a number and returns the result. Handles negative numbers. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/calculator.py)
# Composio
Source: https://docs.phidata.com/tools/composio
[**ComposioTools**](https://docs.composio.dev/framework/phidata) enable an Agent to work with tools like Gmail, Salesforce, Github, etc.
## Prerequisites
The following example requires the `composio-phidata` library.
```shell
pip install composio-phidata
composio add github # Login into Github
```
## Example
The following agent will use Github Tool from Composio Toolkit to star a repo.
```python cookbook/tools/composio_tools.py
from phi.agent import Agent
from composio_phidata import Action, ComposioToolSet
toolset = ComposioToolSet()
composio_tools = toolset.get_tools(
actions=[Action.GITHUB_STAR_A_REPOSITORY_FOR_THE_AUTHENTICATED_USER]
)
agent = Agent(tools=composio_tools, show_tool_calls=True)
agent.print_response("Can you star agno-agi/phidata repo?")
```
## Toolkit Params
The following parameters are used when calling the GitHub star repository action:
| Parameter | Type | Default | Description |
| --------- | ----- | ------- | ------------------------------------ |
| `owner` | `str` | - | The owner of the repository to star. |
| `repo` | `str` | - | The name of the repository to star. |
## Toolkit Functions
Composio Toolkit provides 1000+ functions to connect to different software tools.
Open this [link](https://composio.dev/tools) to view the complete list of functions.
# Crawl4AI
Source: https://docs.phidata.com/tools/crawl4ai
**Crawl4aiTools** enable an Agent to perform web crawling and scraping tasks using the Crawl4ai library.
## Prerequisites
The following example requires the `crawl4ai` library.
```shell
pip install -U crawl4ai
```
## Example
The following agent will scrape the content from the [https://github.com/agno-agi/phidata](https://github.com/agno-agi/phidata) webpage:
```python cookbook/tools/crawl4ai_tools.py
from phi.agent import Agent
from phi.tools.crawl4ai_tools import Crawl4aiTools
agent = Agent(tools=[Crawl4aiTools(max_length=None)], show_tool_calls=True)
agent.print_response("Tell me about https://github.com/agno-agi/phidata.")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------ | ----- | ------- | ------------------------------------------------------------------------- |
| `max_length` | `int` | `1000` | Specifies the maximum length of the text from the webpage to be returned. |
## Toolkit Functions
| Function | Description |
| ------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `web_crawler` | Crawls a website using crawl4ai's WebCrawler. Parameters include 'url' for the URL to crawl and an optional 'max\_length' to limit the length of extracted content. The default value for 'max\_length' is 1000. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/crawl4ai_tools.py)
# CSV
Source: https://docs.phidata.com/tools/csv
**CsvTools** enable an Agent to read and write CSV files.
## Example
The following agent will download the IMDB csv file and allow the user to query it using a CLI app.
```python cookbook/tools/csv_tools.py
import httpx
from pathlib import Path
from phi.agent import Agent
from phi.tools.csv_tools import CsvTools
url = "https://phidata-public.s3.amazonaws.com/demo_data/IMDB-Movie-Data.csv"
response = httpx.get(url)
imdb_csv = Path(__file__).parent.joinpath("wip").joinpath("imdb.csv")
imdb_csv.parent.mkdir(parents=True, exist_ok=True)
imdb_csv.write_bytes(response.content)
agent = Agent(
tools=[CsvTools(csvs=[imdb_csv])],
markdown=True,
show_tool_calls=True,
instructions=[
"First always get the list of files",
"Then check the columns in the file",
"Then run the query to answer the question",
],
)
agent.cli_app(stream=False)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------- | ------------------------ | ------- | ---------------------------------------------------------------------- |
| `csvs` | `List[Union[str, Path]]` | - | A list of CSV files or paths to be processed or read. |
| `row_limit` | `int` | - | The maximum number of rows to process from each CSV file. |
| `read_csvs` | `bool` | `True` | Enables the functionality to read data from specified CSV files. |
| `list_csvs` | `bool` | `True` | Enables the functionality to list all available CSV files. |
| `query_csvs` | `bool` | `True` | Enables the functionality to execute queries on data within CSV files. |
| `read_column_names` | `bool` | `True` | Enables the functionality to read the column names from the CSV files. |
| `duckdb_connection` | `Any` | - | Specifies a connection instance for DuckDB database operations. |
| `duckdb_kwargs` | `Dict[str, Any]` | - | A dictionary of keyword arguments for configuring DuckDB operations. |
## Toolkit Functions
| Function | Description |
| ---------------- | ------------------------------------------------ |
| `list_csv_files` | Lists all available CSV files. |
| `read_csv_file` | This function reads the contents of a csv file |
| `get_columns` | This function returns the columns of a csv file |
| `query_csv_file` | This function queries the contents of a csv file |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/csv_tools.py)
# Writing your own Toolkit
Source: https://docs.phidata.com/tools/custom-toolkits
Many advanced use-cases will require writing custom Toolkits. Here's the general flow:
1. Create a class inheriting the `phi.tools.Toolkit` class.
2. Add your functions to the class.
3. **Important:** Register the functions using `self.register(function_name)`
Now your Toolkit is ready to use with an Agent. For example:
```python shell_toolkit.py
from typing import List
from phi.tools import Toolkit
from phi.utils.log import logger
class ShellTools(Toolkit):
def __init__(self):
super().__init__(name="shell_tools")
self.register(self.run_shell_command)
def run_shell_command(self, args: List[str], tail: int = 100) -> str:
"""Runs a shell command and returns the output or error.
Args:
args (List[str]): The command to run as a list of strings.
tail (int): The number of lines to return from the output.
Returns:
str: The output of the command.
"""
import subprocess
logger.info(f"Running shell command: {args}")
try:
logger.info(f"Running shell command: {args}")
result = subprocess.run(args, capture_output=True, text=True)
logger.debug(f"Result: {result}")
logger.debug(f"Return code: {result.returncode}")
if result.returncode != 0:
return f"Error: {result.stderr}"
# return only the last n lines of the output
return "\n".join(result.stdout.split("\n")[-tail:])
except Exception as e:
logger.warning(f"Failed to run shell command: {e}")
return f"Error: {e}"
```
# Dalle
Source: https://docs.phidata.com/tools/dalle
## Prerequisites
You need to install the `openai` library.
```bash
pip install openai
```
Set the `OPENAI_API_KEY` environment variable.
```bash
export OPENAI_API_KEY=****
```
## Example
The following agent will use DALL-E to generate an image based on a text prompt.
```python cookbook/tools/dalle_tools.py
from phi.agent import Agent
from phi.tools.dalle import Dalle
# Create an Agent with the DALL-E tool
agent = Agent(tools=[Dalle()], name="DALL-E Image Generator")
# Example 1: Generate a basic image with default settings
agent.print_response("Generate an image of a futuristic city with flying cars and tall skyscrapers", markdown=True)
# Example 2: Generate an image with custom settings
custom_dalle = Dalle(model="dall-e-3", size="1792x1024", quality="hd", style="natural")
agent_custom = Agent(
tools=[custom_dalle],
name="Custom DALL-E Generator",
show_tool_calls=True,
)
agent_custom.print_response("Create a panoramic nature scene showing a peaceful mountain lake at sunset", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------- | ----- | ------------- | ----------------------------------------------------------------- |
| `model` | `str` | `"dall-e-3"` | The DALL-E model to use |
| `n` | `int` | `1` | Number of images to generate |
| `size` | `str` | `"1024x1024"` | Image size (256x256, 512x512, 1024x1024, 1792x1024, or 1024x1792) |
| `quality` | `str` | `"standard"` | Image quality (standard or hd) |
| `style` | `str` | `"vivid"` | Image style (vivid or natural) |
| `api_key` | `str` | `None` | The OpenAI API key for authentication |
## Toolkit Functions
| Function | Description |
| ---------------- | ----------------------------------------- |
| `generate_image` | Generates an image based on a text prompt |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/dalle.py)
# DuckDb
Source: https://docs.phidata.com/tools/duckdb
**DuckDbTools** enable an Agent to run SQL and analyze data using DuckDb.
## Prerequisites
The following example requires DuckDB library. To install DuckDB, run the following command:
```shell
pip install duckdb
```
For more installation options, please refer to [DuckDB documentation](https://duckdb.org/docs/installation).
## Example
The following agent will analyze the movies file using SQL and return the result.
```python cookbook/tools/duckdb_tools.py
from phi.agent import Agent
from phi.tools.duckdb import DuckDbTools
agent = Agent(
tools=[DuckDbTools()],
show_tool_calls=True,
system_prompt="Use this file for Movies data: https://phidata-public.s3.amazonaws.com/demo_data/IMDB-Movie-Data.csv",
)
agent.print_response("What is the average rating of movies?", markdown=True, stream=False)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------ | -------------------- | ------- | ----------------------------------------------------------------- |
| `db_path` | `str` | - | Specifies the path to the database file. |
| `connection` | `DuckDBPyConnection` | - | Provides an existing DuckDB connection object. |
| `init_commands` | `List` | - | A list of initial SQL commands to run on database connection. |
| `read_only` | `bool` | `False` | Configures the database connection to be read-only. |
| `config` | `dict` | - | Configuration options for the database connection. |
| `run_queries` | `bool` | `True` | Determines whether to run SQL queries during the operation. |
| `inspect_queries` | `bool` | `False` | Enables inspection of SQL queries without executing them. |
| `create_tables` | `bool` | `True` | Allows creation of tables in the database during the operation. |
| `summarize_tables` | `bool` | `True` | Enables summarization of table data during the operation. |
| `export_tables` | `bool` | `False` | Allows exporting tables to external formats during the operation. |
## Toolkit Functions
| Function | Description |
| -------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `show_tables` | Function to show tables in the database |
| `describe_table` | Function to describe a table |
| `inspect_query` | Function to inspect a query and return the query plan. Always inspect your query before running them. |
| `run_query` | Function that runs a query and returns the result. |
| `summarize_table` | Function to compute a number of aggregates over a table. The function launches a query that computes a number of aggregates over all columns, including min, max, avg, std and approx\_unique. |
| `get_table_name_from_path` | Get the table name from a path |
| `create_table_from_path` | Creates a table from a path |
| `export_table_to_path` | Save a table in a desired format (default: parquet). If the path is provided, the table will be saved under that path. Eg: If path is /tmp, the table will be saved as /tmp/table.parquet. Otherwise it will be saved in the current directory |
| `load_local_path_to_table` | Load a local file into duckdb |
| `load_local_csv_to_table` | Load a local CSV file into duckdb |
| `load_s3_path_to_table` | Load a file from S3 into duckdb |
| `load_s3_csv_to_table` | Load a CSV file from S3 into duckdb |
| `create_fts_index` | Create a full text search index on a table |
| `full_text_search` | Full text Search in a table column for a specific text/keyword |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/duckdb.py)
# DuckDuckGo
Source: https://docs.phidata.com/tools/duckduckgo
**DuckDuckGo** enables an Agent to search the web for information.
## Prerequisites
The following example requires the `duckduckgo-search` library. To install DuckDuckGo, run the following command:
```shell
pip install -U duckduckgo-search
```
## Example
```python cookbook/tools/duckduckgo.py
from phi.agent import Agent
from phi.tools.duckduckgo import DuckDuckGo
agent = Agent(tools=[DuckDuckGo()], show_tool_calls=True)
agent.print_response("Whats happening in France?", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------- | ------ | ------- | ---------------------------------------------------------------------------------------------------- |
| `search` | `bool` | `True` | Enables the use of the `duckduckgo_search` function to search DuckDuckGo for a query. |
| `news` | `bool` | `True` | Enables the use of the `duckduckgo_news` function to fetch the latest news via DuckDuckGo. |
| `fixed_max_results` | `int` | - | Sets a fixed number of maximum results to return. No default is provided, must be specified if used. |
| `headers` | `Any` | - | Accepts any type of header values to be sent with HTTP requests. |
| `proxy` | `str` | - | Specifies a single proxy address as a string to be used for the HTTP requests. |
| `proxies` | `Any` | - | Accepts a dictionary of proxies to be used for HTTP requests. |
| `timeout` | `int` | `10` | Sets the timeout for HTTP requests, in seconds. |
## Toolkit Functions
| Function | Description |
| ------------------- | --------------------------------------------------------- |
| `duckduckgo_search` | Use this function to search DuckDuckGo for a query. |
| `duckduckgo_news` | Use this function to get the latest news from DuckDuckGo. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/duckduckgo.py)
# Email
Source: https://docs.phidata.com/tools/email
**EmailTools** enable an Agent to send an email to a user. The Agent can send an email to a user with a specific subject and body.
## Example
```python cookbook/tools/email_tools.py
from phi.agent import Agent
from phi.tools.email import EmailTools
receiver_email = ""
sender_email = ""
sender_name = ""
sender_passkey = ""
agent = Agent(
tools=[
EmailTools(
receiver_email=receiver_email,
sender_email=sender_email,
sender_name=sender_name,
sender_passkey=sender_passkey,
)
]
)
agent.print_response("send an email to ")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ---------------- | ----- | ------- | ----------------------------------- |
| `receiver_email` | `str` | - | The email address of the receiver. |
| `sender_name` | `str` | - | The name of the sender. |
| `sender_email` | `str` | - | The email address of the sender. |
| `sender_passkey` | `str` | - | The passkey for the sender's email. |
## Toolkit Functions
| Function | Description |
| ------------ | ---------------------------------------------------------------------------- |
| `email_user` | Emails the user with the given subject and body. Currently works with Gmail. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/email.py)
# Exa
Source: https://docs.phidata.com/tools/exa
**ExaTools** enable an Agent to search the web using Exa.
## Prerequisites
The following examples requires the `exa-client` library and an API key which can be obtained from [Exa](https://exa.ai).
```shell
pip install -U exa-client
```
```shell
export EXA_API_KEY=***
```
## Example
The following agent will run seach exa for AAPL news and print the response.
```python cookbook/tools/exa_tools.py
from phi.agent import Agent
from phi.tools.exa import ExaTools
agent = Agent(tools=[ExaTools(include_domains=["cnbc.com", "reuters.com", "bloomberg.com"])], show_tool_calls=True)
agent.print_response("Search for AAPL news", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ---------------------- | ------ | ------- | ------------------------------------------------------------ |
| `api_key` | `str` | - | API key for authentication purposes. |
| `search` | `bool` | `False` | Determines whether to enable search functionality. |
| `search_with_contents` | `bool` | `True` | Indicates whether to include contents in the search results. |
| `show_results` | `bool` | `False` | Controls whether to display search results directly. |
## Toolkit Functions
| Function | Description |
| -------------------------- | -------------------------------------------------------------------------- |
| `search_exa` | Searches Exa for a query. |
| `search_exa_with_contents` | Searches Exa for a query and returns the contents from the search results. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/exa.py)
# Fal
Source: https://docs.phidata.com/tools/fal
**FalTools** enable an Agent to perform media generation tasks.
## Prerequisites
The following example requires the `fal_client` library and an API key which can be obtained from [Fal](https://fal.ai/).
```shell
pip install -U fal_client
```
```shell
export FAL_KEY=***
```
## Example
The following agent will use FAL to generate any video requested by the user.
```python cookbook/tools/fal_tools.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.fal_tools import FalTools
fal_agent = Agent(
name="Fal Video Generator Agent",
model=OpenAIChat(id="gpt-4o"),
tools=[FalTools("fal-ai/hunyuan-video")],
description="You are an AI agent that can generate videos using the Fal API.",
instructions=[
"When the user asks you to create a video, use the `generate_media` tool to create the video.",
"Return the URL as raw to the user.",
"Don't convert video URL to markdown or anything else.",
],
markdown=True,
debug_mode=True,
show_tool_calls=True,
)
fal_agent.print_response("Generate video of balloon in the ocean")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------- | ----- | ------- | ------------------------------------------ |
| `api_key` | `str` | `None` | API key for authentication purposes. |
| `model` | `str` | `None` | The model to use for the media generation. |
## Toolkit Functions
| Function | Description |
| ---------------- | -------------------------------------------------------------- |
| `generate_media` | Generate either images or videos depending on the user prompt. |
| `image_to_image` | Transform an input image based on a text prompt. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/fal_tools.py)
# File
Source: https://docs.phidata.com/tools/file
**FileTools** enable an Agent to read and write files on the local file system.
## Example
The following agent will generate an answer and save it in a file.
```python cookbook/tools/file_tools.py
from phi.agent import Agent
from phi.tools.file import FileTools
agent = Agent(tools=[FileTools()], show_tool_calls=True)
agent.print_response("What is the most advanced LLM currently? Save the answer to a file.", markdown=True)
```
## Toolkit Params
| Name | Type | Default | Description |
| ------------ | ------ | ------- | -------------------------------------------------------------- |
| `base_dir` | `Path` | - | Specifies the base directory path for file operations. |
| `save_files` | `bool` | `True` | Determines whether files should be saved during the operation. |
| `read_files` | `bool` | `True` | Allows reading from files during the operation. |
| `list_files` | `bool` | `True` | Enables listing of files in the specified directory. |
## Toolkit Functions
| Name | Description |
| ------------ | ---------------------------------------------------------------------------------------- |
| `save_file` | Saves the contents to a file called `file_name` and returns the file name if successful. |
| `read_file` | Reads the contents of the file `file_name` and returns the contents if successful. |
| `list_files` | Returns a list of files in the base directory |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/file.py)
# Firecrawl
Source: https://docs.phidata.com/tools/firecrawl
**FirecrawlTools** enable an Agent to perform web crawling and scraping tasks.
## Prerequisites
The following example requires the `firecrawl-py` library and an API key which can be obtained from [Firecrawl](https://firecrawl.dev).
```shell
pip install -U firecrawl-py
```
```shell
export FIRECRAWL_API_KEY=***
```
## Example
The following agent will scrape the content from [https://finance.yahoo.com/](https://finance.yahoo.com/) and return a summary of the content:
```python cookbook/tools/firecrawl_tools.py
from phi.agent import Agent
from phi.tools.firecrawl import FirecrawlTools
agent = Agent(tools=[FirecrawlTools(scrape=False, crawl=True)], show_tool_calls=True, markdown=True)
agent.print_response("Summarize this https://finance.yahoo.com/")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------- | ----------- | ------- | ------------------------------------------------------------- |
| `api_key` | `str` | `None` | Optional API key for authentication purposes. |
| `formats` | `List[str]` | `None` | Optional list of formats to be used for the operation. |
| `limit` | `int` | `10` | Maximum number of items to retrieve. The default value is 10. |
| `scrape` | `bool` | `True` | Enables the scraping functionality. Default is True. |
| `crawl` | `bool` | `False` | Enables the crawling functionality. Default is False. |
## Toolkit Functions
| Function | Description |
| ---------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `scrape_website` | Scrapes a website using Firecrawl. Parameters include `url` to specify the URL to scrape. The function supports optional formats if specified. Returns the results of the scraping in JSON format. |
| `crawl_website` | Crawls a website using Firecrawl. Parameters include `url` to specify the URL to crawl, and an optional `limit` to define the maximum number of pages to crawl. The function supports optional formats and returns the crawling results in JSON format. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/firecrawl.py)
# Functions
Source: https://docs.phidata.com/tools/functions
Any python function can be used as a tool by an Agent. **We highly recommend** creating functions specific to your workflow and adding them to your Agents.
For example, here's how to use a `get_top_hackernews_stories` function as a tool:
```python hn_agent.py
import json
import httpx
from phi.agent import Agent
def get_top_hackernews_stories(num_stories: int = 10) -> str:
"""Use this function to get top stories from Hacker News.
Args:
num_stories (int): Number of stories to return. Defaults to 10.
Returns:
str: JSON string of top stories.
"""
# Fetch top story IDs
response = httpx.get('https://hacker-news.firebaseio.com/v0/topstories.json')
story_ids = response.json()
# Fetch story details
stories = []
for story_id in story_ids[:num_stories]:
story_response = httpx.get(f'https://hacker-news.firebaseio.com/v0/item/{story_id}.json')
story = story_response.json()
if "text" in story:
story.pop("text", None)
stories.append(story)
return json.dumps(stories)
agent = Agent(tools=[get_top_hackernews_stories], show_tool_calls=True, markdown=True)
agent.print_response("Summarize the top 5 stories on hackernews?", stream=True)
```
# Giphy
Source: https://docs.phidata.com/tools/giphy
**GiphyTools** enables an Agent to search for GIFs on GIPHY.
## Prerequisites
```shell
export GIPHY_API_KEY=***
```
## Example
The following agent will search GIPHY for a GIF appropriate for a birthday message.
```python
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.giphy import GiphyTools
gif_agent = Agent(
name="Gif Generator Agent",
model=OpenAIChat(id="gpt-4o"),
tools=[GiphyTools()],
description="You are an AI agent that can generate gifs using Giphy.",
)
gif_agent.print_response("I want a gif to send to a friend for their birthday.")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------- | ----- | ------- | ------------------------------------------------- |
| `api_key` | `str` | `None` | If you want to manually supply the GIPHY API key. |
| `limit` | `int` | `1` | The number of GIFs to return in a search. |
## Toolkit Functions
| Function | Description |
| ------------- | --------------------------------------------------- |
| `search_gifs` | Searches GIPHY for a GIF based on the query string. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/giphy.py)
# Github
Source: https://docs.phidata.com/tools/github
**GithubTools** enables an Agent to access Github repositories and perform tasks such as listing open pull requests, issues and more.
## Prerequisites
The following examples requires the `PyGithub` library and a Github access token which can be obtained from [here](https://github.com/settings/tokens).
```shell
pip install -U PyGithub
```
```shell
export GITHUB_ACCESS_TOKEN=***
```
## Example
The following agent will search Google for the latest news about "Mistral AI":
```python cookbook/tools/github_tools.py
from phi.agent import Agent
from phi.tools.github import GithubTools
agent = Agent(
instructions=[
"Use your tools to answer questions about the repo: agno-agi/phidata",
"Do not create any issues or pull requests unless explicitly asked to do so",
],
tools=[GithubTools()],
show_tool_calls=True,
)
agent.print_response("List open pull requests", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| -------------------------- | ------ | ------- | ------------------------------------------------------------------------------------------------------------- |
| `access_token` | `str` | `None` | Github access token for authentication. If not provided, will use GITHUB\_ACCESS\_TOKEN environment variable. |
| `base_url` | `str` | `None` | Optional base URL for Github Enterprise installations. |
| `search_repositories` | `bool` | `True` | Enable searching Github repositories. |
| `list_repositories` | `bool` | `True` | Enable listing repositories for a user/organization. |
| `get_repository` | `bool` | `True` | Enable getting repository details. |
| `list_pull_requests` | `bool` | `True` | Enable listing pull requests for a repository. |
| `get_pull_request` | `bool` | `True` | Enable getting pull request details. |
| `get_pull_request_changes` | `bool` | `True` | Enable getting pull request file changes. |
| `create_issue` | `bool` | `True` | Enable creating issues in repositories. |
## Toolkit Functions
| Function | Description |
| -------------------------- | ---------------------------------------------------- |
| `search_repositories` | Searches Github repositories based on a query. |
| `list_repositories` | Lists repositories for a given user or organization. |
| `get_repository` | Gets details about a specific repository. |
| `list_pull_requests` | Lists pull requests for a repository. |
| `get_pull_request` | Gets details about a specific pull request. |
| `get_pull_request_changes` | Gets the file changes in a pull request. |
| `create_issue` | Creates a new issue in a repository. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/github.py)
# Google Calendar
Source: https://docs.phidata.com/tools/googlecalendar
Enable an Agent to work with Google Calendar to view and schedule meetings.
## Prerequisites
### Install dependencies
```shell
pip install tzlocal
```
### Setup Google Project and OAuth
Reference: [https://developers.google.com/calendar/api/quickstart/python](https://developers.google.com/calendar/api/quickstart/python)
1. Enable Google Calender API
* Go to [Google Cloud Console](https://console.cloud.google.com/apis/enableflow?apiid=calendar-json.googleapis.com).
* Select Project and Enable.
2. Go To API & Service -> OAuth Consent Screen
3. Select User Type
* If you are a Google Workspace user, select Internal.
* Otherwise, select External.
4. Fill in the app details (App name, logo, support email, etc).
5. Select Scope
* Click on Add or Remove Scope.
* Search for Google Calender API (Make sure you've enabled Google calender API otherwise scopes wont be visible).
* Select scopes accordingly
* From the dropdown check on `/auth/calendar` scope
* Save and continue.
6. Adding Test User
* Click Add Users and enter the email addresses of the users you want to allow during testing.
* NOTE : Only these users can access the app's OAuth functionality when the app is in "Testing" mode.
Any other users will receive access denied errors.
* To make the app available to all users, you'll need to move the app's status to "In Production".
Before doing so, ensure the app is fully verified by Google if it uses sensitive or restricted scopes.
* Click on Go back to Dashboard.
7. Generate OAuth 2.0 Client ID
* Go to Credentials.
* Click on Create Credentials -> OAuth Client ID
* Select Application Type as Desktop app.
* Download JSON.
8. Using Google Calender Tool
* Pass the path of downloaded credentials as credentials\_path to Google Calender tool.
* Optional: Set the `token_path` parameter to specify where the tool should create the `token.json` file.
* The `token.json` file is used to store the user's access and refresh tokens and is automatically created during the authorization flow if it doesn't already exist.
* If `token_path` is not explicitly provided, the file will be created in the default location which is your current working directory.
* If you choose to specify `token_path`, please ensure that the directory you provide has write access, as the application needs to create or update this file during the authentication process.
## Example
The following agent will use GoogleCalendarTools to find today's events.
```python cookbook/tools/googlecalendar_tools.py
from phi.agent import Agent
from phi.tools.googlecalendar import GoogleCalendarTools
import datetime
import os
from tzlocal import get_localzone_name
agent = Agent(
tools=[GoogleCalendarTools(credentials_path="")],
show_tool_calls=True,
instructions=[
f"""
You are scheduling assistant . Today is {datetime.datetime.now()} and the users timezone is {get_localzone_name()}.
You should help users to perform these actions in their Google calendar:
- get their scheduled events from a certain date and time
- create events based on provided details
"""
],
add_datetime_to_instructions=True,
)
agent.print_response("Give me the list of todays events", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------ | ----- | ------- | ------------------------------------------------------------------------------ |
| `credentials_path` | `str` | `None` | Path of the file credentials.json file which contains OAuth 2.0 Client ID. |
| `token_path` | `str` | `None` | Path of the file token.json which stores the user's access and refresh tokens. |
## Toolkit Functions
| Function | Description |
| -------------- | -------------------------------------------------- |
| `list_events` | List events from the user's primary calendar. |
| `create_event` | Create a new event in the user's primary calendar. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/googlecalendar.py)
# Google Search
Source: https://docs.phidata.com/tools/googlesearch
**GoogleSearch** enables an Agent to perform web crawling and scraping tasks.
## Prerequisites
The following examples requires the `googlesearch` and `pycountry` libraries.
```shell
pip install -U googlesearch-python pycountry
```
## Example
The following agent will search Google for the latest news about "Mistral AI":
```python cookbook/tools/googlesearch_tools.py
from phi.agent import Agent
from phi.tools.googlesearch import GoogleSearch
agent = Agent(
tools=[GoogleSearch()],
description="You are a news agent that helps users find the latest news.",
instructions=[
"Given a topic by the user, respond with 4 latest news items about that topic.",
"Search for 10 news items and select the top 4 unique items.",
"Search in English and in French.",
],
show_tool_calls=True,
debug_mode=True,
)
agent.print_response("Mistral AI", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------- | ----- | ------- | --------------------------------------------------- |
| `fixed_max_results` | `int` | `None` | Optional fixed maximum number of results to return. |
| `fixed_language` | `str` | `None` | Optional fixed language for the requests. |
| `headers` | `Any` | `None` | Optional headers to include in the requests. |
| `proxy` | `str` | `None` | Optional proxy to be used for the requests. |
| `timeout` | `int` | `None` | Optional timeout for the requests, in seconds. |
## Toolkit Functions
| Function | Description |
| --------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `google_search` | Searches Google for a specified query. Parameters include `query` for the search term, `max_results` for the maximum number of results (default is 5), and `language` for the language of the search results (default is "en"). Returns the search results as a JSON formatted string. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/googlesearch.py)
# Hacker News
Source: https://docs.phidata.com/tools/hackernews
**HackerNews** enables an Agent to search Hacker News website.
## Example
The following agent will write an engaging summary of the users with the top 2 stories on hackernews along with the stories.
```python cookbook/tools/hackernews.py
from phi.agent import Agent
from phi.tools.hackernews import HackerNews
agent = Agent(
name="Hackernews Team",
tools=[HackerNews()],
show_tool_calls=True,
markdown=True,
)
agent.print_response(
"Write an engaging summary of the "
"users with the top 2 stories on hackernews. "
"Please mention the stories as well.",
)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------ | ------ | ------- | ------------------------------ |
| `get_top_stories` | `bool` | `True` | Enables fetching top stories. |
| `get_user_details` | `bool` | `True` | Enables fetching user details. |
## Toolkit Functions
| Function | Description |
| ---------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `get_top_hackernews_stories` | Retrieves the top stories from Hacker News. Parameters include `num_stories` to specify the number of stories to return (default is 10). Returns the top stories in JSON format. |
| `get_user_details` | Retrieves the details of a Hacker News user by their username. Parameters include `username` to specify the user. Returns the user details in JSON format. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/hackernews.py)
# Introduction
Source: https://docs.phidata.com/tools/introduction
Tools are **functions** that an Agent can run like searching the web, running SQL, sending an email or calling APIs. Use tools integrate Agents with external systems.
You can use any python function as a tool or use a pre-built **toolkit**. The general syntax is:
```python
from phi.agent import Agent
agent = Agent(
# Add functions or Toolkits
tools=[...],
# Show tool calls in the Agent response
show_tool_calls=True
)
```
Read more about:
* [Available Toolkits](/tools/toolkits)
* [Using functions as tools](/tools/functions)
# Jina Reader
Source: https://docs.phidata.com/tools/jina_reader
**JinaReaderTools** enable an Agent to perform web search tasks using Jina.
## Prerequisites
The following example requires the `jina` library.
```shell
pip install -U jina
```
## Example
The following agent will use Jina API to summarize the content of [https://github.com/phidatahq](https://github.com/phidatahq)
```python cookbook/tools/jinareader_tools.py
from phi.agent import Agent
from phi.tools.jina_tools import JinaReaderTools
agent = Agent(tools=[JinaReaderTools()])
agent.print_response("Summarize: https://github.com/phidatahq")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| -------------------- | ----- | ------- | -------------------------------------------------------------------------- |
| `api_key` | `str` | - | The API key for authentication purposes, retrieved from the configuration. |
| `base_url` | `str` | - | The base URL of the API, retrieved from the configuration. |
| `search_url` | `str` | - | The URL used for search queries, retrieved from the configuration. |
| `max_content_length` | `int` | - | The maximum length of content allowed, retrieved from the configuration. |
## Toolkit Functions
| Function | Description |
| -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `read_url` | Reads the content of a specified URL using Jina Reader API. Parameters include `url` for the URL to read. Returns the truncated content or an error message if the request fails. |
| `search_query` | Performs a web search using Jina Reader API based on a specified query. Parameters include `query` for the search term. Returns the truncated search results or an error message if the request fails. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/jina_tools.py)
# Jira
Source: https://docs.phidata.com/tools/jira
**JiraTools** enable an Agent to perform Jira tasks.
## Prerequisites
The following example requires the `jira` library and auth credentials.
```shell
pip install -U jira
```
```shell
export JIRA_SERVER_URL="YOUR_JIRA_SERVER_URL"
export JIRA_USERNAME="YOUR_USERNAME"
export JIRA_API_TOKEN="YOUR_API_TOKEN"
```
## Example
The following agent will use Jira API to search for issues in a project.
```python cookbook/tools/jira_tools.py
from phi.agent import Agent
from phi.tools.jira_tools import JiraTools
agent = Agent(tools=[JiraTools()])
agent.print_response("Find all issues in project PROJ", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------ | ----- | ------- | ----------------------------------------------------------------------------------------------------------------------------- |
| `server_url` | `str` | `""` | The URL of the JIRA server, retrieved from the environment variable `JIRA_SERVER_URL`. Default is an empty string if not set. |
| `username` | `str` | `None` | The JIRA username for authentication, retrieved from the environment variable `JIRA_USERNAME`. Default is None if not set. |
| `password` | `str` | `None` | The JIRA password for authentication, retrieved from the environment variable `JIRA_PASSWORD`. Default is None if not set. |
| `token` | `str` | `None` | The JIRA API token for authentication, retrieved from the environment variable `JIRA_TOKEN`. Default is None if not set. |
## Toolkit Functions
| Function | Description |
| --------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `get_issue` | Retrieves issue details from JIRA. Parameters include:
- `issue_key`: the key of the issue to retrieve
Returns a JSON string containing issue details or an error message. |
| `create_issue` | Creates a new issue in JIRA. Parameters include:
- `project_key`: the project in which to create the issue
- `summary`: the issue summary
- `description`: the issue description
- `issuetype`: the type of issue (default is "Task")
Returns a JSON string with the new issue's key and URL or an error message. |
| `search_issues` | Searches for issues using a JQL query in JIRA. Parameters include:
- `jql_str`: the JQL query string
- `max_results`: the maximum number of results to return (default is 50)
Returns a JSON string containing a list of dictionaries with issue details or an error message. |
| `add_comment` | Adds a comment to an issue in JIRA. Parameters include:
- `issue_key`: the key of the issue
- `comment`: the comment text
Returns a JSON string indicating success or an error message. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/jira_tools.py)
# Linear
Source: https://docs.phidata.com/tools/linear
**LinearTool** enable an Agent to perform [Linear](https://linear.app/) tasks.
## Prerequisites
```shell
export LINEAR_API_KEY="LINEAR_API_KEY"
```
## Example
The following agent will use Linear API to search for issues in a project for a specific user.
```python cookbook/tools/linear_tools.py
from phi.agent import Agent
from phi.tools.linear_tools import LinearTool
agent = Agent(
name="Linear Tool Agent",
tools=[LinearTool()],
show_tool_calls=True,
markdown=True,
)
agent.print_response("Show all the issues assigned to user id: 12021")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| -------------------------- | ------ | ------- | --------------------------------------- |
| `get_user_details` | `bool` | `True` | Enable `get_user_details` tool. |
| `get_issue_details` | `bool` | `True` | Enable `get_issue_details` tool. |
| `create_issue` | `bool` | `True` | Enable `create_issue` tool. |
| `update_issue` | `bool` | `True` | Enable `update_issue` tool. |
| `get_user_assigned_issues` | `bool` | `True` | Enable `get_user_assigned_issues` tool. |
| `get_workflow_issues` | `bool` | `True` | Enable `get_workflow_issues` tool. |
| `get_high_priority_issues` | `bool` | `True` | Enable `get_high_priority_issues` tool. |
## Toolkit Functions
| Function | Description |
| -------------------------- | ---------------------------------------------------------------- |
| `get_user_details` | Fetch authenticated user details. |
| `get_issue_details` | Retrieve details of a specific issue by issue ID. |
| `create_issue` | Create a new issue within a specific project and team. |
| `update_issue` | Update the title or state of a specific issue by issue ID. |
| `get_user_assigned_issues` | Retrieve issues assigned to a specific user by user ID. |
| `get_workflow_issues` | Retrieve issues within a specific workflow state by workflow ID. |
| `get_high_priority_issues` | Retrieve issues with a high priority (priority `<=` 2). |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/linear_tools.py)
# Lumalabs
Source: https://docs.phidata.com/tools/lumalabs
**LumaLabTools** enables an Agent to generate media using the [Lumalabs platform](https://lumalabs.ai/dream-machine).
## Prerequisites
```shell
export LUMAAI_API_KEY=***
```
The following example requires the `lumaai` library. To install the Lumalabs client, run the following command:
```shell
pip install -U lumaai
```
## Example
The following agent will use Lumalabs to generate any video requested by the user.
```python cookbook/tools/lumalabs_tool.py
from phi.agent import Agent
from phi.llm.openai import OpenAIChat
from phi.tools.lumalab import LumaLabTools
luma_agent = Agent(
name="Luma Video Agent",
llm=OpenAIChat(model="gpt-4o"),
tools=[LumaLabTools()], # Using the LumaLab tool we created
markdown=True,
debug_mode=True,
show_tool_calls=True,
instructions=[
"You are an agent designed to generate videos using the Luma AI API.",
"You can generate videos in two ways:",
"1. Text-to-Video Generation:",
"2. Image-to-Video Generation:",
"Choose the appropriate function based on whether the user provides image URLs or just a text prompt.",
"The video will be displayed in the UI automatically below your response, so you don't need to show the video URL in your response.",
],
system_message=(
"Use generate_video for text-to-video requests and image_to_video for image-based "
"generation. Don't modify default parameters unless specifically requested. "
"Always provide clear feedback about the video generation status."
),
)
luma_agent.run("Generate a video of a car in a sky")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------- | ----- | ------- | ---------------------------------------------------- |
| `api_key` | `str` | `None` | If you want to manually supply the Lumalabs API key. |
## Toolkit Functions
| Function | Description |
| ---------------- | --------------------------------------------------------------------- |
| `generate_video` | Generate a video from a prompt. |
| `image_to_video` | Generate a video from a prompt, a starting image and an ending image. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/lumalab.py)
# MLX Transcribe
Source: https://docs.phidata.com/tools/mlx_transcribe
**MLX Transcribe** is a tool for transcribing audio files using MLX Whisper.
## Prerequisites
1. **Install ffmpeg**
* macOS: `brew install ffmpeg`
* Ubuntu: `sudo apt-get install ffmpeg`
* Windows: Download from [https://ffmpeg.org/download.html](https://ffmpeg.org/download.html)
2. **Install mlx-whisper library**
```shell
pip install mlx-whisper
```
3. **Prepare audio files**
* Create a 'storage/audio' directory
* Place your audio files in this directory
* Supported formats: mp3, mp4, wav, etc.
4. **Download sample audio** (optional)
* Visit: [https://www.ted.com/talks/reid\_hoffman\_and\_kevin\_scott\_the\_evolution\_of\_ai\_and\_how\_it\_will\_impact\_human\_creativity](https://www.ted.com/talks/reid_hoffman_and_kevin_scott_the_evolution_of_ai_and_how_it_will_impact_human_creativity)
* Save the audio file to 'storage/audio' directory
## Example
The following agent will use MLX Transcribe to transcribe audio files.
```python cookbook/tools/mlx_transcribe_tools.py
from pathlib import Path
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.mlx_transcribe import MLXTranscribe
# Get audio files from storage/audio directory
phidata_root_dir = Path(__file__).parent.parent.parent.resolve()
audio_storage_dir = phidata_root_dir.joinpath("storage/audio")
if not audio_storage_dir.exists():
audio_storage_dir.mkdir(exist_ok=True, parents=True)
agent = Agent(
name="Transcription Agent",
model=OpenAIChat(id="gpt-4o"),
tools=[MLXTranscribe(base_dir=audio_storage_dir)],
instructions=[
"To transcribe an audio file, use the `transcribe` tool with the name of the audio file as the argument.",
"You can find all available audio files using the `read_files` tool.",
],
markdown=True,
)
agent.print_response("Summarize the reid hoffman ted talk, split into sections", stream=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------------------------------- | ------------------------------ | ---------------------------------------- | -------------------------------------------- |
| `base_dir` | `Path` | `Path.cwd()` | Base directory for audio files |
| `read_files_in_base_dir` | `bool` | `True` | Whether to register the read\_files function |
| `path_or_hf_repo` | `str` | `"mlx-community/whisper-large-v3-turbo"` | Path or HuggingFace repo for the model |
| `verbose` | `bool` | `None` | Enable verbose output |
| `temperature` | `float` or `Tuple[float, ...]` | `None` | Temperature for sampling |
| `compression_ratio_threshold` | `float` | `None` | Compression ratio threshold |
| `logprob_threshold` | `float` | `None` | Log probability threshold |
| `no_speech_threshold` | `float` | `None` | No speech threshold |
| `condition_on_previous_text` | `bool` | `None` | Whether to condition on previous text |
| `initial_prompt` | `str` | `None` | Initial prompt for transcription |
| `word_timestamps` | `bool` | `None` | Enable word-level timestamps |
| `prepend_punctuations` | `str` | `None` | Punctuations to prepend |
| `append_punctuations` | `str` | `None` | Punctuations to append |
| `clip_timestamps` | `str` or `List[float]` | `None` | Clip timestamps |
| `hallucination_silence_threshold` | `float` | `None` | Hallucination silence threshold |
| `decode_options` | `dict` | `None` | Additional decoding options |
## Toolkit Functions
| Function | Description |
| ------------ | ------------------------------------------- |
| `transcribe` | Transcribes an audio file using MLX Whisper |
| `read_files` | Lists all audio files in the base directory |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/mlx_transcribe.py)
# ModelsLabs
Source: https://docs.phidata.com/tools/models_labs
## Prerequisites
You need to install the `requests` library.
```bash
pip install requests
```
Set the `MODELS_LAB_API_KEY` environment variable.
```bash
export MODELS_LAB_API_KEY=****
```
## Example
The following agent will use ModelsLabs to generate a video based on a text prompt.
```python cookbook/tools/models_labs_tools.py
from phi.agent import Agent
from phi.tools.models_labs import ModelsLabs
# Create an Agent with the ModelsLabs tool
agent = Agent(tools=[ModelsLabs()], name="ModelsLabs Agent")
agent.print_response("Generate a video of a beautiful sunset over the ocean", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------------------- | ------ | ------------------------------------------------- | -------------------------------------------------------------------------- |
| `api_key` | `str` | `None` | The ModelsLab API key for authentication |
| `url` | `str` | `"https://modelslab.com/api/v6/video/text2video"` | The API endpoint URL |
| `fetch_url` | `str` | `https://modelslab.com/api/v6/video/fetch` | The URL to fetch the video status from |
| `wait_for_completion` | `bool` | `False` | Whether to wait for the video to be ready |
| `add_to_eta` | `int` | `15` | Time to add to the ETA to account for the time it takes to fetch the video |
| `max_wait_time` | `int` | `60` | Maximum time to wait for the video to be ready |
| `file_type` | `str` | `"mp4"` | The type of file to generate |
## Toolkit Functions
| Function | Description |
| ---------------- | ----------------------------------------------- |
| `generate_media` | Generates a video or gif based on a text prompt |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/models_labs.py)
# Newspaper
Source: https://docs.phidata.com/tools/newspaper
**NewspaperTools** enable an Agent to read news articles using the Newspaper4k library.
## Prerequisites
The following example requires the `newspaper3k` library.
```shell
pip install -U newspaper3k
```
## Example
The following agent will summarize the wikipedia article on language models.
```python cookbook/tools/newspaper_tools.py
from phi.agent import Agent
from phi.tools.newspaper_tools import NewspaperTools
agent = Agent(tools=[NewspaperTools()])
agent.print_response("Please summarize https://en.wikipedia.org/wiki/Language_model")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------ | ------ | ------- | ------------------------------------------------------------- |
| `get_article_text` | `bool` | `True` | Enables the functionality to retrieve the text of an article. |
## Toolkit Functions
| Function | Description |
| ------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `get_article_text` | Retrieves the text of an article from a specified URL. Parameters include `url` for the URL of the article. Returns the text of the article or an error message if the retrieval fails. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/newspaper_tools.py)
# Newspaper4k
Source: https://docs.phidata.com/tools/newspaper4k
**Newspaper4k** enables an Agent to read news articles using the Newspaper4k library.
## Prerequisites
The following example requires the `newspaper4k` and `lxml_html_clean` libraries.
```shell
pip install -U newspaper4k lxml_html_clean
```
## Example
The following agent will summarize the article: [https://www.rockymountaineer.com/blog/experience-icefields-parkway-scenic-drive-lifetime](https://www.rockymountaineer.com/blog/experience-icefields-parkway-scenic-drive-lifetime).
```python cookbook/tools/newspaper4k_tools.py
from phi.agent import Agent
from phi.tools.newspaper4k import Newspaper4k
agent = Agent(tools=[Newspaper4k()], debug_mode=True, show_tool_calls=True)
agent.print_response("Please summarize https://www.rockymountaineer.com/blog/experience-icefields-parkway-scenic-drive-lifetime")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ----------------- | ------ | ------- | ---------------------------------------------------------------------------------- |
| `read_article` | `bool` | `True` | Enables the functionality to read the full content of an article. |
| `include_summary` | `bool` | `False` | Specifies whether to include a summary of the article along with the full content. |
| `article_length` | `int` | - | The maximum length of the article or its summary to be processed or returned. |
## Toolkit Functions
| Function | Description |
| ------------------ | ------------------------------------------------------------ |
| `get_article_data` | This function reads the full content and data of an article. |
| `read_article` | This function reads the full content of an article. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/newspaper4k.py)
# OpenBB
Source: https://docs.phidata.com/tools/openbb
**OpenBBTools** enable an Agent to provide information about stocks and companies.
```python cookbook/tools/openbb_tools.py
from phi.agent import Agent
from phi.tools.openbb_tools import OpenBBTools
agent = Agent(tools=[OpenBBTools()], debug_mode=True, show_tool_calls=True)
# Example usage showing stock analysis
agent.print_response(
"Get me the current stock price and key information for Apple (AAPL)"
)
# Example showing market analysis
agent.print_response(
"What are the top gainers in the market today?"
)
# Example showing economic indicators
agent.print_response(
"Show me the latest GDP growth rate and inflation numbers for the US"
)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ----------------- | ------ | ------- | ---------------------------------------------------------------------------------- |
| `read_article` | `bool` | `True` | Enables the functionality to read the full content of an article. |
| `include_summary` | `bool` | `False` | Specifies whether to include a summary of the article along with the full content. |
| `article_length` | `int` | - | The maximum length of the article or its summary to be processed or returned. |
## Toolkit Functions
| Function | Description |
| ----------------------- | --------------------------------------------------------------------------------- |
| `get_stock_price` | This function gets the current stock price for a stock symbol or list of symbols. |
| `search_company_symbol` | This function searches for the stock symbol of a company. |
| `get_price_targets` | This function gets the price targets for a stock symbol or list of symbols. |
| `get_company_news` | This function gets the latest news for a stock symbol or list of symbols. |
| `get_company_profile` | This function gets the company profile for a stock symbol or list of symbols. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/openbb_tools.py)
# Pandas
Source: https://docs.phidata.com/tools/pandas
**PandasTools** enable an Agent to perform data manipulation tasks using the Pandas library.
```python cookbook/tools/pandas_tool.py
from phi.agent import Agent
from phi.tools.pandas import PandasTools
# Create an agent with PandasTools
agent = Agent(tools=[PandasTools()])
# Example: Create a dataframe with sample data and get the first 5 rows
agent.print_response("""
Please perform these tasks:
1. Create a pandas dataframe named 'sales_data' using DataFrame() with this sample data:
{'date': ['2023-01-01', '2023-01-02', '2023-01-03', '2023-01-04', '2023-01-05'],
'product': ['Widget A', 'Widget B', 'Widget A', 'Widget C', 'Widget B'],
'quantity': [10, 15, 8, 12, 20],
'price': [9.99, 15.99, 9.99, 12.99, 15.99]}
2. Show me the first 5 rows of the sales_data dataframe
""")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------------- | ------------------------- | ------- | -------------------------------------------------------------- |
| `dataframes` | `Dict[str, pd.DataFrame]` | `{}` | A dictionary to store Pandas DataFrames, keyed by their names. |
| `create_pandas_dataframe` | `function` | - | Registers a function to create a Pandas DataFrame. |
| `run_dataframe_operation` | `function` | - | Registers a function to run operations on a Pandas DataFrame. |
## Toolkit Functions
| Function | Description |
| ------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `create_pandas_dataframe` | Creates a Pandas DataFrame named `dataframe_name` by using the specified function `create_using_function` with parameters `function_parameters`. Parameters include 'dataframe\_name' for the name of the DataFrame, 'create\_using\_function' for the function to create it (e.g., 'read\_csv'), and 'function\_parameters' for the arguments required by the function. Returns the name of the created DataFrame if successful, otherwise returns an error message. |
| `run_dataframe_operation` | Runs a specified operation `operation` on a DataFrame `dataframe_name` with the parameters `operation_parameters`. Parameters include 'dataframe\_name' for the DataFrame to operate on, 'operation' for the operation to perform (e.g., 'head', 'tail'), and 'operation\_parameters' for the arguments required by the operation. Returns the result of the operation if successful, otherwise returns an error message. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/pandas.py)
# Phi
Source: https://docs.phidata.com/tools/phi
## Example
The following agent will use the Phi toolkit to create and manage phidata workspaces. It can create new applications from templates like llm-app, api-app, django-app, and streamlit-app. It can also start existing workspaces and validate that Phi is ready to run commands.
```python cookbook/tools/phi_tools.py
from phi.agent import Agent
from phi.tools.phi import PhiTools
# Create an Agent with the Phi tool
agent = Agent(tools=[PhiTools()], name="Phi Workspace Manager")
# Example 1: Create a new agent app
agent.print_response("Create a new agent-app called agent-app-turing", markdown=True)
# Example 3: Start a workspace
agent.print_response("Start the workspace agent-app-turing", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------- | ----- | ------------- | -------------------- |
| `name` | `str` | `"phi_tools"` | The name of the tool |
## Toolkit Functions
| Function | Description |
| ----------------------- | ---------------------------------------------------------------- |
| `validate_phi_is_ready` | Validates that Phi is ready to run commands |
| `create_new_app` | Creates a new phidata workspace for a given application template |
| `start_user_workspace` | Starts the workspace for a user |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/phi.py)
# Postgres
Source: https://docs.phidata.com/tools/postgres
**PostgresTools** enable an Agent to interact with a PostgreSQL database.
## Prerequisites
The following example requires the `psycopg2` library.
```shell
pip install -U psycopg2
```
You will also need a database. The following example uses a Postgres database running in a Docker container.
```shell
docker run -d \
-e POSTGRES_DB=ai \
-e POSTGRES_USER=ai \
-e POSTGRES_PASSWORD=ai \
-e PGDATA=/var/lib/postgresql/data/pgdata \
-v pgvolume:/var/lib/postgresql/data \
-p 5532:5432 \
--name pgvector \
phidata/pgvector:16
```
## Example
The following agent will list all tables in the database.
```python cookbook/tools/postgres.py
from phi.agent import Agent
from phi.tools.postgres import PostgresTools
# Initialize PostgresTools with connection details
postgres_tools = PostgresTools(
host="localhost",
port=5532,
db_name="ai",
user="ai",
password="ai"
)
# Create an agent with the PostgresTools
agent = Agent(tools=[postgres_tools])
# Example: Ask the agent to run a SQL query
agent.print_response("""
Please run a SQL query to get all users from the users table
who signed up in the last 30 days
""")
```
## Toolkit Params
| Name | Type | Default | Description |
| ------------------ | -------------------------------- | ------- | ------------------------------------------------ |
| `connection` | `psycopg2.extensions.connection` | `None` | Optional database connection object. |
| `db_name` | `str` | `None` | Optional name of the database to connect to. |
| `user` | `str` | `None` | Optional username for database authentication. |
| `password` | `str` | `None` | Optional password for database authentication. |
| `host` | `str` | `None` | Optional host for the database connection. |
| `port` | `int` | `None` | Optional port for the database connection. |
| `run_queries` | `bool` | `True` | Enables running SQL queries. |
| `inspect_queries` | `bool` | `False` | Enables inspecting SQL queries before execution. |
| `summarize_tables` | `bool` | `True` | Enables summarizing table structures. |
| `export_tables` | `bool` | `False` | Enables exporting tables from the database. |
## Toolkit Functions
| Function | Description |
| ---------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `show_tables` | Retrieves and displays a list of tables in the database. Returns the list of tables. |
| `describe_table` | Describes the structure of a specified table by returning its columns, data types, and maximum character length. Parameters include 'table' to specify the table name. Returns the table description. |
| `summarize_table` | Summarizes a table by computing aggregates such as min, max, average, standard deviation, and non-null counts for numeric columns. Parameters include 'table' to specify the table name, and an optional 'table\_schema' to specify the schema (default is "public"). Returns the summary of the table. |
| `inspect_query` | Inspects an SQL query by returning the query plan. Parameters include 'query' to specify the SQL query. Returns the query plan. |
| `export_table_to_path` | Exports a specified table in CSV format to a given path. Parameters include 'table' to specify the table name and an optional 'path' to specify where to save the file (default is the current directory). Returns the result of the export operation. |
| `run_query` | Executes an SQL query and returns the result. Parameters include 'query' to specify the SQL query. Returns the result of the query execution. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/postgres.py)
# Pubmed
Source: https://docs.phidata.com/tools/pubmed
**PubmedTools** enable an Agent to search for Pubmed for articles.
## Example
The following agent will search Pubmed for articles related to "ulcerative colitis".
```python cookbook/tools/pubmed.py
from phi.agent import Agent
from phi.tools.pubmed import PubmedTools
agent = Agent(tools=[PubmedTools()], show_tool_calls=True)
agent.print_response("Tell me about ulcerative colitis.")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------- | ----- | -------------------------- | ---------------------------------------------------------------------- |
| `email` | `str` | `"your_email@example.com"` | Specifies the email address to use. |
| `max_results` | `int` | `None` | Optional parameter to specify the maximum number of results to return. |
## Toolkit Functions
| Function | Description |
| --------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `search_pubmed` | Searches PubMed for articles based on a specified query. Parameters include `query` for the search term and `max_results` for the maximum number of results to return (default is 10). Returns a JSON string containing the search results, including publication date, title, and summary. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/pubmed.py)
# Python
Source: https://docs.phidata.com/tools/python
**PythonTools** enable an Agent to write and run python code.
## Example
The following agent will write a python script that creates the fibonacci series, save it to a file, run it and return the result.
```python cookbook/tools/python_tools.py
from phi.agent import Agent
from phi.tools.python import PythonTools
agent = Agent(tools=[PythonTools()], show_tool_calls=True)
agent.print_response("Write a python script for fibonacci series and display the result till the 10th number")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| -------------- | ------ | ------- | ------------------------------------------------------------------------------------------------------- |
| `base_dir` | `Path` | `None` | Specifies the base directory for operations. Default is None, indicating the current working directory. |
| `save_and_run` | `bool` | `True` | If True, saves and runs the code. Useful for execution of scripts after saving. |
| `pip_install` | `bool` | `False` | Enables pip installation of required packages before running the code. |
| `run_code` | `bool` | `False` | Determines whether the code should be executed. |
| `list_files` | `bool` | `False` | If True, lists all files in the specified base directory. |
| `run_files` | `bool` | `False` | If True, runs the Python files found in the specified directory. |
| `read_files` | `bool` | `False` | If True, reads the contents of the files in the specified directory. |
| `safe_globals` | `dict` | - | Specifies a dictionary of global variables that are considered safe to use during the execution. |
| `safe_locals` | `dict` | - | Specifies a dictionary of local variables that are considered safe to use during the execution. |
## Toolkit Functions
| Function | Description |
| --------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `save_to_file_and_run` | This function saves Python code to a file called `file_name` and then runs it. If successful, returns the value of `variable_to_return` if provided otherwise returns a success message. If failed, returns an error message. Make sure the file\_name ends with `.py` |
| `run_python_file_return_variable` | This function runs code in a Python file. If successful, returns the value of `variable_to_return` if provided otherwise returns a success message. If failed, returns an error message. |
| `read_file` | Reads the contents of the file `file_name` and returns the contents if successful. |
| `list_files` | Returns a list of files in the base directory |
| `run_python_code` | This function runs Python code in the current environment. If successful, returns the value of `variable_to_return` if provided otherwise returns a success message. If failed, returns an error message. |
| `pip_install_package` | This function installs a package using pip in the current environment. If successful, returns a success message. If failed, returns an error message. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/python.py)
# Replicate
Source: https://docs.phidata.com/tools/replicate
**ReplicateTools** enables an Agent to generate media using the [Replicate platform](https://replicate.com/).
## Prerequisites
```shell
export REPLICATE_API_TOKEN=***
```
The following example requires the `replicate` library. To install the Replicate client, run the following command:
```shell
pip install -U replicate
```
## Example
The following agent will use Replicate to generate images or videos requested by the user.
```python cookbook/tools/replicate_tool.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.replicate import ReplicateTools
"""Create an agent specialized for Replicate AI content generation"""
image_agent = Agent(
name="Image Generator Agent",
model=OpenAIChat(id="gpt-4o"),
tools=[ReplicateTools(model="luma/photon-flash")],
description="You are an AI agent that can generate images using the Replicate API.",
instructions=[
"When the user asks you to create an image, use the `generate_media` tool to create the image.",
"Return the URL as raw to the user.",
"Don't convert image URL to markdown or anything else.",
],
markdown=True,
debug_mode=True,
show_tool_calls=True,
)
image_agent.print_response("Generate an image of a horse in the dessert.")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------- | ----- | ------------------ | -------------------------------------------------------------------- |
| `api_key` | `str` | `None` | If you want to manually supply the Replicate API key. |
| `model` | `str` | `minimax/video-01` | The replicate model to use. Find out more on the Replicate platform. |
## Toolkit Functions
| Function | Description |
| ---------------- | ----------------------------------------------------------------------------------- |
| `generate_media` | Generate either an image or a video from a prompt. The output depends on the model. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/replicate.py)
# Resend
Source: https://docs.phidata.com/tools/resend
**ResendTools** enable an Agent to send emails using Resend
## Prerequisites
The following example requires the `resend` library and an API key from [Resend](https://resend.com/).
```shell
pip install -U resend
```
```shell
export RESEND_API_KEY=***
```
## Example
The following agent will send an email using Resend
```python cookbook/tools/resend_tools.py
from phi.agent import Agent
from phi.tools.resend_tools import ResendTools
from_email = ""
to_email = ""
agent = Agent(tools=[ResendTools(from_email=from_email)], show_tool_calls=True)
agent.print_response(f"Send an email to {to_email} greeting them with hello world")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------ | ----- | ------- | ------------------------------------------------------------- |
| `api_key` | `str` | - | API key for authentication purposes. |
| `from_email` | `str` | - | The email address used as the sender in email communications. |
## Toolkit Functions
| Function | Description |
| ------------ | ----------------------------------- |
| `send_email` | Send an email using the Resend API. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/resend_tools.py)
# Searxng
Source: https://docs.phidata.com/tools/searxng
## Example
**Searxng** enables an Agent to search the web for a query, scrape a website, or crawl a website.
```python cookbook/tools/searxng_tools.py
from phi.agent import Agent
from phi.tools.searxng import Searxng
# Initialize Searxng with your Searxng instance URL
searxng = Searxng(
host="http://localhost:53153",
engines=[],
fixed_max_results=5,
news=True,
science=True
)
# Create an agent with Searxng
agent = Agent(tools=[searxng])
# Example: Ask the agent to search using Searxng
agent.print_response("""
Please search for information about artificial intelligence
and summarize the key points from the top results
""")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------------- | ----------- | ------- | ------------------------------------------------------------------ |
| `host` | `str` | - | The host for the connection. |
| `engines` | `List[str]` | `[]` | A list of search engines to use. |
| `fixed_max_results` | `int` | `None` | Optional parameter to specify the fixed maximum number of results. |
| `images` | `bool` | `False` | Enables searching for images. |
| `it` | `bool` | `False` | Enables searching for IT-related content. |
| `map` | `bool` | `False` | Enables searching for maps. |
| `music` | `bool` | `False` | Enables searching for music. |
| `news` | `bool` | `False` | Enables searching for news. |
| `science` | `bool` | `False` | Enables searching for science-related content. |
| `videos` | `bool` | `False` | Enables searching for videos. |
## Toolkit Functions
| Function | Description |
| ---------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `search` | Performs a general web search using the specified query. Parameters include `query` for the search term and `max_results` for the maximum number of results (default is 5). Returns the search results. |
| `image_search` | Performs an image search using the specified query. Parameters include `query` for the search term and `max_results` for the maximum number of results (default is 5). Returns the image search results. |
| `it_search` | Performs a search for IT-related information using the specified query. Parameters include `query` for the search term and `max_results` for the maximum number of results (default is 5). Returns the IT-related search results. |
| `map_search` | Performs a search for maps using the specified query. Parameters include `query` for the search term and `max_results` for the maximum number of results (default is 5). Returns the map search results. |
| `music_search` | Performs a search for music-related information using the specified query. Parameters include `query` for the search term and `max_results` for the maximum number of results (default is 5). Returns the music search results. |
| `news_search` | Performs a search for news using the specified query. Parameters include `query` for the search term and `max_results` for the maximum number of results (default is 5). Returns the news search results. |
| `science_search` | Performs a search for science-related information using the specified query. Parameters include `query` for the search term and `max_results` for the maximum number of results (default is 5). Returns the science search results. |
| `video_search` | Performs a search for videos using the specified query. Parameters include `query` for the search term and `max_results` for the maximum number of results (default is 5). Returns the video search results. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/searxng.py)
# Serpapi
Source: https://docs.phidata.com/tools/serpapi
**SerpApiTools** enable an Agent to search Google and YouTube for a query.
## Prerequisites
The following example requires the `google-search-results` library and an API key from [SerpApi](https://serpapi.com/).
```shell
pip install -U google-search-results
```
```shell
export SERPAPI_API_KEY=***
```
## Example
The following agent will search Google for the query: "Whats happening in the USA" and share results.
```python cookbook/tools/serpapi_tools.py
from phi.agent import Agent
from phi.tools.serpapi_tools import SerpApiTools
agent = Agent(tools=[SerpApiTools()])
agent.print_response("Whats happening in the USA?", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ---------------- | ------ | ------- | ----------------------------------------------------------- |
| `api_key` | `str` | - | API key for authentication purposes. |
| `search_youtube` | `bool` | `False` | Enables the functionality to search for content on YouTube. |
## Toolkit Functions
| Function | Description |
| ---------------- | ------------------------------------------ |
| `search_google` | This function searches Google for a query. |
| `search_youtube` | Searches YouTube for a query. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/serpapi_tools.py)
# Shell
Source: https://docs.phidata.com/tools/shell
**ShellTools** enable an Agent to interact with the shell to run commands.
## Example
The following agent will run a shell command and show contents of the current directory.
Mention your OS to the agent to make sure it runs the correct command.
```python cookbook/tools/shell_tools.py
from phi.agent import Agent
from phi.tools.shell import ShellTools
agent = Agent(tools=[ShellTools()], show_tool_calls=True)
agent.print_response("Show me the contents of the current directory", markdown=True)
```
## Functions in Toolkit
| Function | Description |
| ------------------- | ----------------------------------------------------- |
| `run_shell_command` | Runs a shell command and returns the output or error. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/shell.py)
# Slack
Source: https://docs.phidata.com/tools/slack
## Prerequisites
The following example requires the `slack-sdk` library.
```shell
pip install openai slack-sdk
```
Get a Slack token from [here](https://api.slack.com/tutorials/tracks/getting-a-token).
```shell
export SLACK_TOKEN=***
```
## Example
The following agent will use Slack to send a message to a channel, list all channels, and get the message history of a specific channel.
```python cookbook/tools/slack_tools.py
import os
from phi.agent import Agent
from phi.tools.slack import SlackTools
slack_tools = SlackTools()
agent = Agent(tools=[slack_tools], show_tool_calls=True)
# Example 1: Send a message to a Slack channel
agent.print_response("Send a message 'Hello from Phi!' to the channel #general", markdown=True)
# Example 2: List all channels in the Slack workspace
agent.print_response("List all channels in our Slack workspace", markdown=True)
# Example 3: Get the message history of a specific channel by channel ID
agent.print_response("Get the last 10 messages from the channel 1231241", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------------------- | ------ | ------- | ------------------------------------------------------------------- |
| `token` | `str` | - | Slack API token for authentication |
| `send_message` | `bool` | `True` | Enables the functionality to send messages to Slack channels |
| `list_channels` | `bool` | `True` | Enables the functionality to list available Slack channels |
| `get_channel_history` | `bool` | `True` | Enables the functionality to retrieve message history from channels |
## Toolkit Functions
| Function | Description |
| --------------------- | --------------------------------------------------- |
| `send_message` | Sends a message to a specified Slack channel |
| `list_channels` | Lists all available channels in the Slack workspace |
| `get_channel_history` | Retrieves message history from a specified channel |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/slack.py)
# Sleep
Source: https://docs.phidata.com/tools/sleep
## Example
The following agent will use the `sleep` tool to pause execution for a given number of seconds.
```python cookbook/tools/sleep_tools.py
from phi.agent import Agent
from phi.tools.sleep import Sleep
# Create an Agent with the Sleep tool
agent = Agent(tools=[Sleep()], name="Sleep Agent")
# Example 1: Sleep for 2 seconds
agent.print_response("Sleep for 2 seconds")
# Example 2: Sleep for a longer duration
agent.print_response("Sleep for 5 seconds")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------- | ----- | --------- | -------------------- |
| `name` | `str` | `"sleep"` | The name of the tool |
## Toolkit Functions
| Function | Description |
| -------- | -------------------------------------------------- |
| `sleep` | Pauses execution for a specified number of seconds |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/sleep.py)
# Spider
Source: https://docs.phidata.com/tools/spider
**SpiderTools** is an open source web Scraper & Crawler that returns LLM-ready data. To start using Spider, you need an API key from the [Spider dashboard](https://spider.cloud).
## Prerequisites
The following example requires the `spider-client` library.
```shell
pip install -U spider-client
```
## Example
The following agent will run a search query to get the latest news in USA and scrape the first search result. The agent will return the scraped data in markdown format.
```python cookbook/tools/spider_tools.py
from phi.agent import Agent
from phi.tools.spider import SpiderTools
agent = Agent(tools=[SpiderTools()])
agent.print_response('Can you scrape the first search result from a search on "news in USA"?', markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ------------- | ----- | ------- | ---------------------------------------------- |
| `max_results` | `int` | - | The maximum number of search results to return |
| `url` | `str` | - | The url to be scraped or crawled |
## Toolkit Functions
| Function | Description |
| -------- | ------------------------------------- |
| `search` | Searches the web for the given query. |
| `scrape` | Scrapes the given url. |
| `crawl` | Crawls the given url. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/spider.py)
# SQL
Source: https://docs.phidata.com/tools/sql
**SQLTools** enable an Agent to run SQL queries and interact with databases.
## Prerequisites
The following example requires the `sqlalchemy` library and a database URL.
```shell
pip install -U sqlalchemy
```
You will also need a database. The following example uses a Postgres database running in a Docker container.
```shell
docker run -d \
-e POSTGRES_DB=ai \
-e POSTGRES_USER=ai \
-e POSTGRES_PASSWORD=ai \
-e PGDATA=/var/lib/postgresql/data/pgdata \
-v pgvolume:/var/lib/postgresql/data \
-p 5532:5432 \
--name pgvector \
phidata/pgvector:16
```
## Example
The following agent will run a SQL query to list all tables in the database and describe the contents of one of the tables.
```python cookbook/tools/sql_tools.py
from phi.agent import Agent
from phi.tools.sql import SQLTools
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
agent = Agent(tools=[SQLTools(db_url=db_url)])
agent.print_response("List the tables in the database. Tell me about contents of one of the tables", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ---------------- | ---------------- | ------- | --------------------------------------------------------------------------- |
| `db_url` | `str` | - | The URL for connecting to the database. |
| `db_engine` | `Engine` | - | The database engine used for connections and operations. |
| `user` | `str` | - | The username for database authentication. |
| `password` | `str` | - | The password for database authentication. |
| `host` | `str` | - | The hostname or IP address of the database server. |
| `port` | `int` | - | The port number on which the database server is listening. |
| `schema` | `str` | - | The specific schema within the database to use. |
| `dialect` | `str` | - | The SQL dialect used by the database. |
| `tables` | `Dict[str, Any]` | - | A dictionary mapping table names to their respective metadata or structure. |
| `list_tables` | `bool` | `True` | Enables the functionality to list all tables in the database. |
| `describe_table` | `bool` | `True` | Enables the functionality to describe the schema of a specific table. |
| `run_sql_query` | `bool` | `True` | Enables the functionality to execute SQL queries directly. |
## Toolkit Functions
| Function | Description |
| ---------------- | ----------------------------------------- |
| `list_tables` | Lists all tables in the database. |
| `describe_table` | Describes the schema of a specific table. |
| `run_sql_query` | Executes SQL queries directly. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/sql.py)
# Tavily
Source: https://docs.phidata.com/tools/tavily
**TavilyTools** enable an Agent to search the web using the Tavily API.
## Prerequisites
The following examples requires the `tavily-python` library and an API key from [Tavily](https://tavily.com/).
```shell
pip install -U tavily-python
```
```shell
export TAVILY_API_KEY=***
```
## Example
The following agent will run a search on Tavily for "language models" and print the response.
```python cookbook/tools/tavily_tools.py
from phi.agent import Agent
from phi.tools.tavily import TavilyTools
agent = Agent(tools=[TavilyTools()], show_tool_calls=True)
agent.print_response("Search tavily for 'language models'", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| -------------------- | ------------------------------ | ------------ | ---------------------------------------------------------------------------------------------- |
| `api_key` | `str` | - | API key for authentication. If not provided, will check TAVILY\_API\_KEY environment variable. |
| `search` | `bool` | `True` | Enables search functionality. |
| `max_tokens` | `int` | `6000` | Maximum number of tokens to use in search results. |
| `include_answer` | `bool` | `True` | Whether to include an AI-generated answer summary in the response. |
| `search_depth` | `Literal['basic', 'advanced']` | `'advanced'` | Depth of search - 'basic' for faster results or 'advanced' for more comprehensive search. |
| `format` | `Literal['json', 'markdown']` | `'markdown'` | Output format - 'json' for raw data or 'markdown' for formatted text. |
| `use_search_context` | `bool` | `False` | Whether to use Tavily's search context API instead of regular search. |
## Toolkit Functions
| Function | Description |
| ------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `web_search_using_tavily` | Searches the web for a query using Tavily API. Takes a query string and optional max\_results parameter (default 5). Returns results in specified format with titles, URLs, content and relevance scores. |
| `web_search_with_tavily` | Alternative search function that uses Tavily's search context API. Takes a query string and returns contextualized search results. Only available if use\_search\_context is True. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/tavily.py)
# Toolkits
Source: https://docs.phidata.com/tools/toolkits
A **Toolkit** is a collection of functions that can be added to an Agent. The functions in a Toolkit are designed to work together, share internal state and provide a better development experience.
The following **Toolkits** are available to use
Tools to use Apify Actors.
Tools to read arXiv papers.
Tools to perform calculations.
Tools to interact with the Cal.com API.
Tools to compose complex workflows.
Tools to crawl web data.
Tools to work with CSV files.
Tools to run SQL using DuckDb.
Tools to search the web using DuckDuckGo.
Tools to interact with Dalle.
Tools to send emails.
Tools to search the web using Exa.
Tools to read and write files.
Tools to crawl the web using Firecrawl.
Tools to interact with GitHub.
Tools to search Google.
Tools to read Hacker News articles.
Tools for neural search and AI services using Jina.
Tools to interact with Jira.
Tools to transcribe audio using MLX.
Tools to generate videos using ModelsLabs.
Tools to read news articles.
Tools to read articles using Newspaper4k.
Tools to search for stock data using OpenBB.
Tools to manipulate data using Pandas.
Tools to interact with PostgreSQL databases.
Tools to search Pubmed.
Tools to write and run Python code.
Tools to send emails using Resend.
Tools to search the web using SearxNG.
Tools to search Google, YouTube, and more using Serpapi.
Tools to interact with Slack.
Tools to run shell commands.
Tools to pause execution for a given number of seconds.
Tools to crawl websites.
Tools to run SQL queries.
Tools to interact with Twitter.
Tools to search the web using Tavily.
Tools to scrape websites.
Tools to search Wikipedia.
Tools to search YouTube.
Tools to search Zendesk.
# Twitter
Source: https://docs.phidata.com/tools/twitter
## Prerequisites
The following example requires the `tweepy` library.
```shell
pip install tweepy
```
Get a Twitter API key and secret from [here](https://developer.x.com/en/docs/authentication/oauth-1-0a/api-key-and-secret).
```shell
export TWITTER_CONSUMER_KEY=***
export TWITTER_CONSUMER_SECRET=***
export TWITTER_ACCESS_TOKEN=***
export TWITTER_ACCESS_TOKEN_SECRET=***
export TWITTER_BEARER_TOKEN=***
```
## Example
The following agent will use Twitter to get information about a user, send a message to a user, and create a new tweet.
```python cookbook/tools/twitter_tools.py
from phi.agent import Agent
from phi.tools.twitter import TwitterTools
# Initialize the Twitter toolkit
twitter_tools = TwitterTools()
# Create an agent with the twitter toolkit
agent = Agent(
instructions=[
"Use your tools to interact with Twitter as the authorized user @phidatahq",
"When asked to create a tweet, generate appropriate content based on the request",
"Do not actually post tweets unless explicitly instructed to do so",
"Provide informative responses about the user's timeline and tweets",
"Respect Twitter's usage policies and rate limits",
],
tools=[twitter_tools],
show_tool_calls=True,
)
agent.print_response("Can you retrieve information about this user https://x.com/phidatahq ", markdown=True)
# Example usage: Reply To a Tweet
agent.print_response(
"Can you reply to this post as a general message as to how great this project is:https://x.com/phidatahq/status/1836101177500479547",
markdown=True,
)
# Example usage: Get your details
agent.print_response("Can you return my twitter profile?", markdown=True)
# Example usage: Send a direct message
agent.print_response(
"Can a send direct message to the user: https://x.com/phidatahq assking you want learn more about them and a link to their community?",
markdown=True,
)
# Example usage: Create a new tweet
agent.print_response("Create & post a tweet about the importance of AI ethics", markdown=True)
# Example usage: Get home timeline
agent.print_response("Get my timeline", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------------------- | ----- | ------- | ------------------------------------------------------ |
| `bearer_token` | `str` | `None` | The bearer token for Twitter API authentication |
| `consumer_key` | `str` | `None` | The consumer key for Twitter API authentication |
| `consumer_secret` | `str` | `None` | The consumer secret for Twitter API authentication |
| `access_token` | `str` | `None` | The access token for Twitter API authentication |
| `access_token_secret` | `str` | `None` | The access token secret for Twitter API authentication |
## Toolkit Functions
| Function | Description |
| ------------------- | ------------------------------------------- |
| `create_tweet` | Creates and posts a new tweet |
| `reply_to_tweet` | Replies to an existing tweet |
| `send_dm` | Sends a direct message to a Twitter user |
| `get_user_info` | Retrieves information about a Twitter user |
| `get_home_timeline` | Gets the authenticated user's home timeline |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/twitter.py)
# Website
Source: https://docs.phidata.com/tools/website
**WebsiteTools** enable an Agent to parse a website and add its contents to the knowledge base.
## Prerequisites
The following example requires the `beautifulsoup4` library.
```shell
pip install -U beautifulsoup4
```
## Example
The following agent will read the contents of a website and add it to the knowledge base.
```python cookbook/tools/website_tools.py
from phi.agent import Agent
from phi.tools.website import WebsiteTools
agent = Agent(tools=[WebsiteTools()], show_tool_calls=True)
agent.print_response("Search web page: 'https://docs.phidata.com/introduction'", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| ---------------- | ---------------------- | ------- | ---------------------------------------------------------------------------------------------------------------------- |
| `knowledge_base` | `WebsiteKnowledgeBase` | - | The knowledge base associated with the website, containing various data and resources linked to the website's content. |
## Toolkit Functions
| Function | Description |
| ------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `add_website_to_knowledge_base` | This function adds a website's content to the knowledge base. **NOTE:** The website must start with `https://` and should be a valid website. Use this function to get information about products from the internet. |
| `read_url` | This function reads a URL and returns the contents. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/website.py)
# Wikipedia
Source: https://docs.phidata.com/tools/wikipedia
**WikipediaTools** enable an Agent to search wikipedia a website and add its contents to the knowledge base.
## Prerequisites
The following example requires the `wikipedia` library.
```shell
pip install -U wikipedia
```
## Example
The following agent will run seach wikipedia for "ai" and print the response.
```python cookbook/tools/wikipedia_tools.py
from phi.agent import Agent
from phi.tools.wikipedia import WikipediaTools
agent = Agent(tools=[WikipediaTools()], show_tool_calls=True)
agent.print_response("Search wikipedia for 'ai'")
```
## Toolkit Params
| Name | Type | Default | Description |
| ---------------- | ------------------------ | ------- | ------------------------------------------------------------------------------------------------------------------ |
| `knowledge_base` | `WikipediaKnowledgeBase` | - | The knowledge base associated with Wikipedia, containing various data and resources linked to Wikipedia's content. |
## Toolkit Functions
| Function Name | Description |
| -------------------------------------------- | ------------------------------------------------------------------------------------------------------ |
| `search_wikipedia_and_update_knowledge_base` | This function searches wikipedia for a topic, adds the results to the knowledge base and returns them. |
| `search_wikipedia` | Searches Wikipedia for a query. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/wikipedia.py)
# Youtube
Source: https://docs.phidata.com/tools/youtube
**YouTubeTools** enable an Agent to access captions and metadata of YouTube videos, when provided with a video URL.
## Prerequisites
The following example requires the `youtube_transcript_api` library.
```shell
pip install -U youtube_transcript_api
```
## Example
The following agent will provide a summary of a YouTube video.
```python cookbook/tools/youtube_tools.py
from phi.agent import Agent
from phi.tools.youtube_tools import YouTubeTools
agent = Agent(
tools=[YouTubeTools()],
show_tool_calls=True,
description="You are a YouTube agent. Obtain the captions of a YouTube video and answer questions.",
)
agent.print_response("Summarize this video https://www.youtube.com/watch?v=Iv9dewmcFbs&t", markdown=True)
```
## Toolkit Params
| Param | Type | Default | Description |
| -------------------- | ----------- | ------- | ---------------------------------------------------------------------------------- |
| `get_video_captions` | `bool` | `True` | Enables the functionality to retrieve video captions. |
| `get_video_data` | `bool` | `True` | Enables the functionality to retrieve video metadata and other related data. |
| `languages` | `List[str]` | - | Specifies the list of languages for which data should be retrieved, if applicable. |
## Toolkit Functions
| Function | Description |
| ---------------------------- | -------------------------------------------------------- |
| `get_youtube_video_captions` | This function retrieves the captions of a YouTube video. |
| `get_youtube_video_data` | This function retrieves the metadata of a YouTube video. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/youtube_tools.py)
# Zendesk
Source: https://docs.phidata.com/tools/zendesk
**ZendeskTools** enable an Agent to access Zendesk API to search for articles.
## Prerequisites
The following example requires the `requests` library and auth credentials.
```shell
pip install -U requests
```
```shell
export ZENDESK_USERNAME=***
export ZENDESK_PW=***
export ZENDESK_COMPANY_NAME=***
```
## Example
The following agent will run seach Zendesk for "How do I login?" and print the response.
```python cookbook/tools/zendesk_tools.py
from phi.agent import Agent
from phi.tools.zendesk import ZendeskTools
agent = Agent(tools=[ZendeskTools()], show_tool_calls=True)
agent.print_response("How do I login?", markdown=True)
```
## Toolkit Params
| Parameter | Type | Default | Description |
| -------------- | ----- | ------- | ----------------------------------------------------------------------- |
| `username` | `str` | - | The username used for authentication or identification purposes. |
| `password` | `str` | - | The password associated with the username for authentication purposes. |
| `company_name` | `str` | - | The name of the company related to the user or the data being accessed. |
## Toolkit Functions
| Function | Description |
| ---------------- | ---------------------------------------------------------------------------------------------- |
| `search_zendesk` | This function searches for articles in Zendesk Help Center that match the given search string. |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/zendesk.py)
# Zoom
Source: https://docs.phidata.com/tools/zoom
## Example
The following agent will use Zoom to schedule a new meeting.
```python cookbook/tools/zoom_tools.py
import os
import time
import requests
from typing import Optional
from phi.utils.log import logger
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.tools.zoom import ZoomTool
# Get environment variables
ACCOUNT_ID = os.getenv("ZOOM_ACCOUNT_ID")
CLIENT_ID = os.getenv("ZOOM_CLIENT_ID")
CLIENT_SECRET = os.getenv("ZOOM_CLIENT_SECRET")
class CustomZoomTool(ZoomTool):
def __init__(
self,
account_id: Optional[str] = None,
client_id: Optional[str] = None,
client_secret: Optional[str] = None,
name: str = "zoom_tool",
):
super().__init__(account_id=account_id, client_id=client_id, client_secret=client_secret, name=name)
self.token_url = "https://zoom.us/oauth/token"
self.access_token = None
self.token_expires_at = 0
def get_access_token(self) -> str:
"""
Obtain or refresh the access token for Zoom API.
Returns:
A string containing the access token or an empty string if token retrieval fails.
"""
if self.access_token and time.time() < self.token_expires_at:
return str(self.access_token)
headers = {"Content-Type": "application/x-www-form-urlencoded"}
data = {"grant_type": "account_credentials", "account_id": self.account_id}
try:
response = requests.post(
self.token_url, headers=headers, data=data, auth=(self.client_id, self.client_secret)
)
response.raise_for_status()
token_info = response.json()
self.access_token = token_info["access_token"]
expires_in = token_info["expires_in"]
self.token_expires_at = time.time() + expires_in - 60
self._set_parent_token(str(self.access_token))
return str(self.access_token)
except requests.RequestException as e:
logger.error(f"Error fetching access token: {e}")
return ""
def _set_parent_token(self, token: str) -> None:
"""Helper method to set the token in the parent ZoomTool class"""
if token:
self._ZoomTool__access_token = token
zoom_tools = CustomZoomTool(account_id=ACCOUNT_ID, client_id=CLIENT_ID, client_secret=CLIENT_SECRET)
agent = Agent(
name="Zoom Meeting Manager",
agent_id="zoom-meeting-manager",
model=OpenAIChat(model="gpt-4"),
tools=[zoom_tools],
markdown=True,
debug_mode=True,
show_tool_calls=True,
instructions=[
"You are an expert at managing Zoom meetings using the Zoom API.",
"You can:",
"1. Schedule new meetings (schedule_meeting)",
"2. Get meeting details (get_meeting)",
"3. List all meetings (list_meetings)",
"4. Get upcoming meetings (get_upcoming_meetings)",
"5. Delete meetings (delete_meeting)",
"6. Get meeting recordings (get_meeting_recordings)",
"",
"For recordings, you can:",
"- Retrieve recordings for any past meeting using the meeting ID",
"- Include download tokens if needed",
"- Get recording details like duration, size, download link and file types",
"",
"Guidelines:",
"- Use ISO 8601 format for dates (e.g., '2024-12-28T10:00:00Z')",
"- Ensure meeting times are in the future",
"- Provide meeting details after scheduling (ID, URL, time)",
"- Handle errors gracefully",
"- Confirm successful operations",
],
)
agent.print_response("Schedule a meeting titled 'Team Sync' 8th december at 2 PM UTC for 45 minutes")
agent.print_response("delete a meeting titled 'Team Sync' which scheduled tomorrow at 2 PM UTC for 45 minutes")
agent.print_response("List all my scheduled meetings")
```
## Toolkit Params
| Parameter | Type | Default | Description |
| --------------- | ----- | ------------- | -------------------------------------- |
| `account_id` | `str` | `None` | The Zoom account ID for authentication |
| `client_id` | `str` | `None` | The client ID for authentication |
| `client_secret` | `str` | `None` | The client secret for authentication |
| `name` | `str` | `"zoom_tool"` | The name of the tool |
## Toolkit Functions
| Function | Description |
| ------------------ | ---------------------------- |
| `schedule_meeting` | Schedules a new Zoom meeting |
## Information
* View on [Github](https://github.com/agno-agi/phidata/blob/main/phi/tools/zoom.py)
# ChromaDB Agent Knowledge
Source: https://docs.phidata.com/vectordb/chroma
## Setup
```shell
pip install chromadb
```
## Example
```python agent_with_knowledge.py
import typer
from rich.prompt import Prompt
from typing import Optional
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.chroma import ChromaDb
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=ChromaDb(collection="recipes"),
)
# Comment out after first run
knowledge_base.load(recreate=False)
def pdf_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge_base=knowledge_base,
use_tools=True,
show_tool_calls=True,
debug_mode=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if __name__ == "__main__":
typer.run(pdf_agent)
```
## ChromaDb Params
# Introduction
Source: https://docs.phidata.com/vectordb/introduction
Vector databases enable us to store information as embeddings and search for "results similar" to our input query using cosine similarity or full text search. These results are then provided to the Agent as context so it can respond in a context-aware manner using Retrieval Augmented Generation (**RAG**).
Here's how vector databases are used with Agents:
Break down the knowledge into smaller chunks to ensure our search query returns only relevant results.
Convert the chunks into embedding vectors and store them in a vector database.
When the user sends a message, we convert the input message into an embedding and "search" for nearest neighbors in the vector database.
Many vector databases also support hybrid search, which combines the power of vector similarity search with traditional keyword-based search. This approach can significantly improve the relevance and accuracy of search results, especially for complex queries or when dealing with diverse types of data.
Hybrid search typically works by:
1. Performing a vector similarity search to find semantically similar content.
2. Conducting a keyword-based search to identify exact or close matches.
3. Combining the results using a weighted approach to provide the most relevant information.
This capability allows for more flexible and powerful querying, often yielding better results than either method alone.
The following VectorDb are currently supported:
* [PgVector](/vectordb/pgvector)\*
* [LanceDb](/vectordb/lancedb)\*
* [Pinecone](/vectordb/pinecone)\*
* [Qdrant](/vectordb/qdrant)
\*hybrid search supported
Each of these databases has its own strengths and features, including varying levels of support for hybrid search. Be sure to check the specific documentation for each to understand how to best leverage their capabilities in your projects.
# LanceDB Agent Knowledge
Source: https://docs.phidata.com/vectordb/lancedb
## Setup
```shell
pip install lancedb
```
## Example
```python agent_with_knowledge.py
import typer
from typing import Optional
from rich.prompt import Prompt
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.lancedb import LanceDb
from phi.vectordb.search import SearchType
# LanceDB Vector DB
vector_db = LanceDb(
table_name="recipes",
uri="/tmp/lancedb",
search_type=SearchType.keyword,
)
# Knowledge Base
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=vector_db,
)
# Comment out after first run
knowledge_base.load(recreate=True)
def lancedb_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge=knowledge_base,
show_tool_calls=True,
debug_mode=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if __name__ == "__main__":
typer.run(lancedb_agent)
```
## LanceDb Params
# PgVector Agent Knowledge
Source: https://docs.phidata.com/vectordb/pgvector
## Setup
```shell
docker run -d \
-e POSTGRES_DB=ai \
-e POSTGRES_USER=ai \
-e POSTGRES_PASSWORD=ai \
-e PGDATA=/var/lib/postgresql/data/pgdata \
-v pgvolume:/var/lib/postgresql/data \
-p 5532:5432 \
--name pgvector \
phidata/pgvector:16
```
## Example
```python agent_with_knowledge.py
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pgvector import PgVector, SearchType
db_url = "postgresql+psycopg://ai:ai@localhost:5532/ai"
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=PgVector(table_name="recipes", db_url=db_url, search_type=SearchType.hybrid),
)
# Load the knowledge base: Comment out after first run
knowledge_base.load(recreate=True, upsert=True)
agent = Agent(
model=OpenAIChat(id="gpt-4o"),
knowledge=knowledge_base,
# Add a tool to read chat history.
read_chat_history=True,
show_tool_calls=True,
markdown=True,
# debug_mode=True,
)
agent.print_response("How do I make chicken and galangal in coconut milk soup", stream=True)
agent.print_response("What was my last question?", stream=True)
```
## PgVector Params
# Pinecone Agent Knowledge
Source: https://docs.phidata.com/vectordb/pinecone
## Setup
Follow the instructions in the [Pinecone Setup Guide](https://docs.pinecone.io/guides/get-started/quickstart) to get started quickly with Pinecone.
## Example
```python agent_with_knowledge.py
import os
import typer
from typing import Optional
from rich.prompt import Prompt
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.pineconedb import PineconeDB
api_key = os.getenv("PINECONE_API_KEY")
index_name = "thai-recipe-hybrid-search"
vector_db = PineconeDB(
name=index_name,
dimension=1536,
metric="cosine",
spec={"serverless": {"cloud": "aws", "region": "us-east-1"}},
api_key=api_key,
use_hybrid_search=True,
hybrid_alpha=0.5,
)
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=vector_db,
)
# Comment out after first run
knowledge_base.load(recreate=True, upsert=True)
def pinecone_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge=knowledge_base,
show_tool_calls=True,
debug_mode=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if __name__ == "__main__":
typer.run(pinecone_agent)
```
## PineconeDB Params
# Qdrant Agent Knowledge
Source: https://docs.phidata.com/vectordb/qdrant
## Setup
Follow the instructions in the [Qdrant Setup Guide](https://qdrant.tech/documentation/guides/installation/) to install Qdrant locally. Here is a guide to get API keys: [Qdrant API Keys](https://qdrant.tech/documentation/cloud/authentication/).
## Example
```python agent_with_knowledge.py
import os
import typer
from typing import Optional
from rich.prompt import Prompt
from phi.agent import Agent
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.qdrant import Qdrant
api_key = os.getenv("QDRANT_API_KEY")
qdrant_url = os.getenv("QDRANT_URL")
collection_name = "thai-recipe-index"
vector_db = Qdrant(
collection=collection_name,
url=qdrant_url,
api_key=api_key,
)
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=vector_db,
)
# Comment out after first run
knowledge_base.load(recreate=True, upsert=True)
def qdrant_agent(user: str = "user"):
run_id: Optional[str] = None
agent = Agent(
run_id=run_id,
user_id=user,
knowledge=knowledge_base,
tool_calls=True,
use_tools=True,
show_tool_calls=True,
debug_mode=True,
)
if run_id is None:
run_id = agent.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
message = Prompt.ask(f"[bold] :sunglasses: {user} [/bold]")
if message in ("exit", "bye"):
break
agent.print_response(message)
if __name__ == "__main__":
typer.run(qdrant_agent)
```
## Qdrant Params
# SingleStore Agent Knowledge
Source: https://docs.phidata.com/vectordb/singlestore
## Setup
Follow the instructions in the [SingleStore Setup Guide](https://docs.singlestore.com/cloud/connect-to-singlestore/connect-with-mysql/connect-with-mysql-client/connect-to-singlestore-helios-using-tls-ssl/) to install SingleStore locally.
## Example
```python agent_with_knowledge.py
import typer
from typing import Optional
from os import getenv
from sqlalchemy.engine import create_engine
from phi.assistant import Assistant
from phi.knowledge.pdf import PDFUrlKnowledgeBase
from phi.vectordb.singlestore import S2VectorDb
USERNAME = getenv("SINGLESTORE_USERNAME")
PASSWORD = getenv("SINGLESTORE_PASSWORD")
HOST = getenv("SINGLESTORE_HOST")
PORT = getenv("SINGLESTORE_PORT")
DATABASE = getenv("SINGLESTORE_DATABASE")
SSL_CERT = getenv("SINGLESTORE_SSL_CERT", None)
db_url = f"mysql+pymysql://{USERNAME}:{PASSWORD}@{HOST}:{PORT}/{DATABASE}?charset=utf8mb4"
if SSL_CERT:
db_url += f"&ssl_ca={SSL_CERT}&ssl_verify_cert=true"
db_engine = create_engine(db_url)
knowledge_base = PDFUrlKnowledgeBase(
urls=["https://phi-public.s3.amazonaws.com/recipes/ThaiRecipes.pdf"],
vector_db=S2VectorDb(
collection="recipes",
db_engine=db_engine,
schema=DATABASE,
),
)
# Comment out after first run
knowledge_base.load(recreate=False)
def pdf_assistant(user: str = "user"):
run_id: Optional[str] = None
assistant = Assistant(
run_id=run_id,
user_id=user,
knowledge_base=knowledge_base,
use_tools=True,
show_tool_calls=True,
# Uncomment the following line to use traditional RAG
# add_references_to_prompt=True,
)
if run_id is None:
run_id = assistant.run_id
print(f"Started Run: {run_id}\n")
else:
print(f"Continuing Run: {run_id}\n")
while True:
assistant.cli_app(markdown=True)
if __name__ == "__main__":
typer.run(pdf_assistant)
```
## SingleStore Params
# Workflows
Source: https://docs.phidata.com/workflows
Workflows are deterministic, stateful, multi-agent programs that are built for production applications. They're incredibly powerful and offer the following benefits:
* **Full control and flexibility**: You have full control over the multi-agent process, how the input is processed, which agents are used and in what order. This is critical for reliability.
* **Pure python**: Control the agent process using standard python. Having built 100s of AI products, no framework will give you the flexibility of pure-python.
* **Built-in state management and caching**: Store state and cache intermediate results in a database, enabling your agents to re-use results from previous executions.
How to build a workflow:
1. Define your workflow as a class by inheriting from the `Workflow` class.
2. Add one or more agents to the workflow.
3. Implement your logic in the `run()` method.
4. Cache results in the `session_state` as needed.
5. Run the workflow using the `.run()` method.
## Example: Blog Post Generator
Let's create a blog post generator that can search the web, read the top links and write a blog post for us. We'll cache intermediate results in the database to improve performance.
### Create the Workflow
Create a file `blog_post_generator.py`
```python blog_post_generator.py
import json
from typing import Optional, Iterator
from pydantic import BaseModel, Field
from phi.agent import Agent
from phi.model.openai import OpenAIChat
from phi.workflow import Workflow, RunResponse, RunEvent
from phi.storage.workflow.sqlite import SqlWorkflowStorage
from phi.tools.duckduckgo import DuckDuckGo
from phi.utils.pprint import pprint_run_response
from phi.utils.log import logger
class NewsArticle(BaseModel):
title: str = Field(..., description="Title of the article.")
url: str = Field(..., description="Link to the article.")
summary: Optional[str] = Field(..., description="Summary of the article if available.")
class SearchResults(BaseModel):
articles: list[NewsArticle]
class BlogPostGenerator(Workflow):
# Define an Agent that will search the web for a topic
searcher: Agent = Agent(
model=OpenAIChat(id="gpt-4o-mini"),
tools=[DuckDuckGo()],
instructions=["Given a topic, search for the top 5 articles."],
response_model=SearchResults,
structured_outputs=True,
)
# Define an Agent that will write the blog post
writer: Agent = Agent(
model=OpenAIChat(id="gpt-4o"),
instructions=[
"You will be provided with a topic and a list of top articles on that topic.",
"Carefully read each article and generate a New York Times worthy blog post on that topic.",
"Break the blog post into sections and provide key takeaways at the end.",
"Make sure the title is catchy and engaging.",
"Always provide sources, do not make up information or sources.",
],
markdown=True,
)
def run(self, topic: str, use_cache: bool = True) -> Iterator[RunResponse]:
"""This is where the main logic of the workflow is implemented."""
logger.info(f"Generating a blog post on: {topic}")
# Step 1: Use the cached blog post if use_cache is True
if use_cache:
cached_blog_post = self.get_cached_blog_post(topic)
if cached_blog_post:
yield RunResponse(content=cached_blog_post, event=RunEvent.workflow_completed)
return
# Step 2: Search the web for articles on the topic
search_results: Optional[SearchResults] = self.get_search_results(topic)
# If no search_results are found for the topic, end the workflow
if search_results is None or len(search_results.articles) == 0:
yield RunResponse(
event=RunEvent.workflow_completed,
content=f"Sorry, could not find any articles on the topic: {topic}",
)
return
# Step 3: Write a blog post
yield from self.write_blog_post(topic, search_results)
def get_cached_blog_post(self, topic: str) -> Optional[str]:
"""Get the cached blog post for a topic."""
logger.info("Checking if cached blog post exists")
return self.session_state.get("blog_posts", {}).get(topic)
def add_blog_post_to_cache(self, topic: str, blog_post: Optional[str]):
"""Add a blog post to the cache."""
logger.info(f"Saving blog post for topic: {topic}")
self.session_state.setdefault("blog_posts", {})
self.session_state["blog_posts"][topic] = blog_post
def get_search_results(self, topic: str) -> Optional[SearchResults]:
"""Get the search results for a topic."""
MAX_ATTEMPTS = 3
for attempt in range(MAX_ATTEMPTS):
try:
searcher_response: RunResponse = self.searcher.run(topic)
# Check if we got a valid response
if not searcher_response or not searcher_response.content:
logger.warning(f"Attempt {attempt + 1}/{MAX_ATTEMPTS}: Empty searcher response")
continue
# Check if the response is of the expected SearchResults type
if not isinstance(searcher_response.content, SearchResults):
logger.warning(f"Attempt {attempt + 1}/{MAX_ATTEMPTS}: Invalid response type")
continue
article_count = len(searcher_response.content.articles)
logger.info(f"Found {article_count} articles on attempt {attempt + 1}")
return searcher_response.content
except Exception as e:
logger.warning(f"Attempt {attempt + 1}/{MAX_ATTEMPTS} failed: {str(e)}")
logger.error(f"Failed to get search results after {MAX_ATTEMPTS} attempts")
return None
def write_blog_post(self, topic: str, search_results: SearchResults) -> Iterator[RunResponse]:
"""Write a blog post on a topic."""
logger.info("Writing blog post")
# Prepare the input for the writer
writer_input = {"topic": topic, "articles": [v.model_dump() for v in search_results.articles]}
# Run the writer and yield the response
yield from self.writer.run(json.dumps(writer_input, indent=4), stream=True)
# Save the blog post in the cache
self.add_blog_post_to_cache(topic, self.writer.run_response.content)
# Run the workflow if the script is executed directly
if __name__ == "__main__":
from rich.prompt import Prompt
# Get topic from user
topic = Prompt.ask(
"[bold]Enter a blog post topic[/bold]\n✨",
default="Why Cats Secretly Run the Internet",
)
# Convert the topic to a URL-safe string for use in session_id
url_safe_topic = topic.lower().replace(" ", "-")
# Initialize the blog post generator workflow
# - Creates a unique session ID based on the topic
# - Sets up SQLite storage for caching results
generate_blog_post = BlogPostGenerator(
session_id=f"generate-blog-post-on-{url_safe_topic}",
storage=SqlWorkflowStorage(
table_name="generate_blog_post_workflows",
db_file="tmp/workflows.db",
),
)
# Execute the workflow with caching enabled
# Returns an iterator of RunResponse objects containing the generated content
blog_post: Iterator[RunResponse] = generate_blog_post.run(topic=topic, use_cache=True)
# Print the response
pprint_run_response(blog_post, markdown=True)
```
### Run the workflow
Install libraries
```shell
pip install phidata openai duckduckgo-search sqlalchemy
```
Run the workflow
```shell
python blog_post_generator.py
```
Now the results are cached in the database and can be re-used for future runs. Run the workflow again to view the cached results.
```shell
python blog_post_generator.py
```
 # Introduction
Source: https://docs.phidata.com/workflows/introduction
Workflows are deterministic, stateful, multi-agent pipelines that power many of our production use cases. They are incredibly powerful and offer the following benefits:
* **Control and Flexibility**: You have full control over the multi-agent process, how the input is processed, which agents are used and in what order.
* **Built-in Memory**: You can store state and cache results in a database at any time, meaning your agents can re-use results from previous steps.
* **Defined as a python class**: You do not need to learn a new framework, its just python.
How to build a workflow:
1. Define your workflow as a class by inheriting from the `Workflow` class
2. Add one or more agents to the workflow
3. Implement your logic in the `run()` method
4. Cache results in the `session_state` as needed
5. Run the workflow using the `.run()` method
## Example: Blog Post Generator
Let's create a blog post generator that can search the web, read the top links and write a blog post for us. We'll cache intermediate results in the database to improve performance.
### Create the Workflow
Create a file `blog_post_generator.py`
```python blog_post_generator.py
import json
from typing import Optional, Iterator
from pydantic import BaseModel, Field
from phi.agent import Agent
from phi.workflow import Workflow, RunResponse, RunEvent
from phi.storage.workflow.sqlite import SqlWorkflowStorage
from phi.tools.duckduckgo import DuckDuckGo
from phi.utils.pprint import pprint_run_response
from phi.utils.log import logger
class NewsArticle(BaseModel):
title: str = Field(..., description="Title of the article.")
url: str = Field(..., description="Link to the article.")
summary: Optional[str] = Field(..., description="Summary of the article if available.")
class SearchResults(BaseModel):
articles: list[NewsArticle]
class BlogPostGenerator(Workflow):
searcher: Agent = Agent(
tools=[DuckDuckGo()],
instructions=["Given a topic, search for 20 articles and return the 5 most relevant articles."],
response_model=SearchResults,
)
writer: Agent = Agent(
instructions=[
"You will be provided with a topic and a list of top articles on that topic.",
"Carefully read each article and generate a New York Times worthy blog post on that topic.",
"Break the blog post into sections and provide key takeaways at the end.",
"Make sure the title is catchy and engaging.",
"Always provide sources, do not make up information or sources.",
],
)
def run(self, topic: str, use_cache: bool = True) -> Iterator[RunResponse]:
logger.info(f"Generating a blog post on: {topic}")
# Use the cached blog post if use_cache is True
if use_cache and "blog_posts" in self.session_state:
logger.info("Checking if cached blog post exists")
for cached_blog_post in self.session_state["blog_posts"]:
if cached_blog_post["topic"] == topic:
logger.info("Found cached blog post")
yield RunResponse(
run_id=self.run_id,
event=RunEvent.workflow_completed,
content=cached_blog_post["blog_post"],
)
return
# Step 1: Search the web for articles on the topic
num_tries = 0
search_results: Optional[SearchResults] = None
# Run until we get a valid search results
while search_results is None and num_tries < 3:
try:
num_tries += 1
searcher_response: RunResponse = self.searcher.run(topic)
if (
searcher_response
and searcher_response.content
and isinstance(searcher_response.content, SearchResults)
):
logger.info(f"Searcher found {len(searcher_response.content.articles)} articles.")
search_results = searcher_response.content
else:
logger.warning("Searcher response invalid, trying again...")
except Exception as e:
logger.warning(f"Error running searcher: {e}")
# If no search_results are found for the topic, end the workflow
if search_results is None or len(search_results.articles) == 0:
yield RunResponse(
run_id=self.run_id,
event=RunEvent.workflow_completed,
content=f"Sorry, could not find any articles on the topic: {topic}",
)
return
# Step 2: Write a blog post
logger.info("Writing blog post")
# Prepare the input for the writer
writer_input = {
"topic": topic,
"articles": [v.model_dump() for v in search_results.articles],
}
# Run the writer and yield the response
yield from self.writer.run(json.dumps(writer_input, indent=4), stream=True)
# Save the blog post in the session state for future runs
if "blog_posts" not in self.session_state:
self.session_state["blog_posts"] = []
self.session_state["blog_posts"].append({"topic": topic, "blog_post": self.writer.run_response.content})
# The topic to generate a blog post on
topic = "US Elections 2024"
# Create the workflow
generate_blog_post = BlogPostGenerator(
session_id=f"generate-blog-post-on-{topic}",
storage=SqlWorkflowStorage(
table_name="generate_blog_post_workflows",
db_file="tmp/workflows.db",
),
)
# Run workflow
blog_post: Iterator[RunResponse] = generate_blog_post.run(topic=topic, use_cache=True)
# Print the response
pprint_run_response(blog_post, markdown=True)
```
### Run the workflow
Install libraries
```shell
pip install phidata openai duckduckgo-search sqlalchemy phidata
```
Run the workflow
```shell
python blog_post_generator.py
```
Now the results are cached in the database and can be re-used for future runs. Run the workflow again to view the cached results.
```shell
python blog_post_generator.py
```
# Advanced Example - News Report Generator
Source: https://docs.phidata.com/workflows/news-report-generator
Let's work through a slightly more complex example of a news report generator. We want full control over the workflow, including the ability to stream the output. We also want to cache the results of the web search and the scrape.
In this workflow, we will generate a comprehensive news report on a given topic.
1. First we will search the web for articles on the topic:
* Use cached search results if available and use\_search\_cache is True.
* Otherwise, perform a new web search.
2. Next we will scrape the content of each article:
* Use cached scraped articles if available and use\_scrape\_cache is True.
* Scrape new articles that aren't in the cache.
3. Finally we will generate the final report using the scraped article contents.
The caching mechanism is implemented using the `session_state` which is a dictionary that is persisted across workflow runs. This really helps with performance and cost.
## Full Code
```python news_report_generator.py
import json
from textwrap import dedent
from typing import Optional, Dict, Iterator
from pydantic import BaseModel, Field
from phi.agent import Agent
from phi.workflow import Workflow, RunResponse, RunEvent
from phi.storage.workflow.sqlite import SqlWorkflowStorage
from phi.tools.duckduckgo import DuckDuckGo
from phi.tools.newspaper4k import Newspaper4k
from phi.utils.pprint import pprint_run_response
from phi.utils.log import logger
class NewsArticle(BaseModel):
title: str = Field(..., description="Title of the article.")
url: str = Field(..., description="Link to the article.")
summary: Optional[str] = Field(..., description="Summary of the article if available.")
class SearchResults(BaseModel):
articles: list[NewsArticle]
class ScrapedArticle(BaseModel):
title: str = Field(..., description="Title of the article.")
url: str = Field(..., description="Link to the article.")
summary: Optional[str] = Field(..., description="Summary of the article if available.")
content: Optional[str] = Field(
...,
description="Content of the in markdown format if available. Return None if the content is not available or does not make sense.",
)
class GenerateNewsReport(Workflow):
web_searcher: Agent = Agent(
tools=[DuckDuckGo()],
instructions=[
"Given a topic, search for 10 articles and return the 5 most relevant articles.",
],
response_model=SearchResults,
)
article_scraper: Agent = Agent(
tools=[Newspaper4k()],
instructions=[
"Given a url, scrape the article and return the title, url, and markdown formatted content.",
"If the content is not available or does not make sense, return None as the content.",
],
response_model=ScrapedArticle,
)
writer: Agent = Agent(
description="You are a Senior NYT Editor and your task is to write a new york times worthy cover story.",
instructions=[
"You will be provided with news articles and their contents.",
"Carefully **read** each article and **think** about the contents",
"Then generate a final New York Times worthy article in the provided below.",
"Break the article into sections and provide key takeaways at the end.",
"Make sure the title is catchy and engaging.",
"Always provide sources for the article, do not make up information or sources.",
"REMEMBER: you are writing for the New York Times, so the quality of the article is important.",
],
expected_output=dedent("""\
An engaging, informative, and well-structured article in the following format:
## Engaging Article Title
### {Overview or Introduction}
{give a brief introduction of the article and why the user should read this report}
{make this section engaging and create a hook for the reader}
### {Section title}
{break the article into sections}
{provide details/facts/processes in this section}
... more sections as necessary...
### Key Takeaways
{provide key takeaways from the article}
### Sources
- [Title](url)
- [Title](url)
- [Title](url)
"""),
)
def run(
self, topic: str, use_search_cache: bool = True, use_scrape_cache: bool = True, use_cached_report: bool = False
) -> Iterator[RunResponse]:
"""
Generate a comprehensive news report on a given topic.
This function orchestrates a workflow to search for articles, scrape their content,
and generate a final report. It utilizes caching mechanisms to optimize performance.
Args:
topic (str): The topic for which to generate the news report.
use_search_cache (bool, optional): Whether to use cached search results. Defaults to True.
use_scrape_cache (bool, optional): Whether to use cached scraped articles. Defaults to True.
use_cached_report (bool, optional): Whether to return a previously generated report on the same topic. Defaults to False.
Returns:
Iterator[RunResponse]: An stream of objects containing the generated report or status information.
Workflow Steps:
1. Check for a cached report if use_cached_report is True.
2. Search the web for articles on the topic:
- Use cached search results if available and use_search_cache is True.
- Otherwise, perform a new web search.
3. Scrape the content of each article:
- Use cached scraped articles if available and use_scrape_cache is True.
- Scrape new articles that aren't in the cache.
4. Generate the final report using the scraped article contents.
The function utilizes the `session_state` to store and retrieve cached data.
"""
logger.info(f"Generating a report on: {topic}")
# Use the cached report if use_cached_report is True
if use_cached_report and "reports" in self.session_state:
logger.info("Checking if cached report exists")
for cached_report in self.session_state["reports"]:
if cached_report["topic"] == topic:
yield RunResponse(
run_id=self.run_id,
event=RunEvent.workflow_completed,
content=cached_report["report"],
)
return
####################################################
# Step 1: Search the web for articles on the topic
####################################################
# 1.1: Get cached search_results from the session state if use_search_cache is True
search_results: Optional[SearchResults] = None
try:
if use_search_cache and "search_results" in self.session_state:
search_results = SearchResults.model_validate(self.session_state["search_results"])
logger.info(f"Found {len(search_results.articles)} articles in cache.")
except Exception as e:
logger.warning(f"Could not read search results from cache: {e}")
# 1.2: If there are no cached search_results, ask the web_searcher to find the latest articles
if search_results is None:
web_searcher_response: RunResponse = self.web_searcher.run(topic)
if (
web_searcher_response
and web_searcher_response.content
and isinstance(web_searcher_response.content, SearchResults)
):
logger.info(f"WebSearcher identified {len(web_searcher_response.content.articles)} articles.")
search_results = web_searcher_response.content
# Save the search_results in the session state
self.session_state["search_results"] = search_results.model_dump()
# 1.3: If no search_results are found for the topic, end the workflow
if search_results is None or len(search_results.articles) == 0:
yield RunResponse(
run_id=self.run_id,
event=RunEvent.workflow_completed,
content=f"Sorry, could not find any articles on the topic: {topic}",
)
return
####################################################
# Step 2: Scrape each article
####################################################
# 2.1: Get cached scraped_articles from the session state if use_scrape_cache is True
scraped_articles: Dict[str, ScrapedArticle] = {}
if (
use_scrape_cache
and "scraped_articles" in self.session_state
and isinstance(self.session_state["scraped_articles"], dict)
):
for url, scraped_article in self.session_state["scraped_articles"].items():
try:
validated_scraped_article = ScrapedArticle.model_validate(scraped_article)
scraped_articles[validated_scraped_article.url] = validated_scraped_article
except Exception as e:
logger.warning(f"Could not read scraped article from cache: {e}")
logger.info(f"Found {len(scraped_articles)} scraped articles in cache.")
# 2.2: Scrape the articles that are not in the cache
for article in search_results.articles:
if article.url in scraped_articles:
logger.info(f"Found scraped article in cache: {article.url}")
continue
article_scraper_response: RunResponse = self.article_scraper.run(article.url)
if (
article_scraper_response
and article_scraper_response.content
and isinstance(article_scraper_response.content, ScrapedArticle)
):
scraped_articles[article_scraper_response.content.url] = article_scraper_response.content.model_dump()
logger.info(f"Scraped article: {article_scraper_response.content.url}")
# 2.3: Save the scraped_articles in the session state
self.session_state["scraped_articles"] = {k: v for k, v in scraped_articles.items()}
####################################################
# Step 3: Write a report
####################################################
# 3.1: Generate the final report
logger.info("Generating final report")
writer_input = {
"topic": topic,
"articles": [v.model_dump() for v in scraped_articles.values()],
}
yield from self.writer.run(json.dumps(writer_input, indent=4), stream=True)
# 3.2: Save the writer_response in the session state
if "reports" not in self.session_state:
self.session_state["reports"] = []
self.session_state["reports"].append({"topic": topic, "report": self.writer.run_response.content})
# The topic to generate a report on
topic = "IBM Hashicorp Acquisition"
# Instantiate the workflow
generate_news_report = GenerateNewsReport(
session_id=f"generate-report-on-{topic}",
storage=SqlWorkflowStorage(
table_name="generate_news_report_workflows",
db_file="tmp/workflows.db",
),
)
# Run workflow
report_stream: Iterator[RunResponse] = generate_news_report.run(
topic=topic, use_search_cache=True, use_scrape_cache=True, use_cached_report=False
)
# Print the response
pprint_run_response(report_stream, markdown=True)
```
## Run the workflow
Install dependencies
```shell
pip install openai duckduckgo-search newspaper4k lxml_html_clean phidata
```
Run the workflow
```shell
python news_report_generator.py
```
Test if the results are cached, run the workflow again with the same parameters.
```shell
python news_report_generator.py
```
## Video
Checkout the recording of the workflow running and see how the results are cached in the 2nd run.
# Session State
Source: https://docs.phidata.com/workflows/session-state
**Use the `session_state` to cache intermediate results in a database.**
All Workflows come with a `session_state` dictionary that you can use to cache intermediate results. Provide your workflows with `storage` and a `session_id` to enable caching.
For example, you can use the `SqlWorkflowStorage` to cache results in a Sqlite database.
```python
# Create the workflow
generate_blog_post = BlogPostGenerator(
session_id="my-session-id",
storage=SqlWorkflowStorage(
table_name="generate_blog_post_workflows",
db_file="tmp/workflows.db",
),
)
```
Then in the `run()` method, you can read from and add to the `session_state` as needed.
```python
class BlogPostGenerator(Workflow):
# ... agents
def run(self, topic: str, use_cache: bool = True) -> Iterator[RunResponse]:
# Read from the session state cache
if use_cache and "blog_posts" in self.session_state:
logger.info("Checking if cached blog post exists")
for cached_blog_post in self.session_state["blog_posts"]:
if cached_blog_post["topic"] == topic:
logger.info("Found cached blog post")
yield RunResponse(
run_id=self.run_id,
event=RunEvent.workflow_completed,
content=cached_blog_post["blog_post"],
)
return
# ... generate the blog post
# Save to session state for future runs
if "blog_posts" not in self.session_state:
self.session_state["blog_posts"] = []
self.session_state["blog_posts"].append({"topic": topic, "blog_post": self.writer.run_response.content})
```
When the workflow starts, the `session_state` for that particular `session_id` is read from the database and when the workflow ends, the `session_state` is stored in the database.
You can always call `self.write_to_storage()` to save the `session_state` to the database at any time. Incase you need to abort the workflow but want to store the intermediate results.
View the [Blog Post Generator](/workflows/introduction#full-example-blog-post-generator) for an example of how to use session state for caching.
# Streaming
Source: https://docs.phidata.com/workflows/streaming
Workflows are all about control and flexibility. You have full control over the multi-agent process, how the input is processed, which agents are used and in what order.
You also have full control over how the output is streamed.
## Streaming
To stream the output, yield an `Iterator[RunResponse]` from the `run()` method of your workflow.
```python news_report_generator.py
# Define the workflow
class GenerateNewsReport(Workflow):
agent_1: Agent = ...
agent_2: Agent = ...
agent_3: Agent = ...
def run(self, ...) -> Iterator[RunResponse]:
# Run agents and gather the response
# These can be batch responses, you can also stream intermediate results if you want
final_agent_input = ...
# Generate the final response from the writer agent
agent_3_response_stream: Iterator[RunResponse] = self.agent_3.run(final_agent_input, stream=True)
# Yield the response
yield agent_3_response_stream
# Instantiate the workflow
generate_news_report = GenerateNewsReport()
# Run workflow and get the response as an iterator of RunResponse objects
report_stream: Iterator[RunResponse] = generate_news_report.run(...)
# Print the response
pprint_run_response(report_stream, markdown=True)
```
## Batch
Simply return a `RunResponse` object from the `run()` method of your workflow to return a single output.
```python news_report_generator.py
# Define the workflow
class GenerateNewsReport(Workflow):
agent_1: Agent = ...
agent_2: Agent = ...
agent_3: Agent = ...
def run(self, ...) -> RunResponse:
# Run agents and gather the response
final_agent_input = ...
# Generate the final response from the writer agent
agent_3_response: RunResponse = self.agent_3.run(final_agent_input)
# Return the response
return agent_3_response
# Instantiate the workflow
generate_news_report = GenerateNewsReport()
# Run workflow and get the response as a RunResponse object
report: RunResponse = generate_news_report.run(...)
# Print the response
pprint_run_response(report, markdown=True)
```